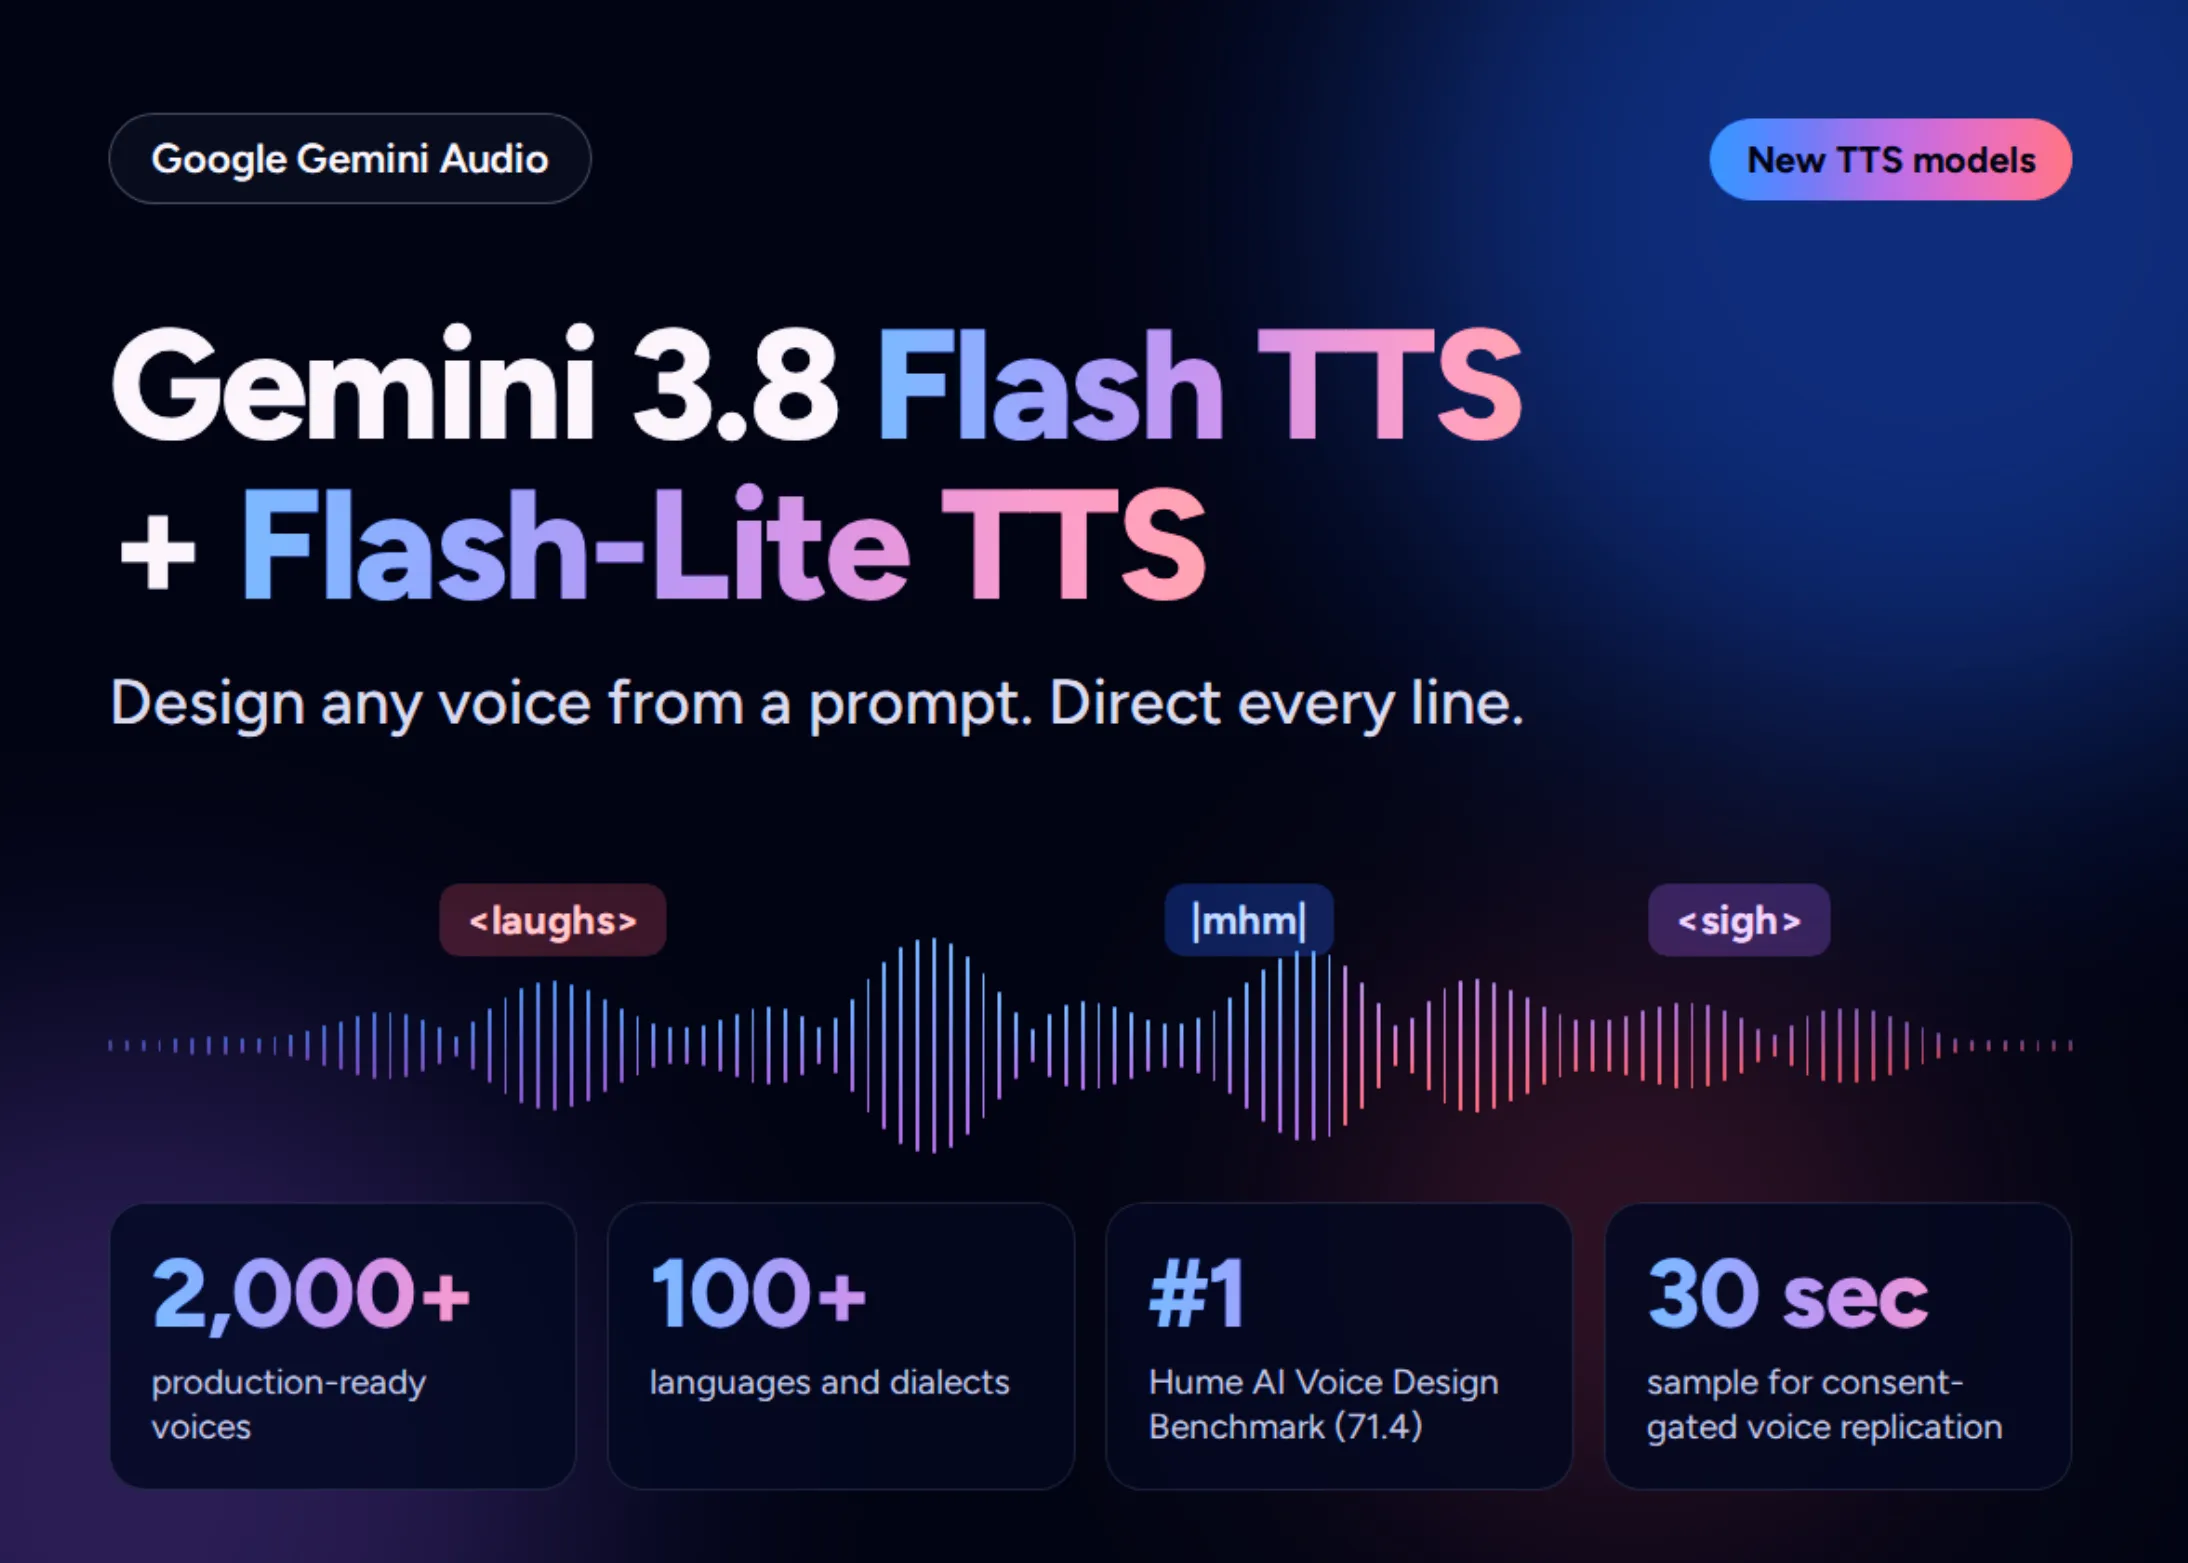
Google has released Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, 2 new text-to-speech models in its Gemini Audio […]
Category: Voice AI
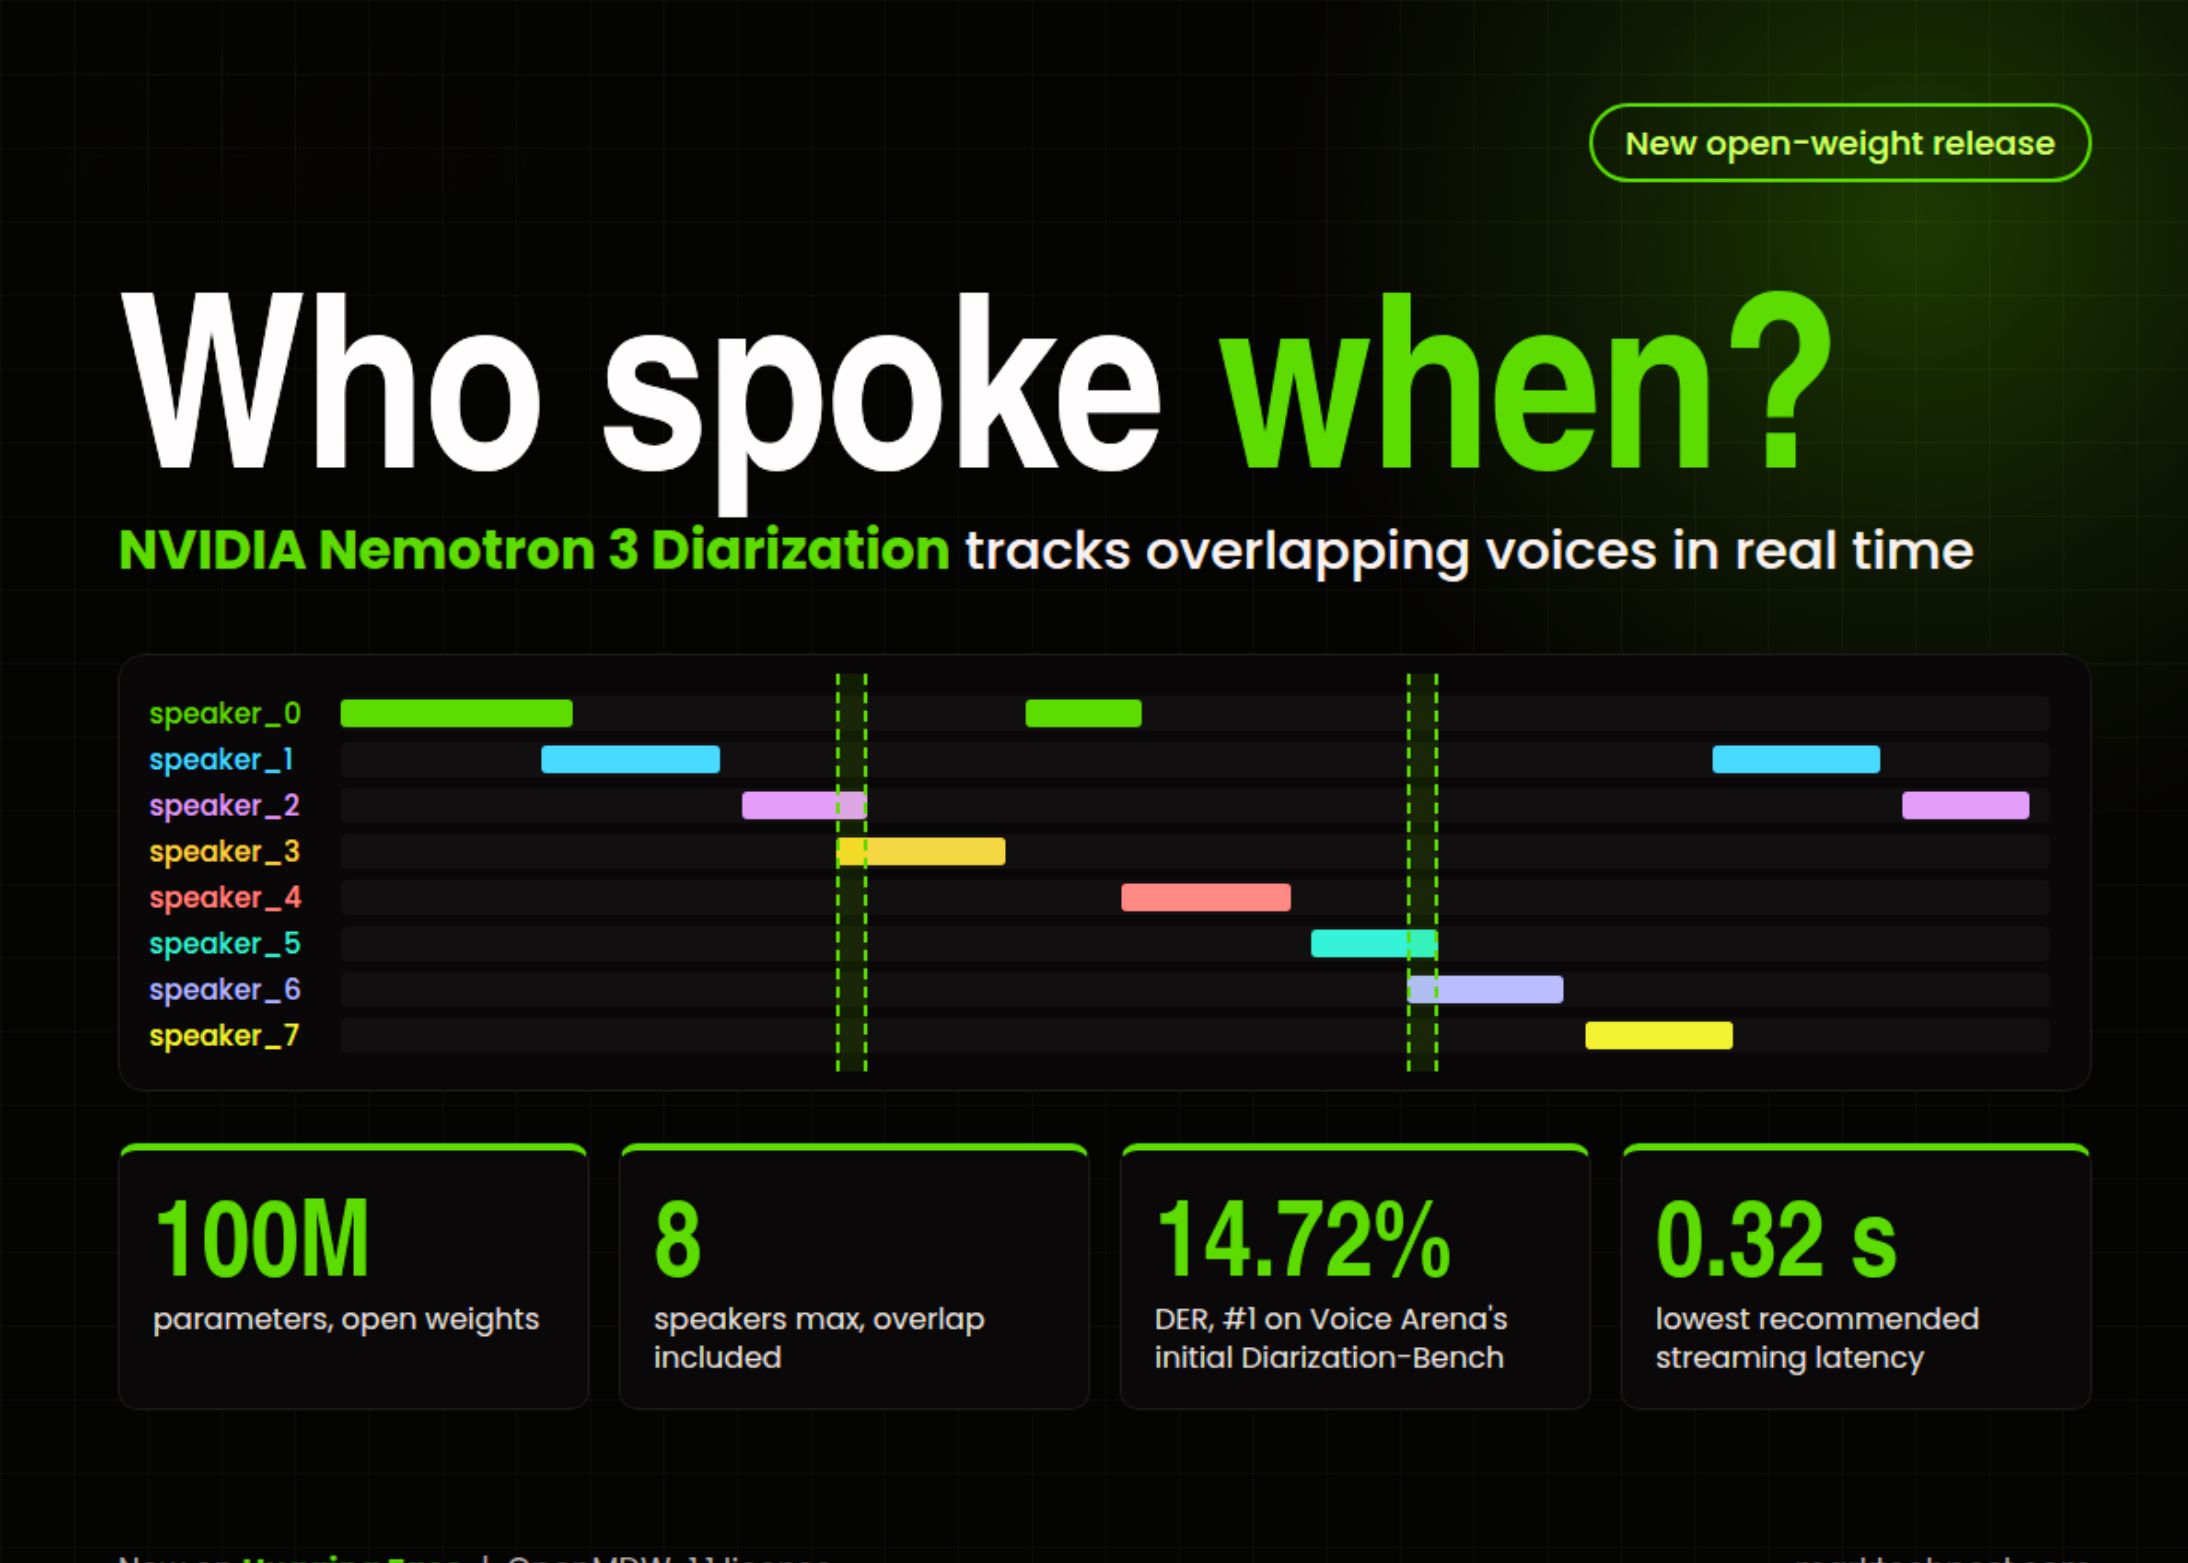
NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time
NVIDIA has released Nemotron 3 Diarization, an open-weight speaker diarization model on Hugging Face. It answers one question about any […]
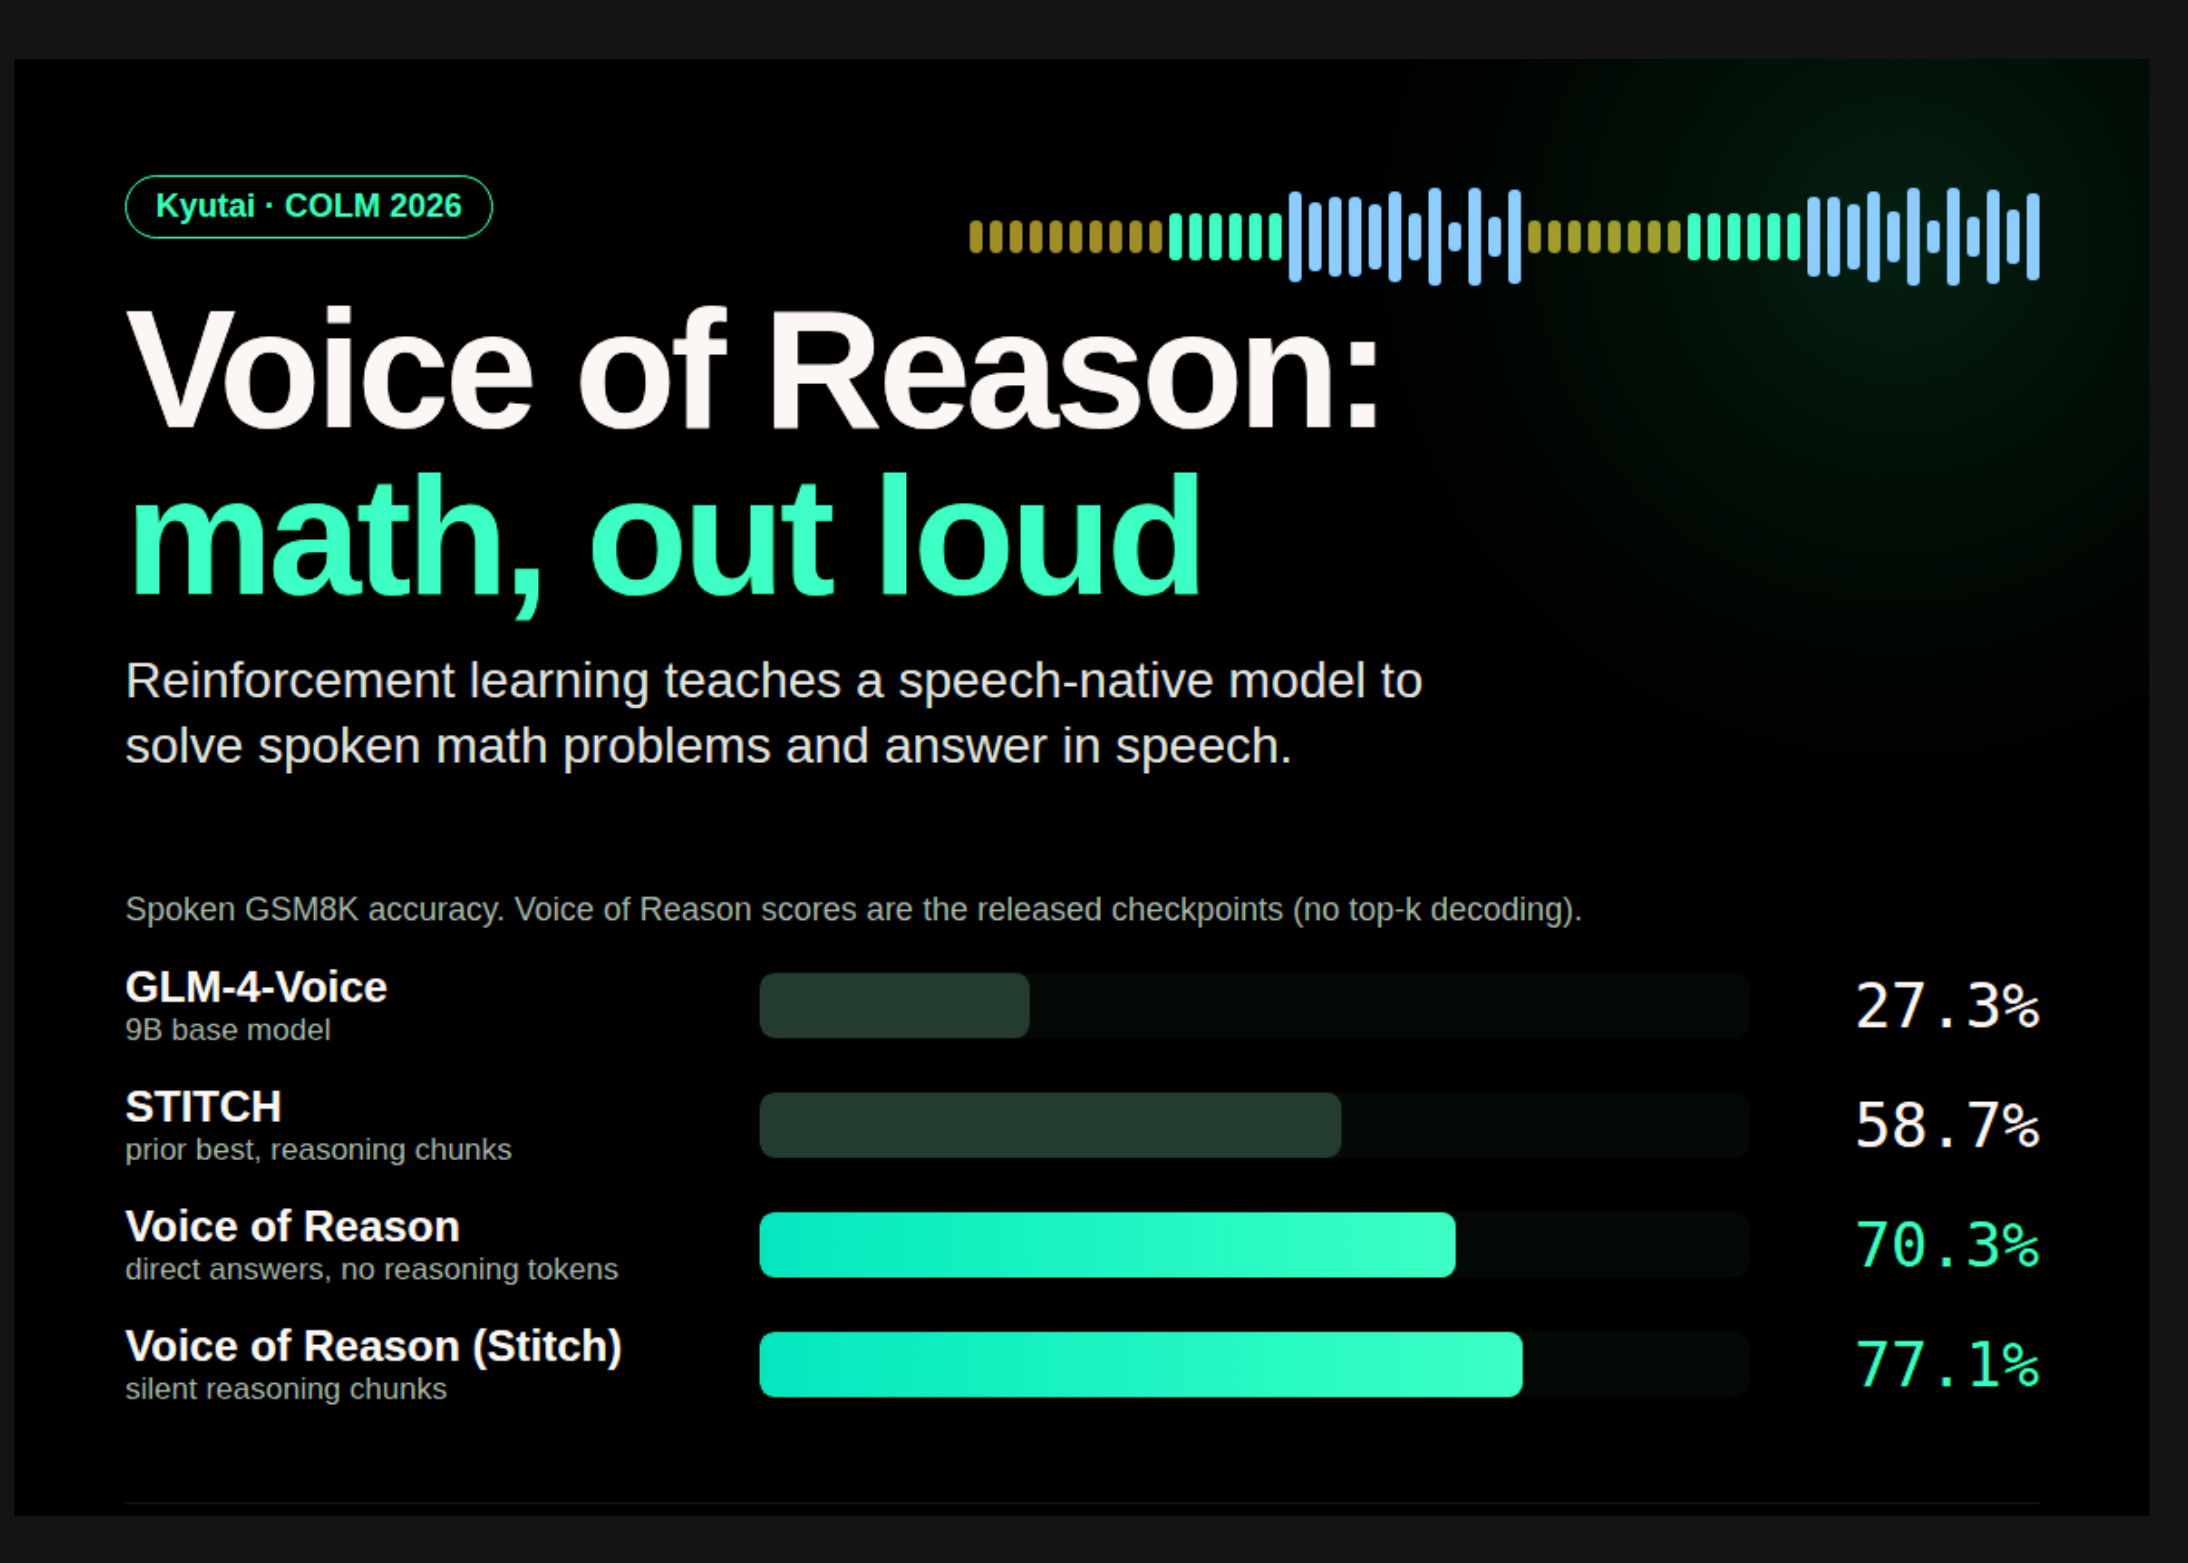
Kyutai Releases Voice of Reason: A Speech-Native Model that Solves Spoken Math with Reinforcement Learning
Kyutai has released Voice of Reason, 2 open-weight speech-to-speech models that solve math problems out loud. Both start from GLM-4-Voice-9B […]
Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters
A stock voice only needs to sound good. A cloned voice must sound like one specific person. That is a […]
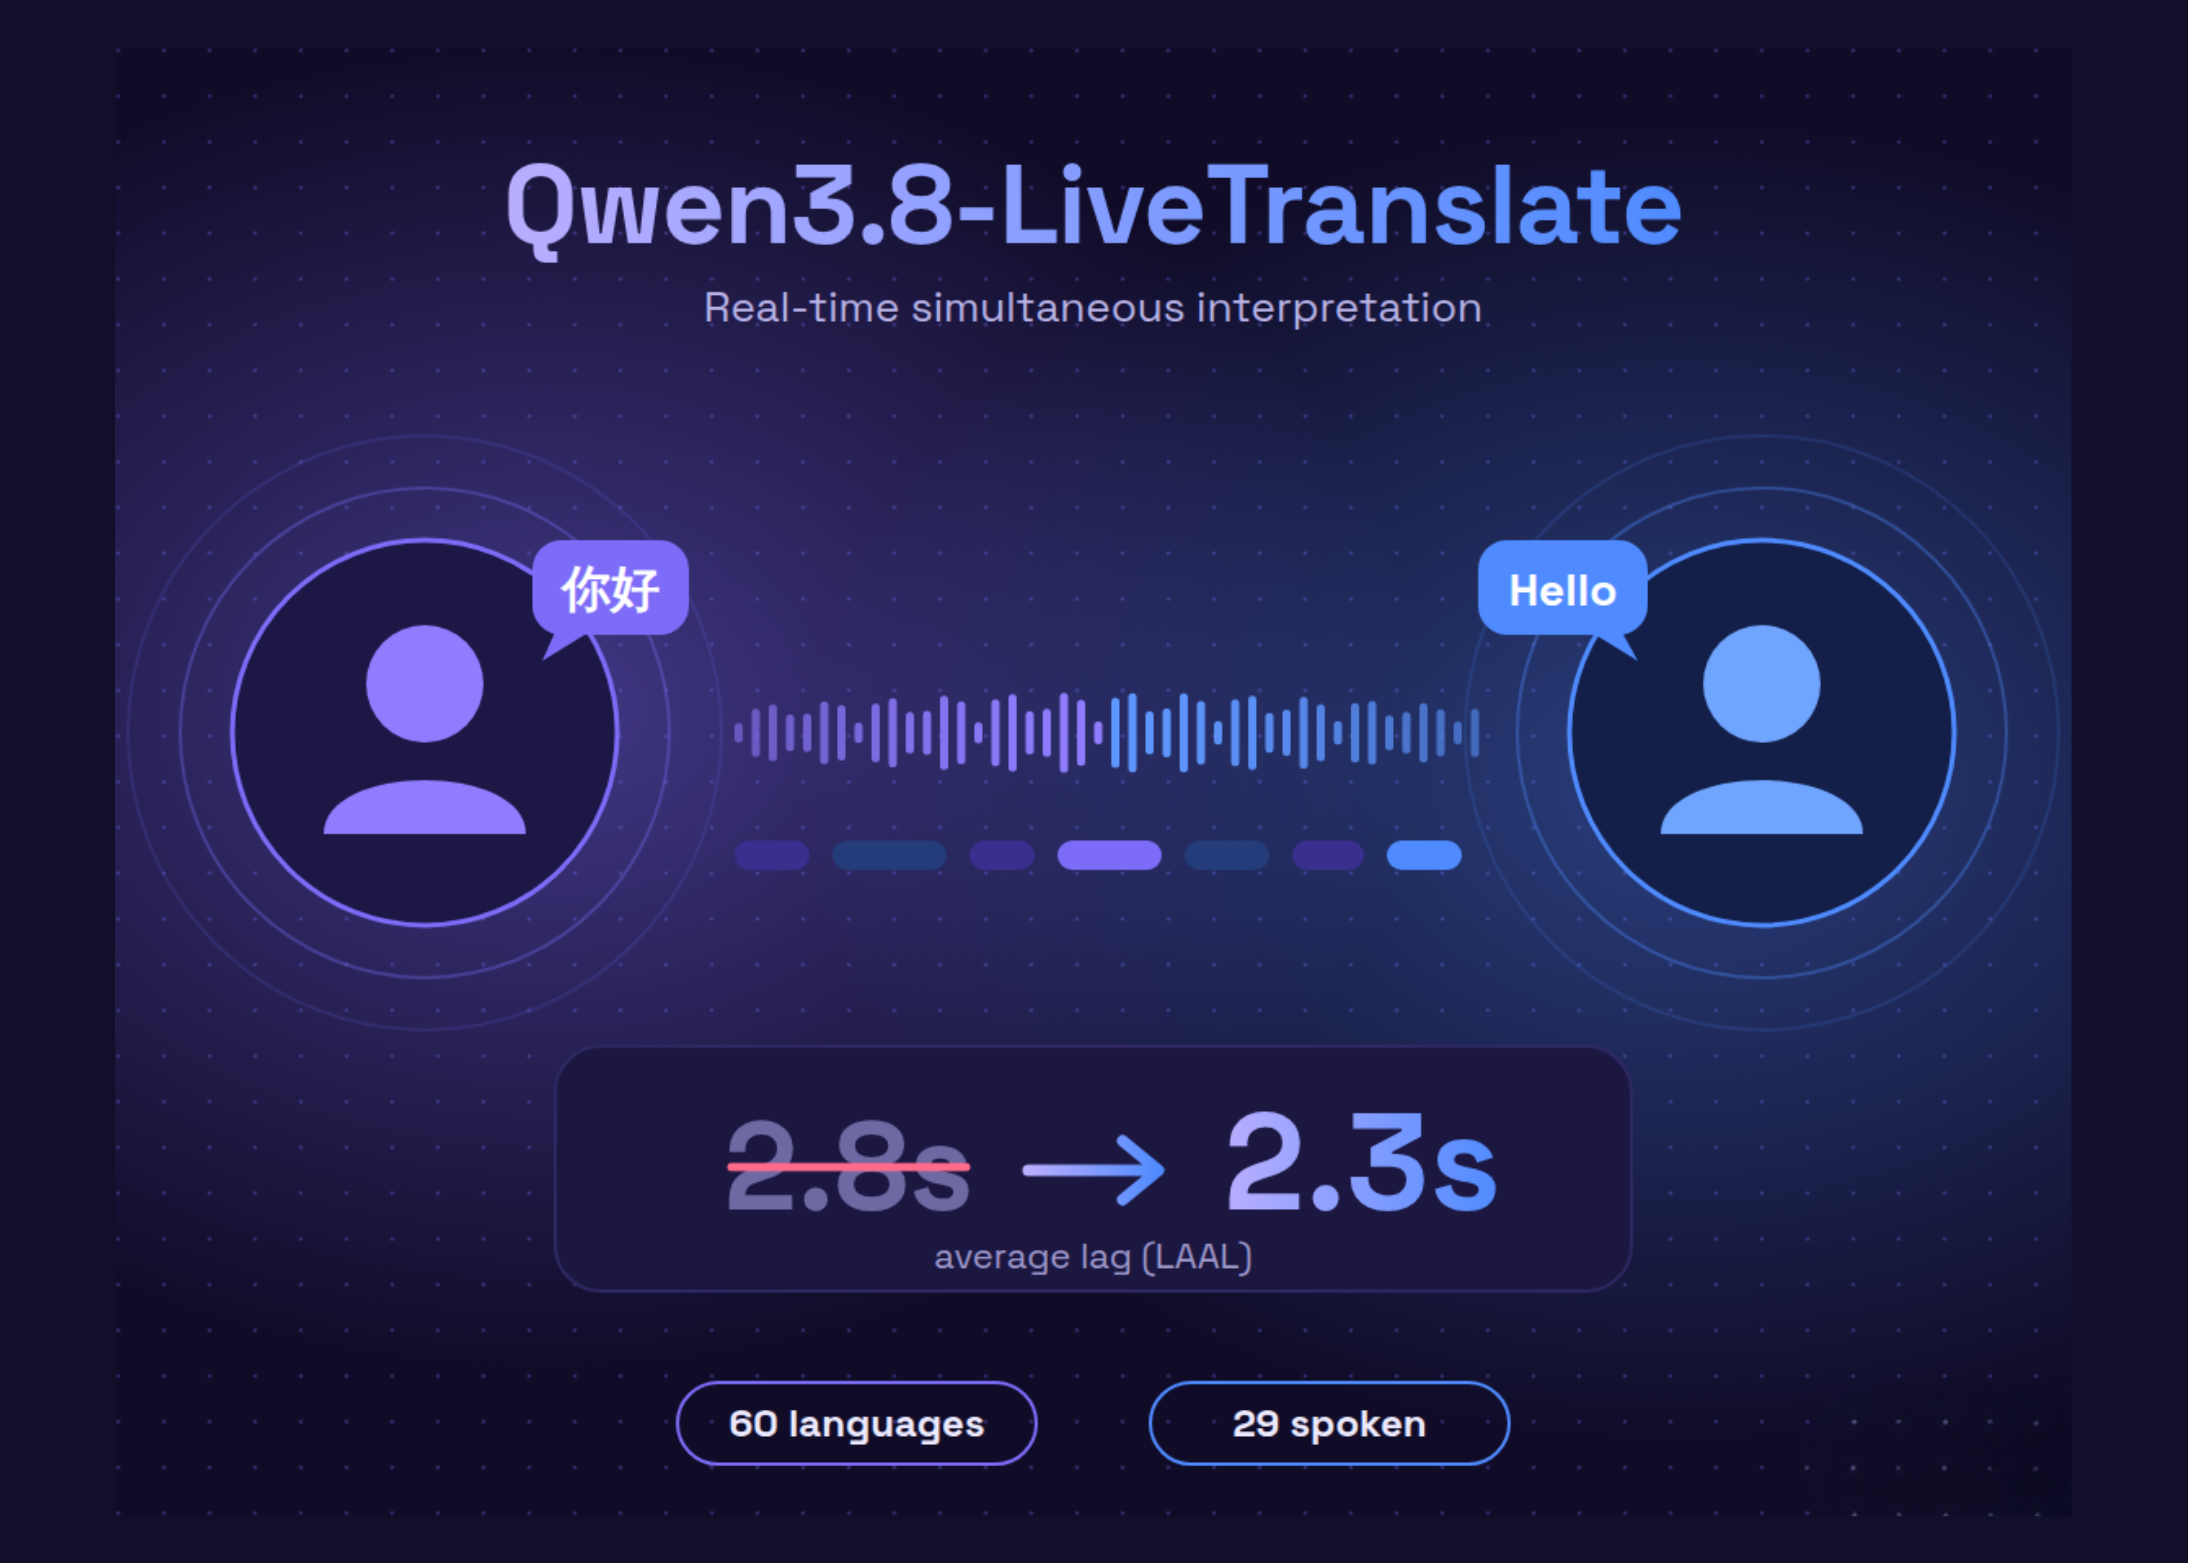
Alibaba Qwen Team Releases Qwen3.8-LiveTranslate: A Real-Time Interpretation Model That Cuts Average Lag to 2.3 Seconds Across 60 Languages
Qwen has released Qwen3.8-LiveTranslate, its next-generation real-time simultaneous interpretation model. It listens to live speech, with optional video frames, and […]
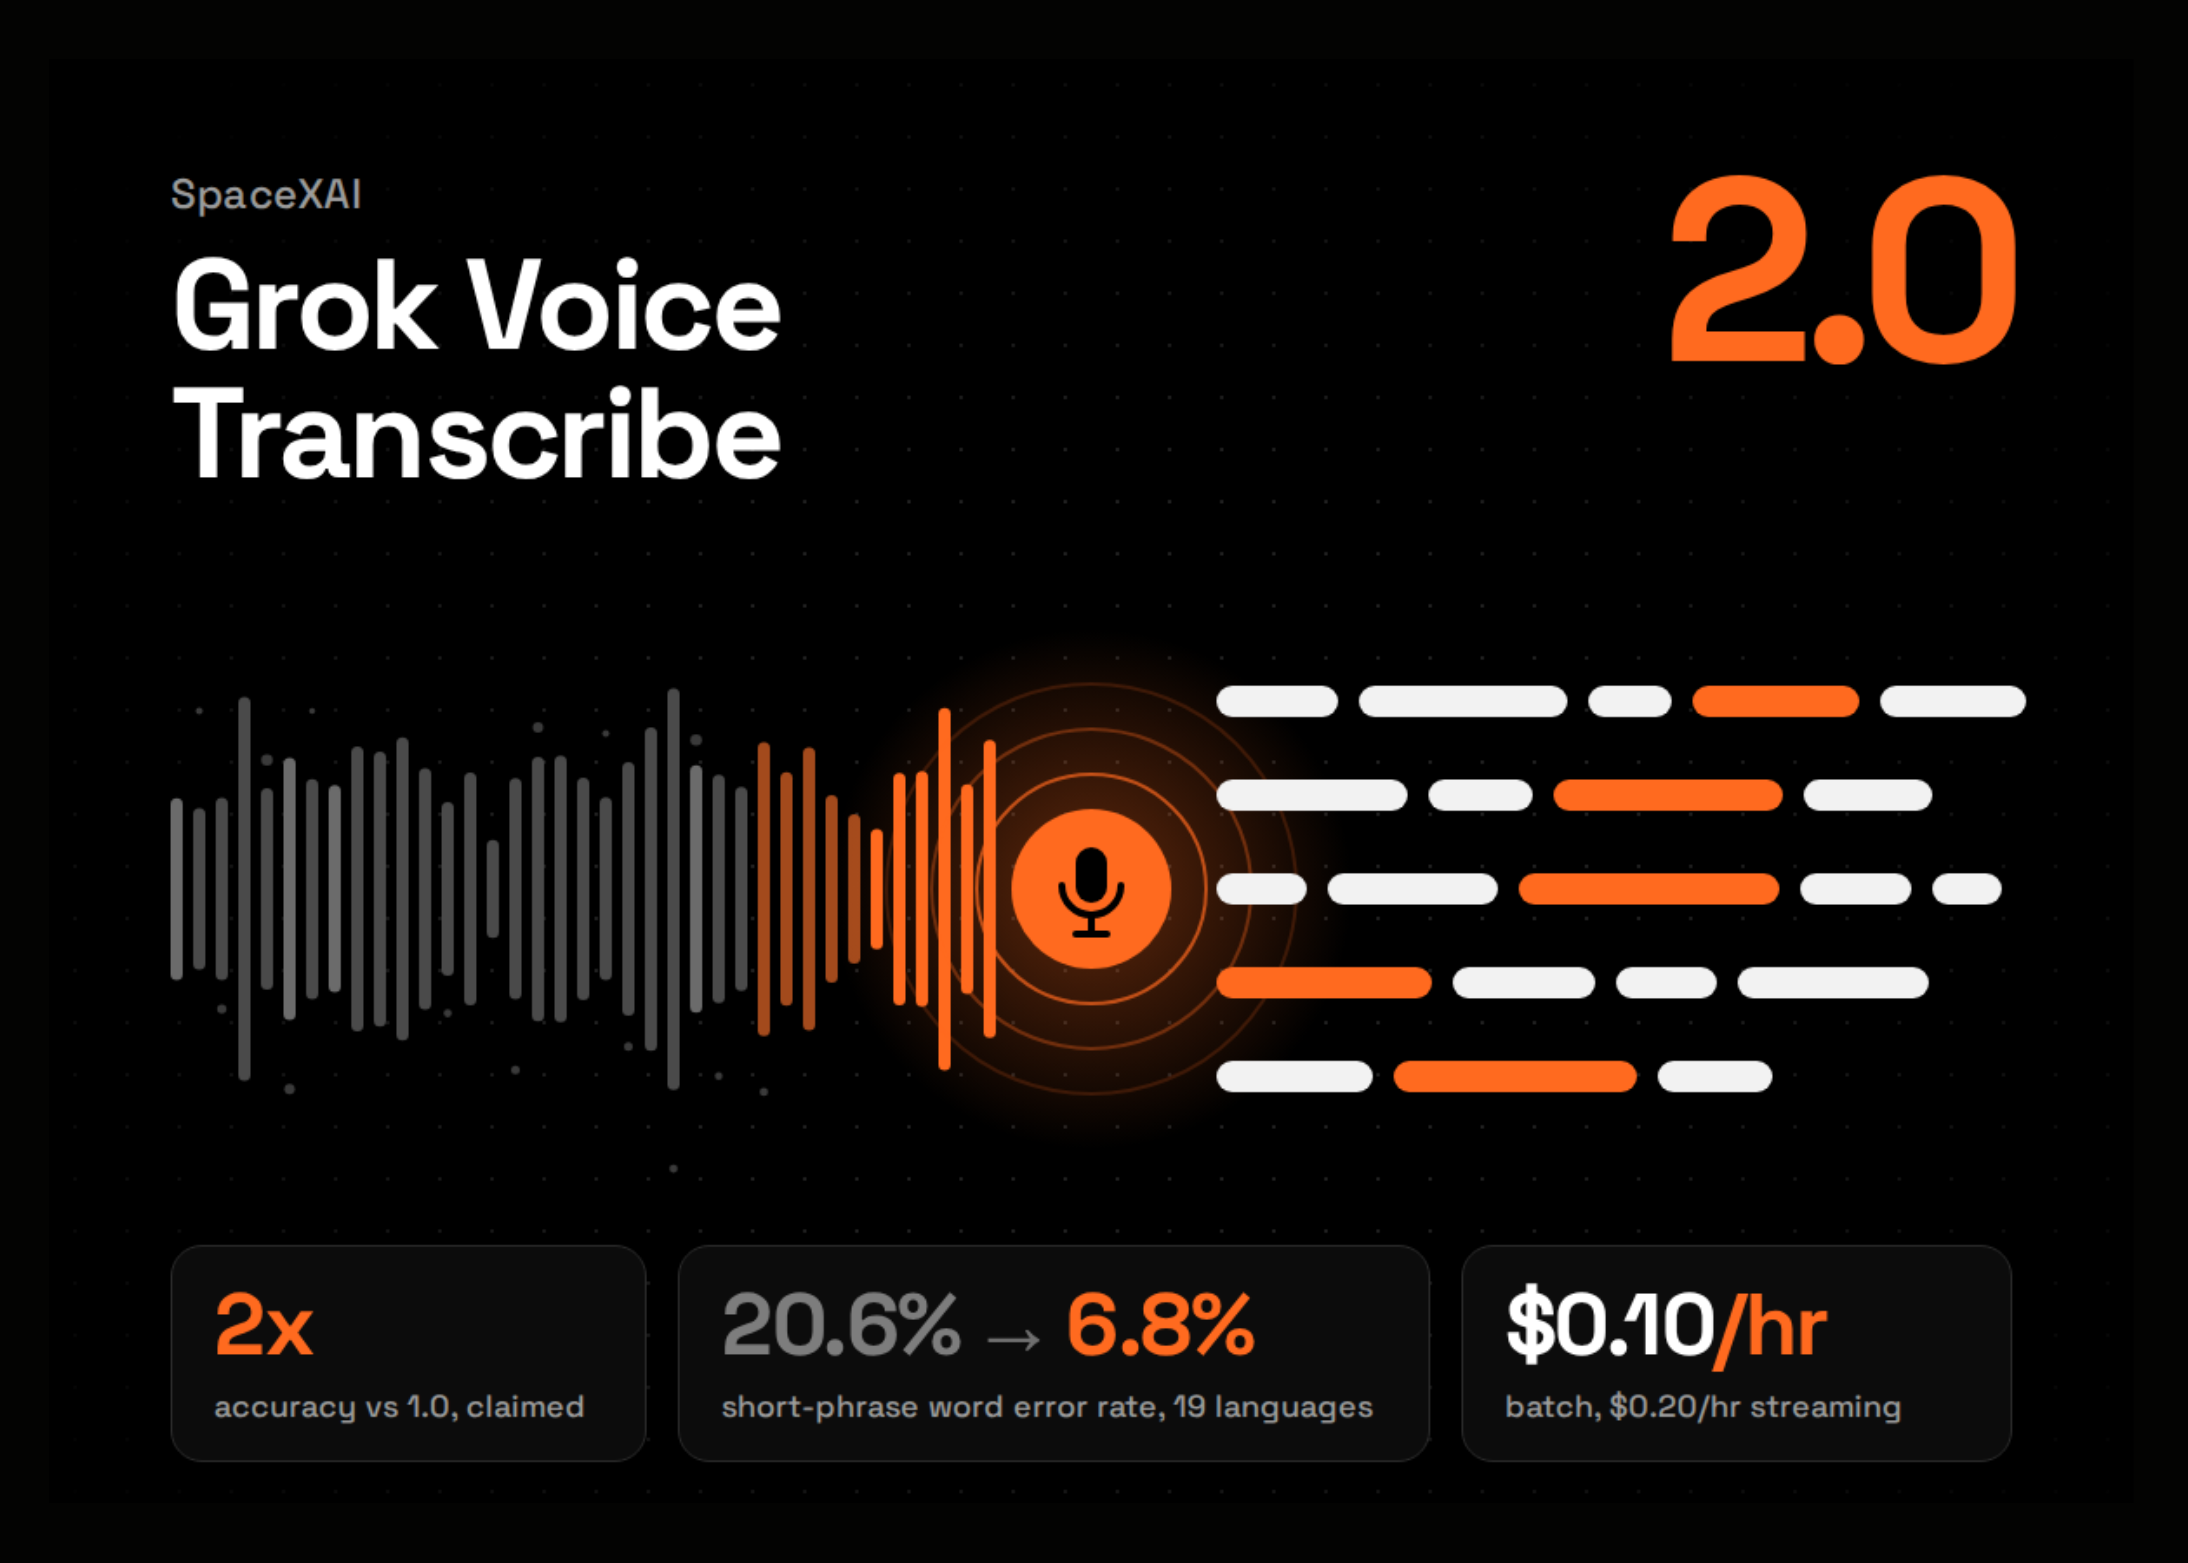
SpaceXAI Releases Grok Voice Transcribe 2.0: A Speech-to-Text API Claiming 2x Accuracy Over 1.0 at $0.10 per Hour
SpaceXAI has released Grok Voice Transcribe 2.0, its newest speech-to-text (STT) model. The development team claims it to be twice […]
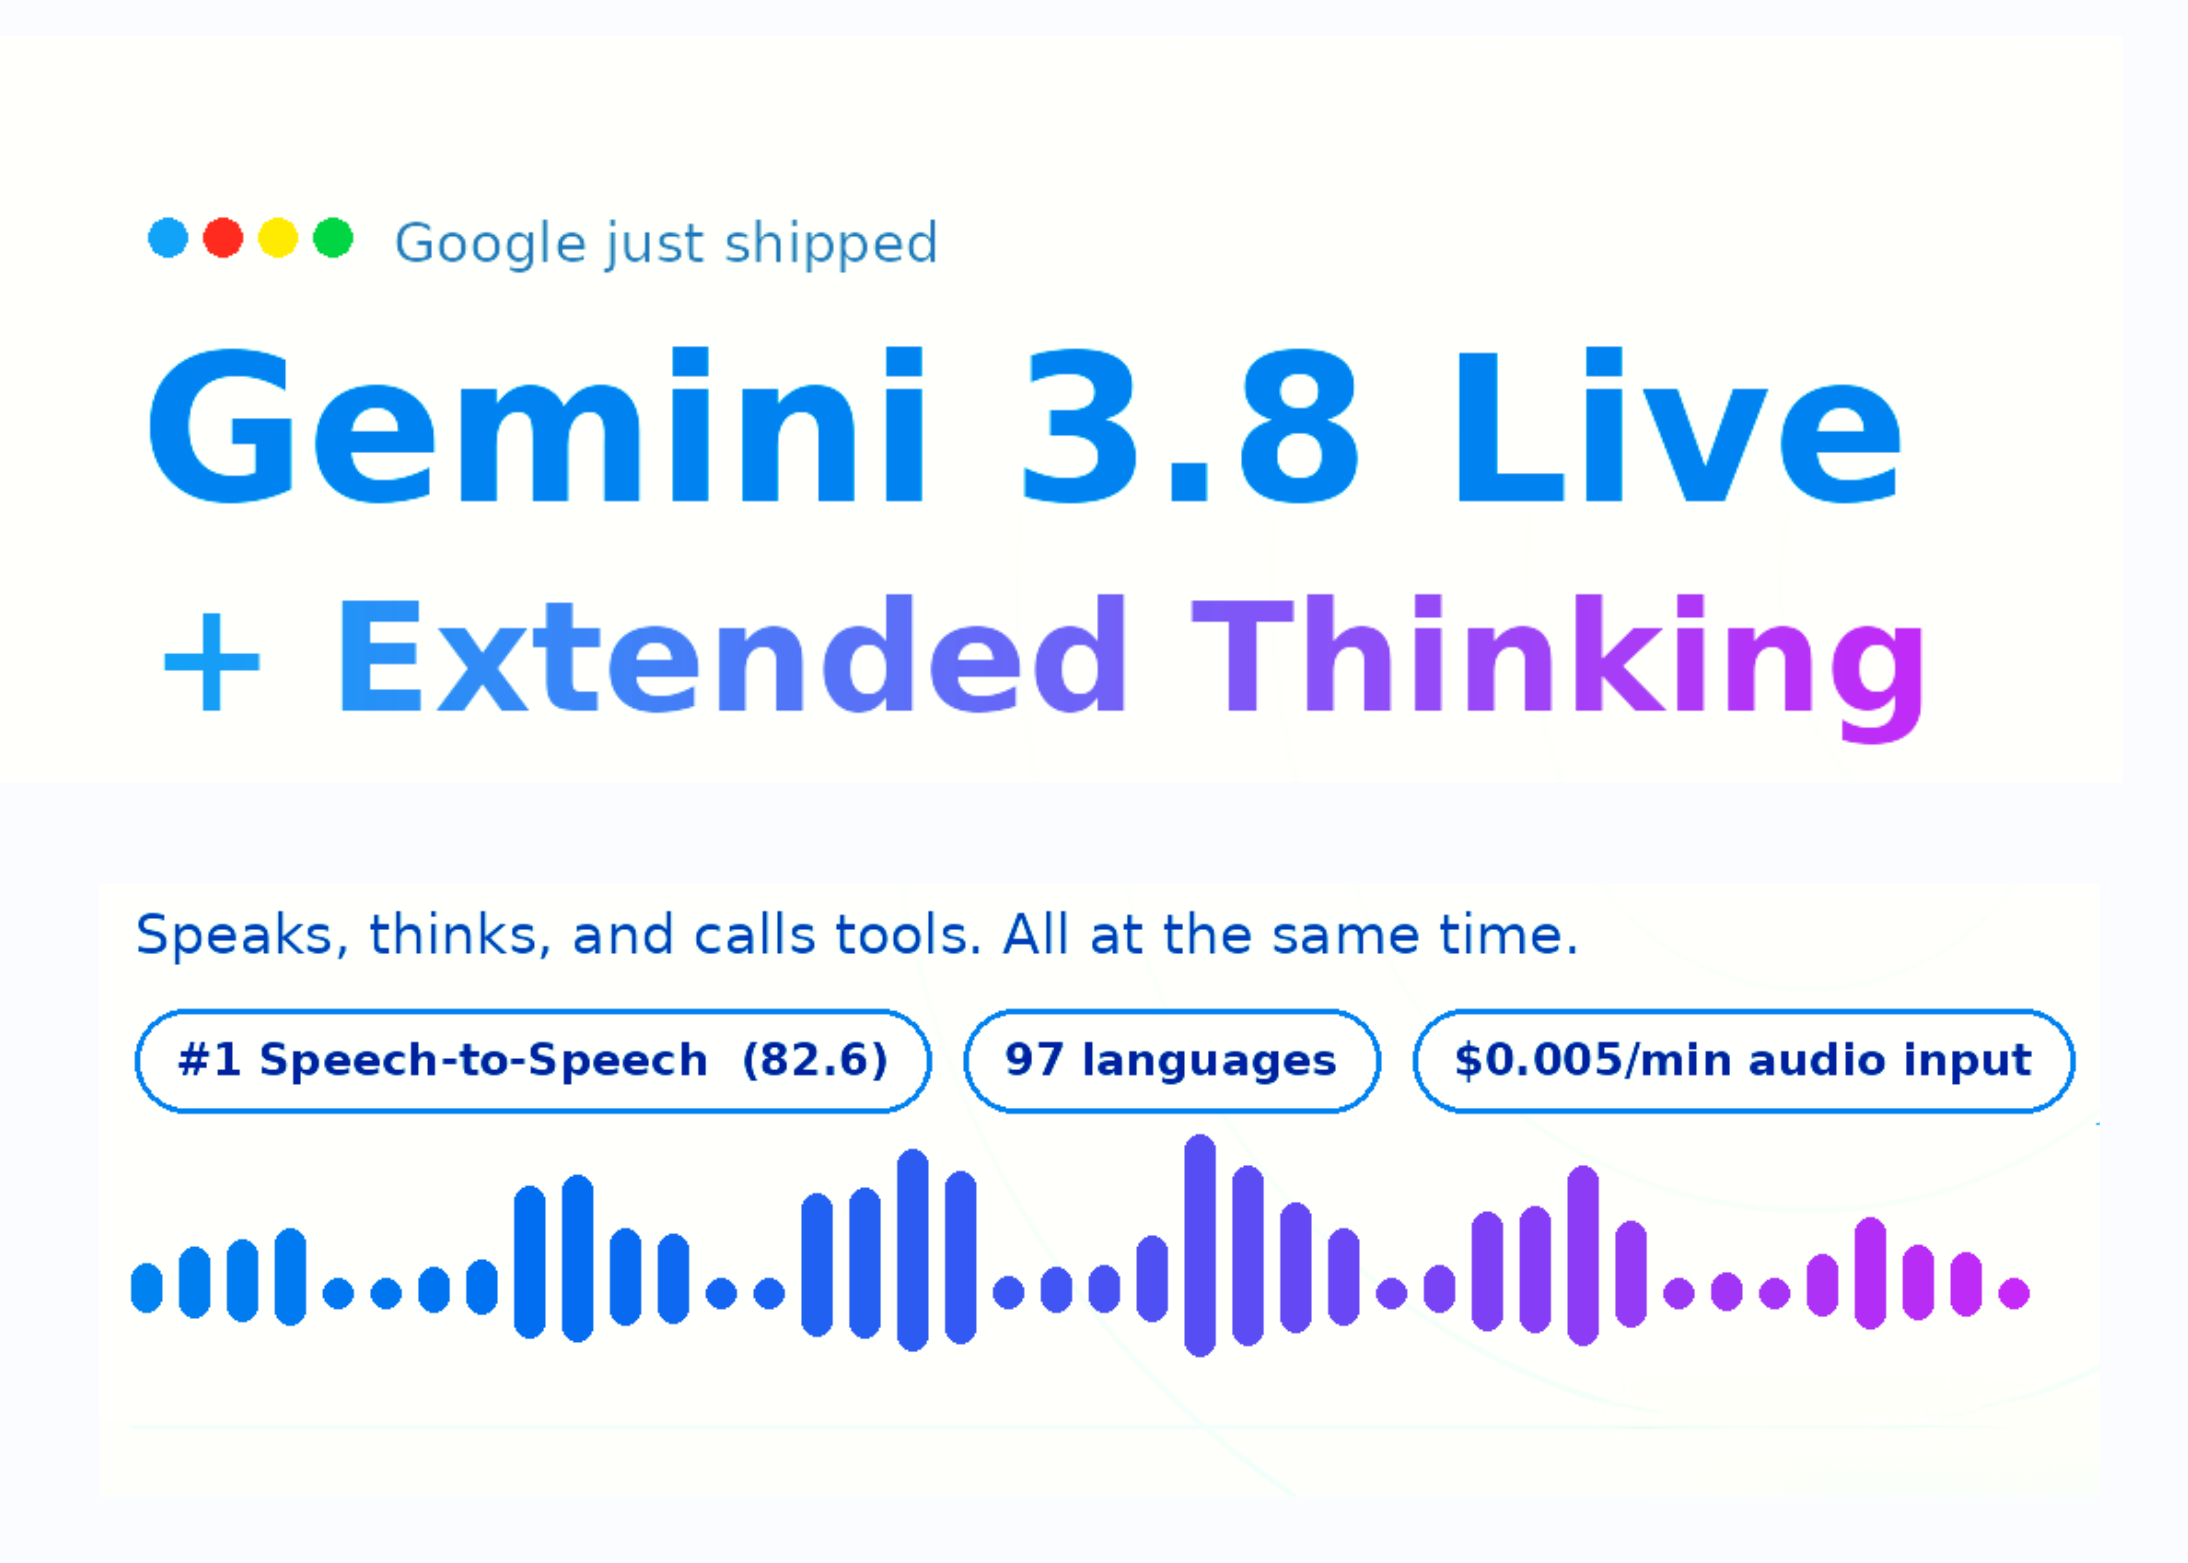
Google Releases Gemini 3.8 Live and 3.8 Live Extended Thinking for Production Grade Voice Agents
Google has introduced Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking, its most advanced live dialogue models to date. […]

Cohere Releases North Small Translate: A 218B MoE Translation Model That Scores 83.6 on WMT26 Across 50 Languages
Cohere has released North Small Translate, an open-weight machine translation model from Cohere and Cohere Labs. It is a sparse […]
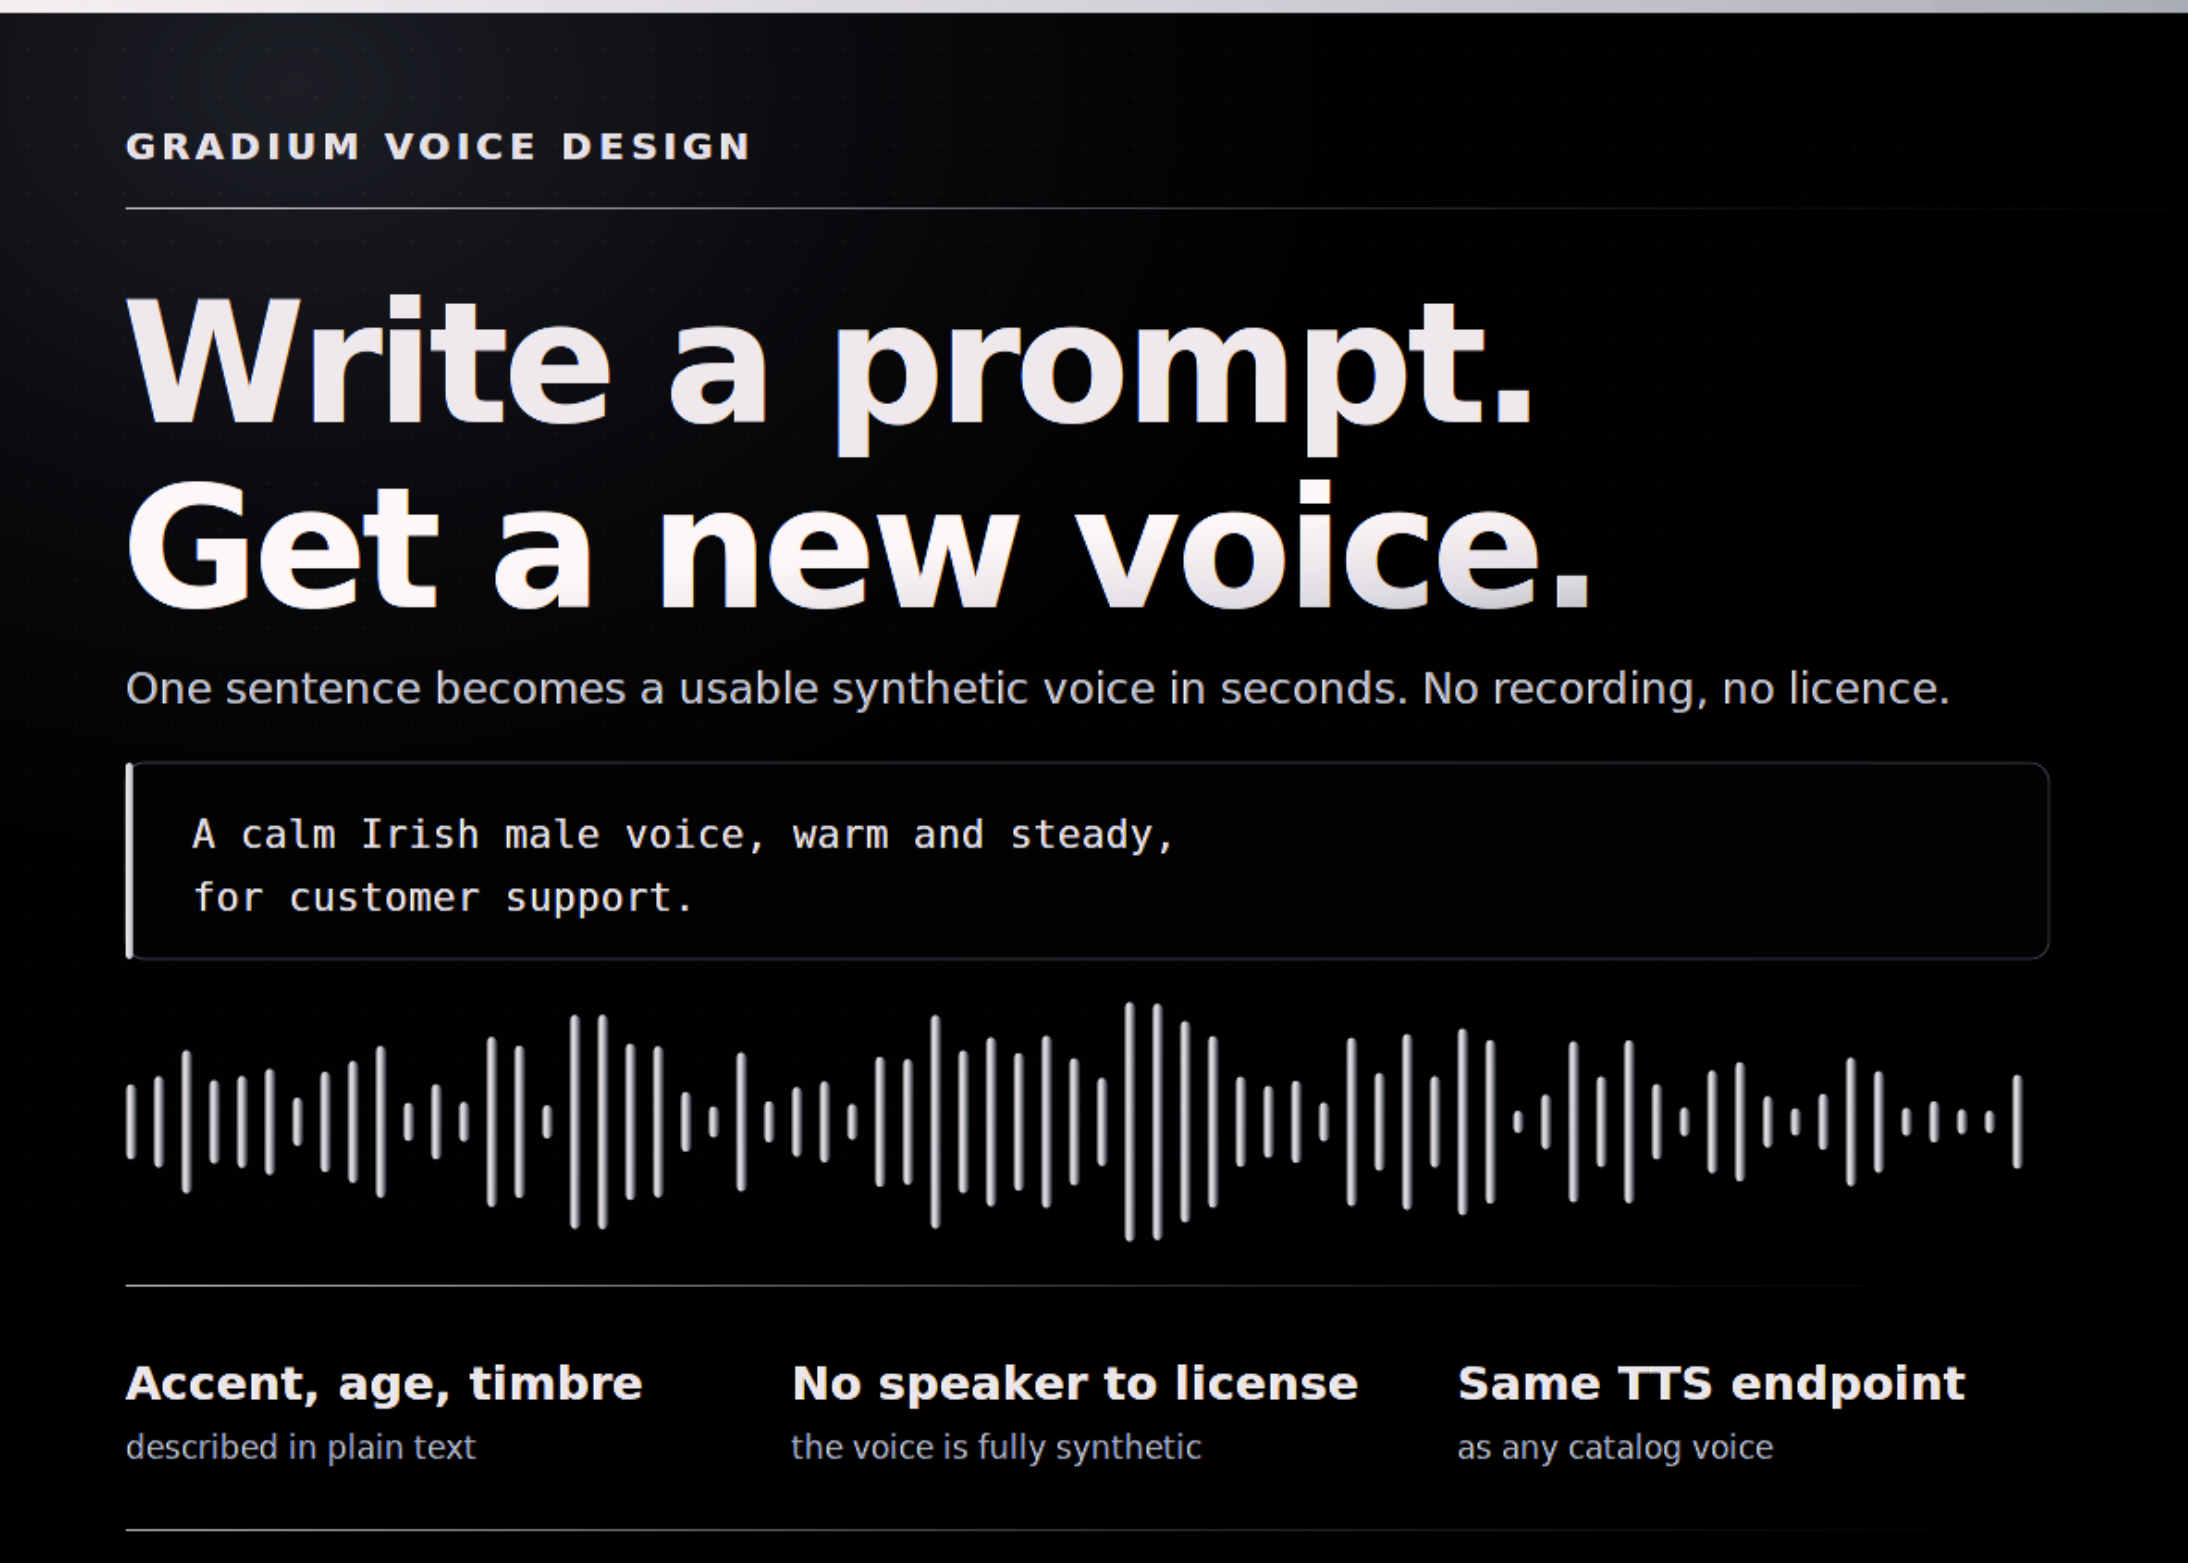
Gradium Launches Voice Design: Write a Prompt, Get a Brand New Synthetic Voice in Seconds
Voice agent teams keep hitting the same wall. The catalog holds 400 voices and the brief asks for the one […]
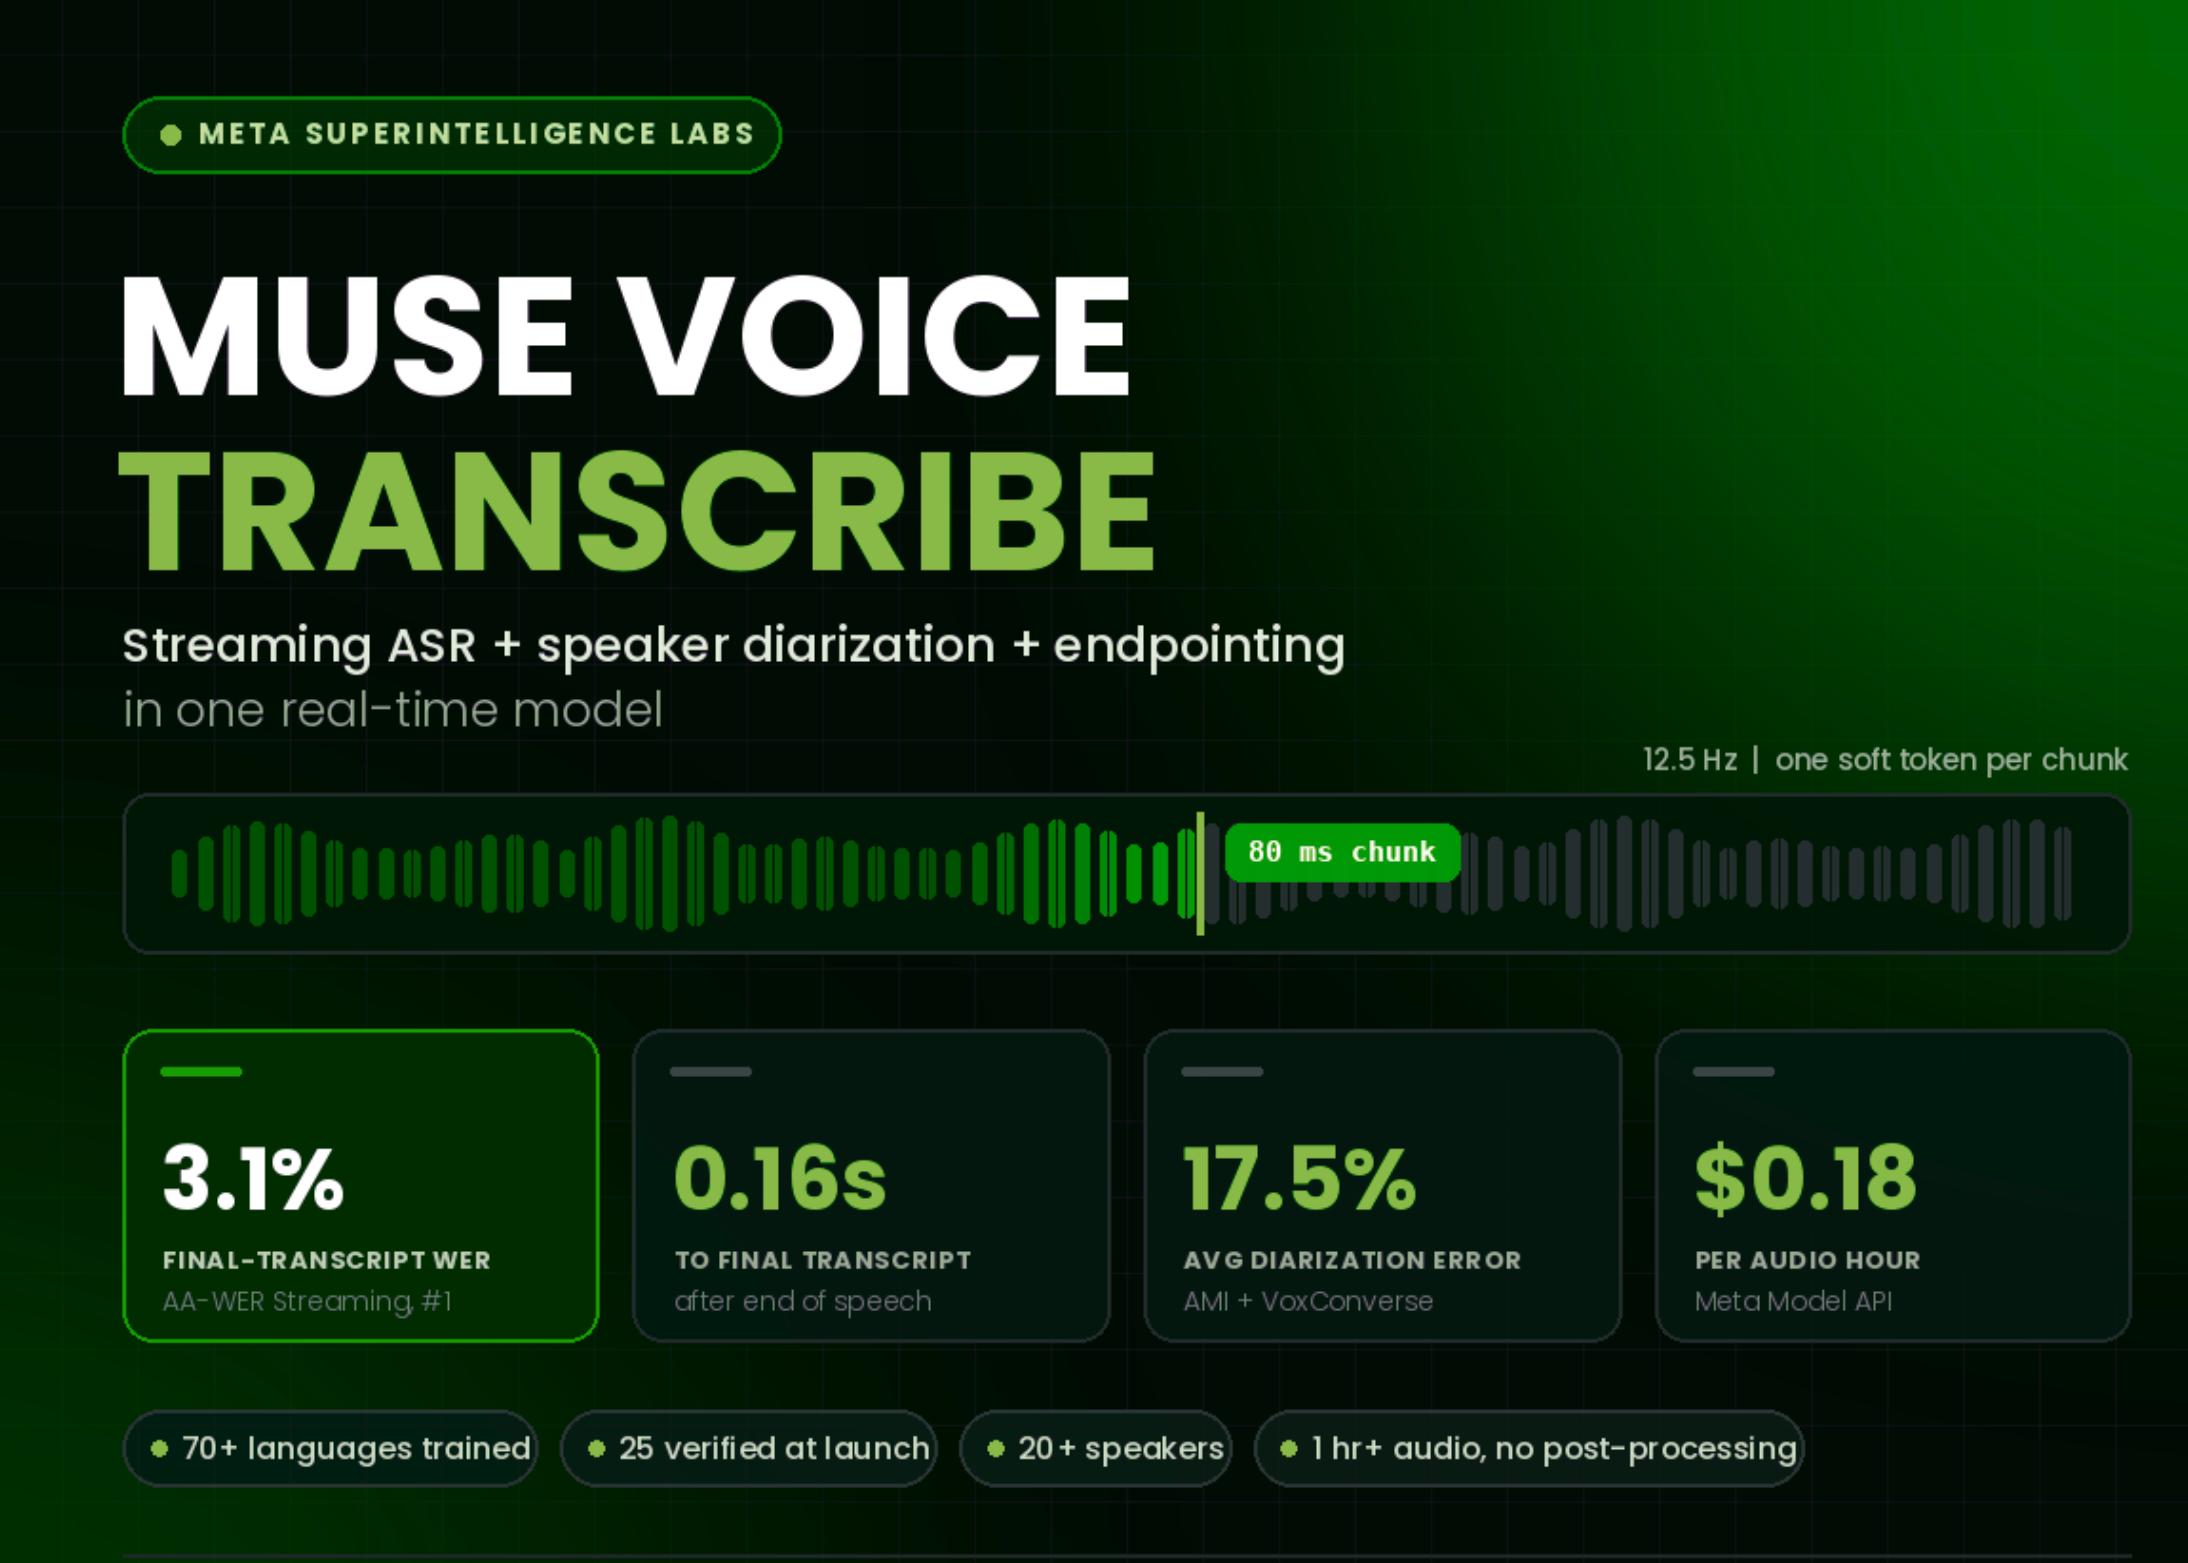
Meta Superintelligence Labs Releases Muse Voice Transcribe: One Real-Time Model for Streaming ASR, Diarization, and Endpointing
Most production voice stacks are three systems stitched together. One model transcribes, a second separates speakers, and a detector decides […]