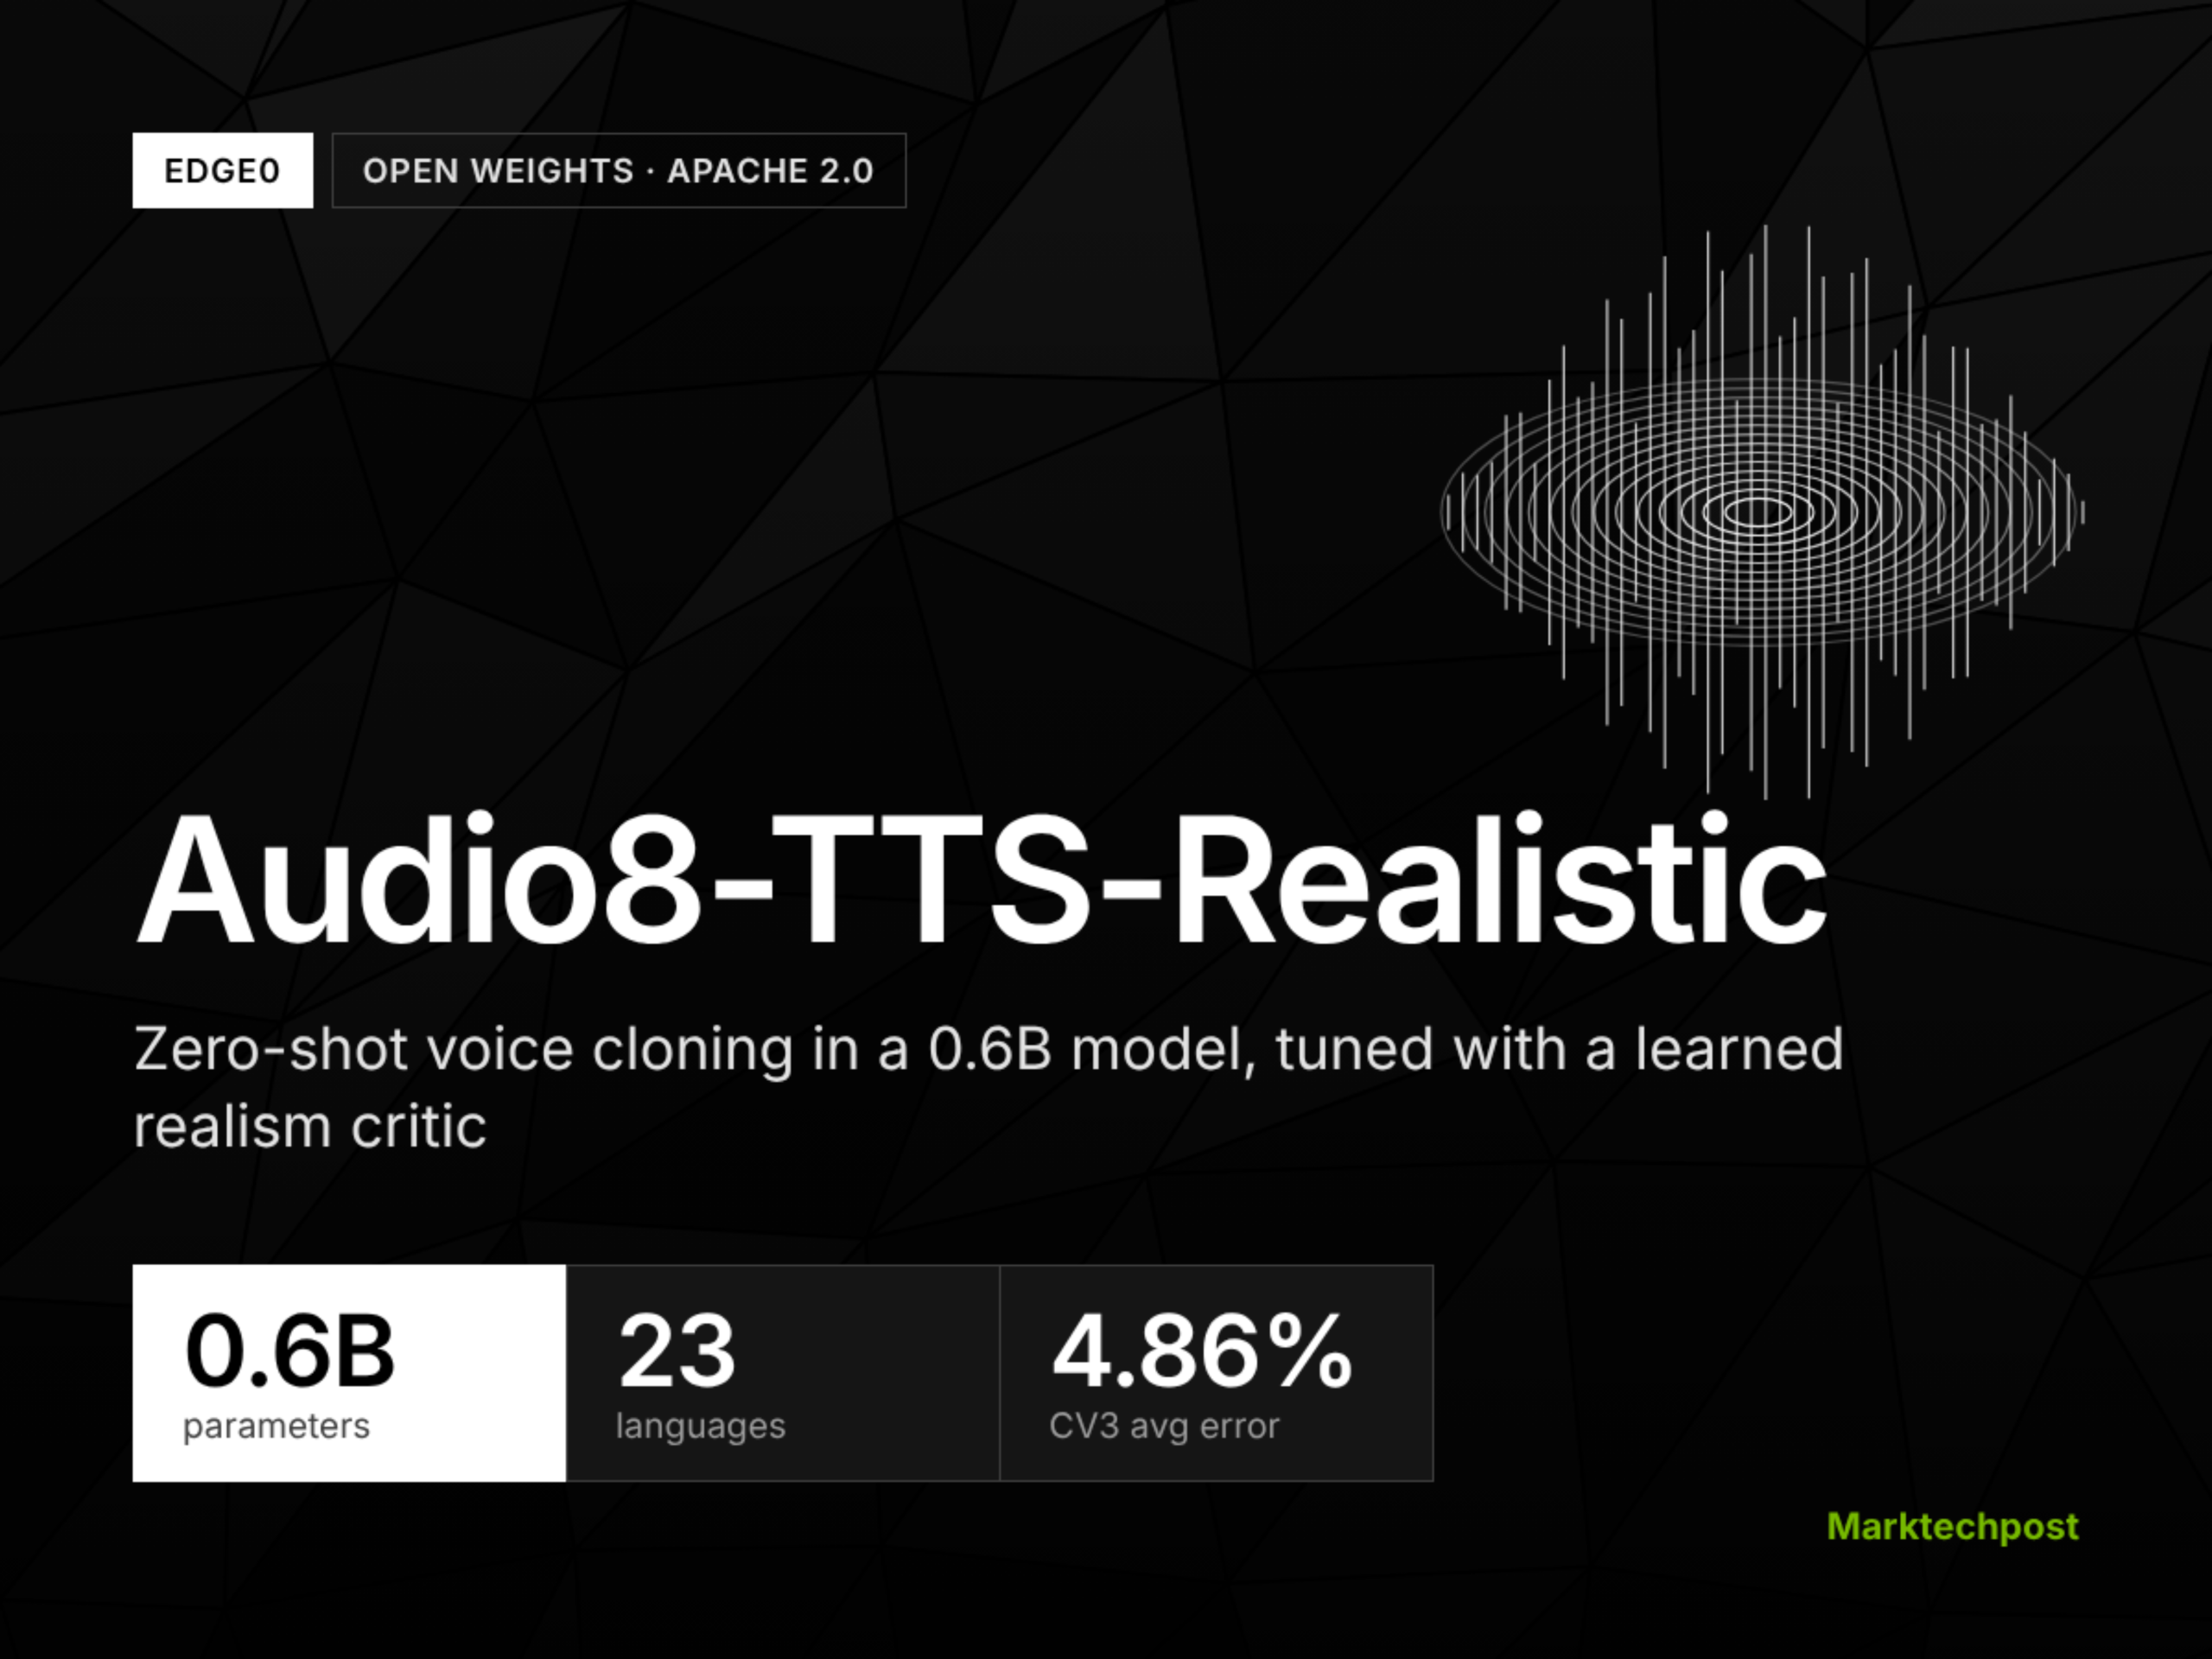
Edge0 has released Audio8-TTS-Realistic, an open-weight text-to-speech model for zero-shot voice cloning. Audio8-TTS-Realistic is a 0.6B-parameter model that clones a […]
Category: TTS
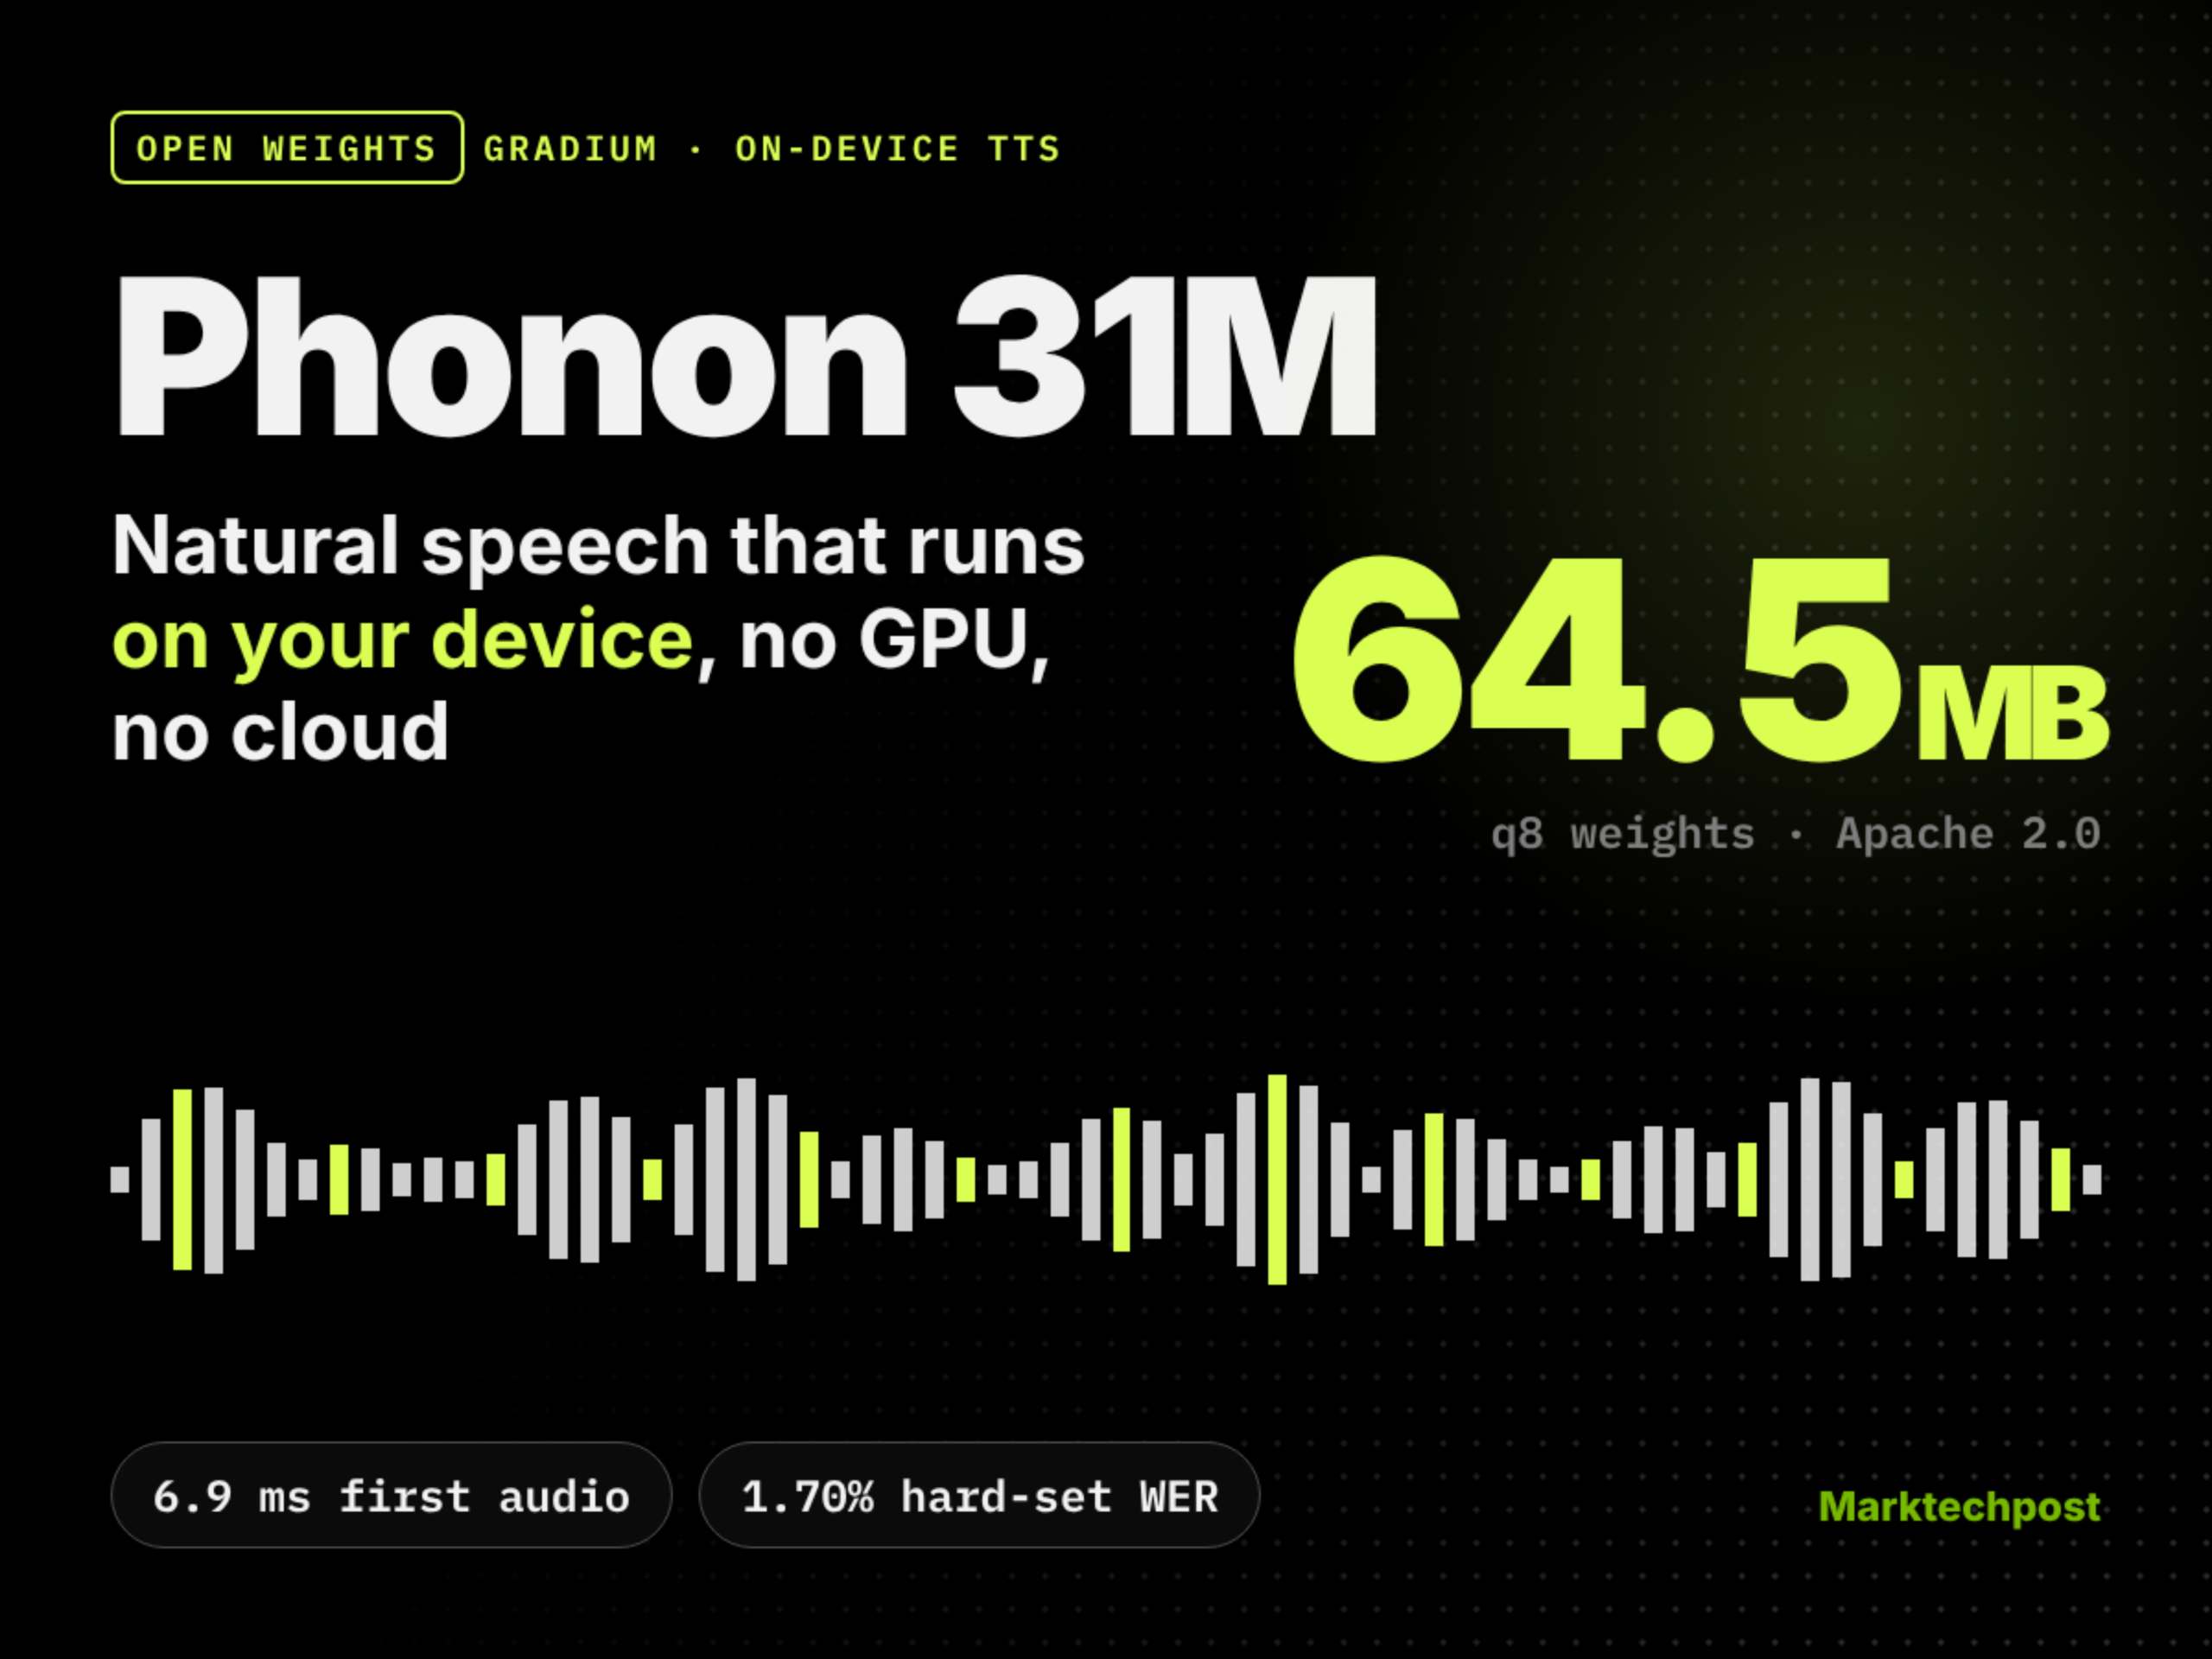
Gradium Open-Sources Phonon, a 31M-Parameter On-Device TTS Model Under Apache 2.0
Gradium has open-sourced Phonon, a family of small text-to-speech models built to run on the device. The Gradium Phonon on-device […]
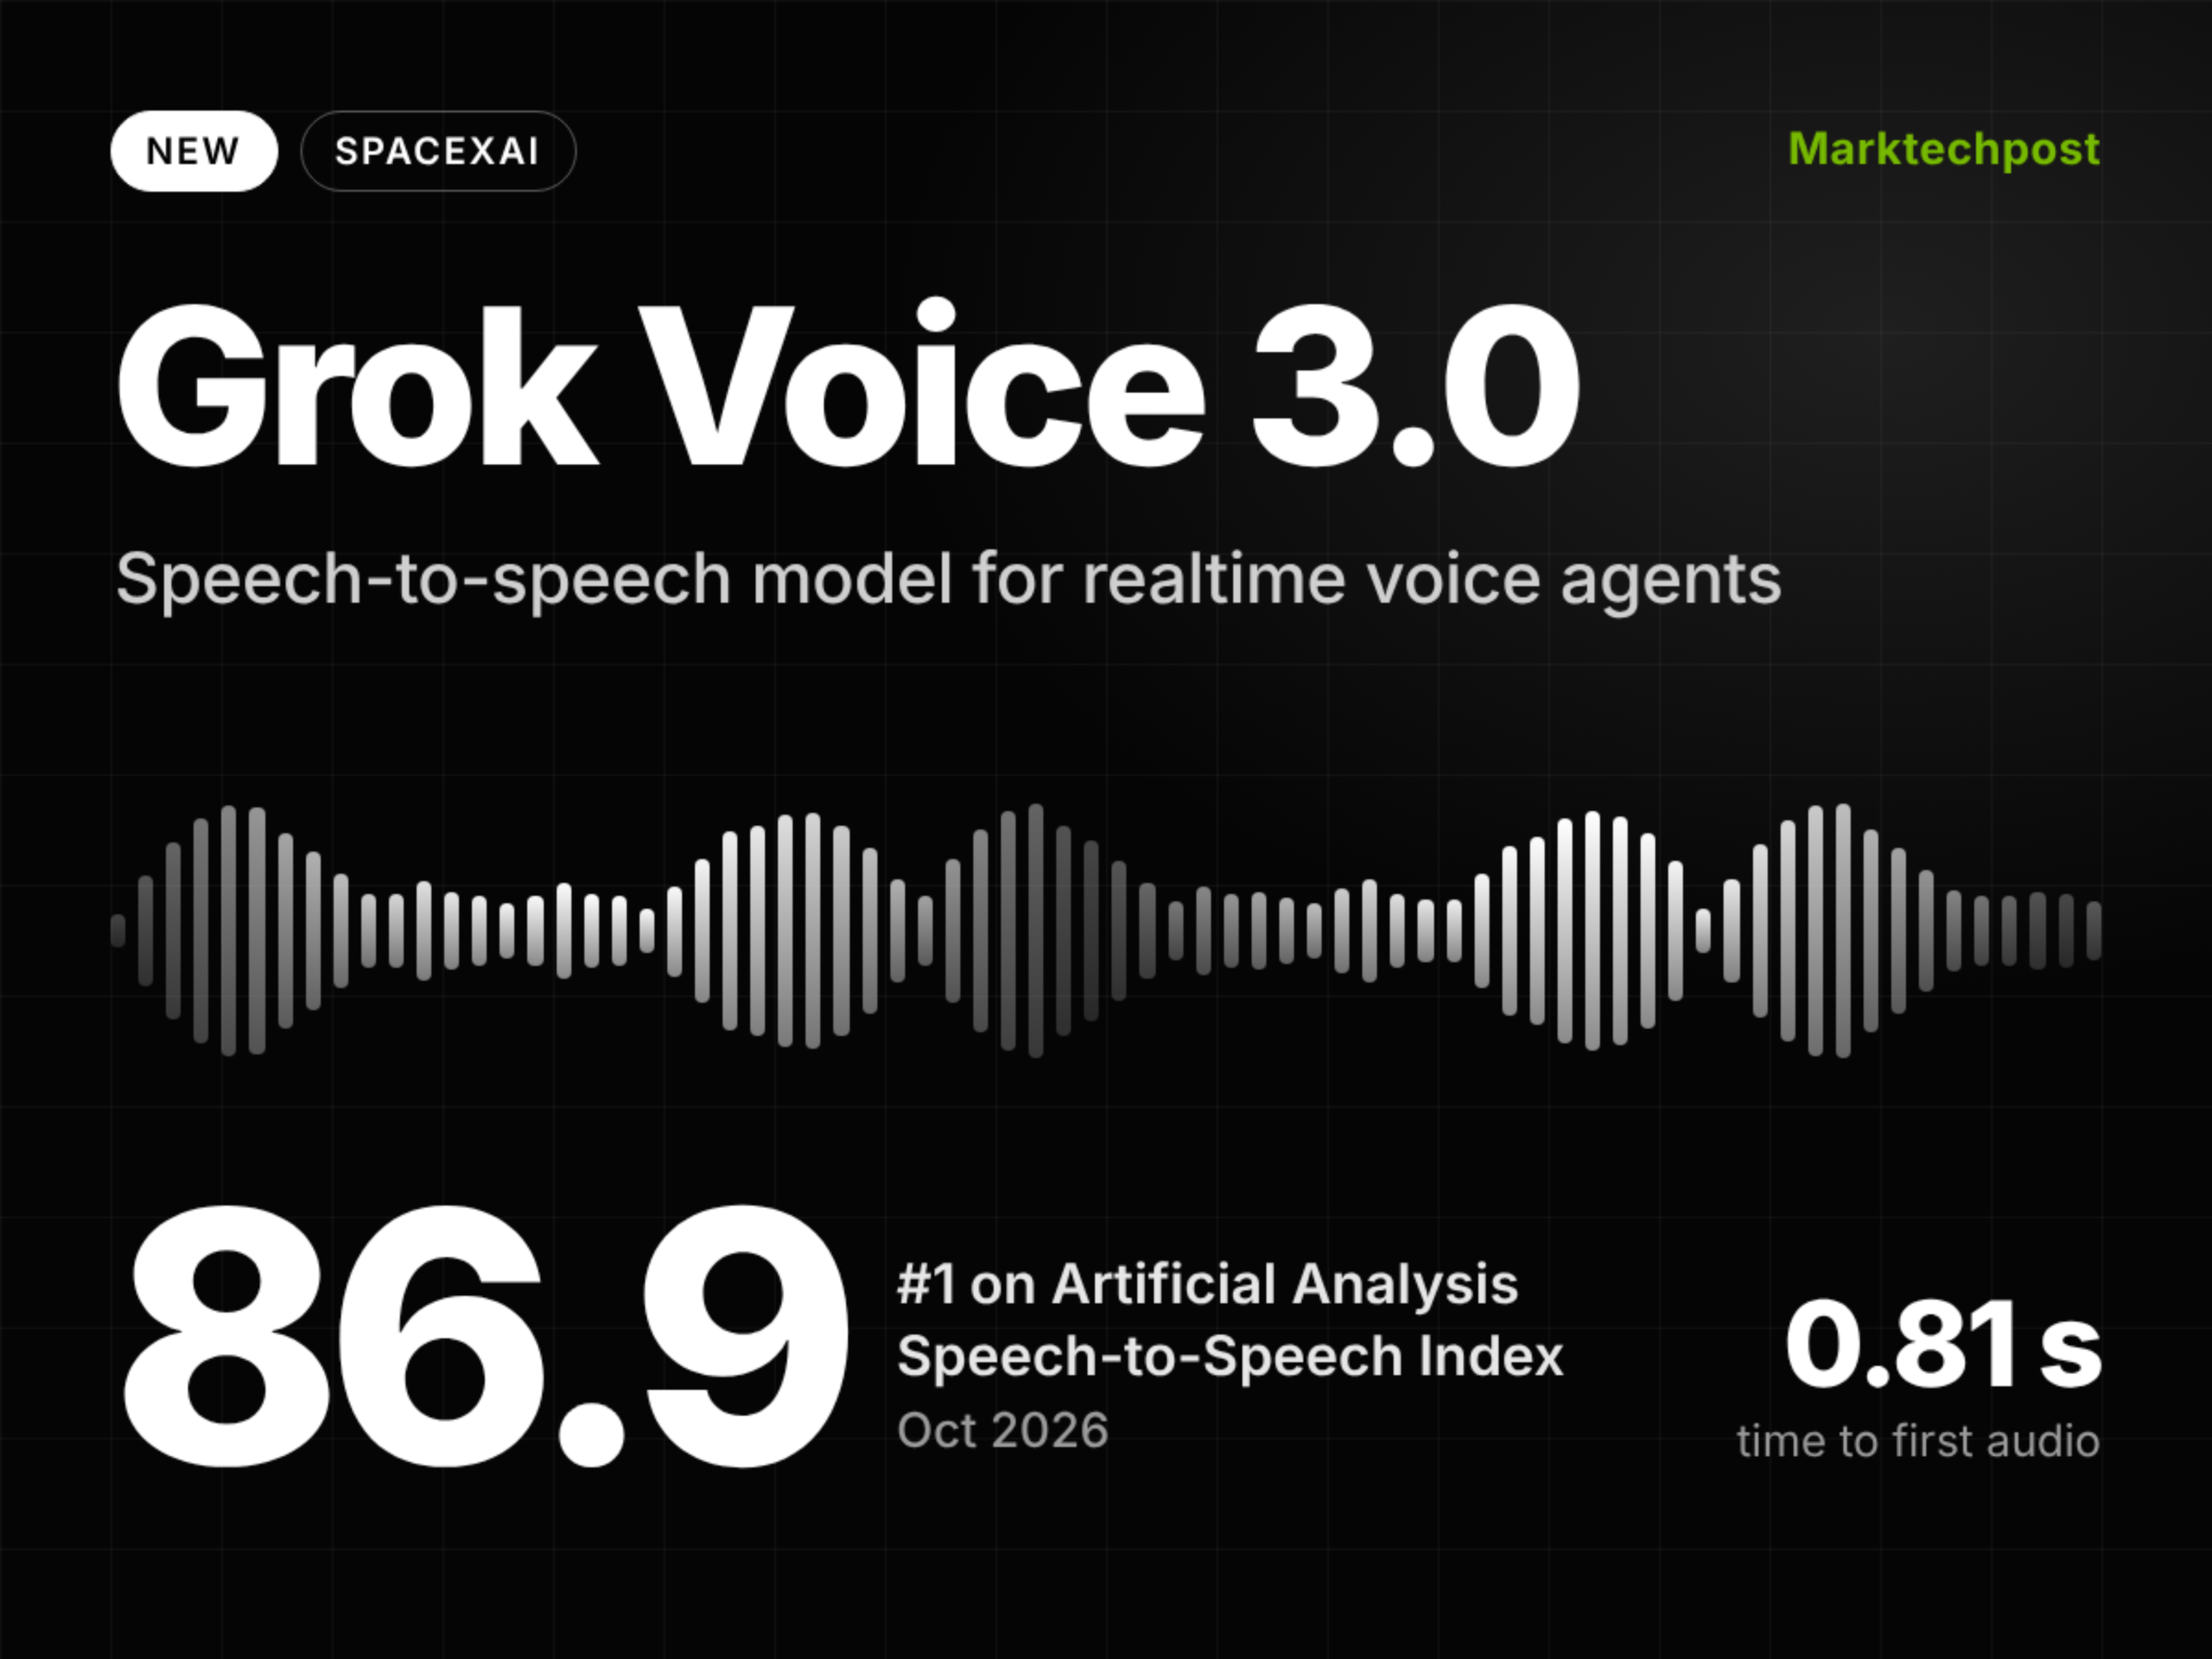
Meet Grok Voice 3.0: SpaceXAI Voice Agent Model Ranks #1 on Artificial Analysis
SpaceXAI just released Grok Voice 3.0. Grok Voice 3.0 is a SpaceXAI speech-to-speech model that listens, reasons, calls tools and […]
Meet S1-mini: Superwhisper’s 462 MB Open-Weights Text Normalizer That Turns Raw ASR Transcripts Into Clean Written Text
Superwhisper has released the S1 family of models: S1-Voice, S1-Language, and S1-mini. S1-Voice is a cloud speech-to-text model, and S1-Language […]

Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both Artificial Analysis Speech Arenas
Cartesia has released Sonic-3.6, the newest version of its real-time text-to-speech model. It arrives roughly three months after Sonic-3.5. The […]

PolyAI Releases Dialog-RSN-1: An Audio-Native Dialog Model That Fuses Turn-Taking, Speech Recognition, Function Calling, And Response
PolyAI has introduced Dialog-RSN-1, a dialog model that perceives the caller’s audio directly instead of reading a transcript. It fuses […]

Alibaba’s Tongyi Lab Releases Qwen-Audio-3.0-TTS, a Hosted Text-to-Speech Model in Flash and Plus Tiers Across 16 Languages
Alibaba’s Tongyi Lab has released Qwen-Audio-3.0-TTS, a production-oriented text-to-speech (TTS) system. The model ships in two variants from the same […]
Kyutai Releases MuScriptor: An Open-Weight Decoder-Only Transformer for Multi-Instrument Music Transcription to MIDI
Automatic Music Transcription (AMT) converts an audio recording into symbolic notes, usually MIDI. Single-instrument transcription already works reasonably well. However, […]
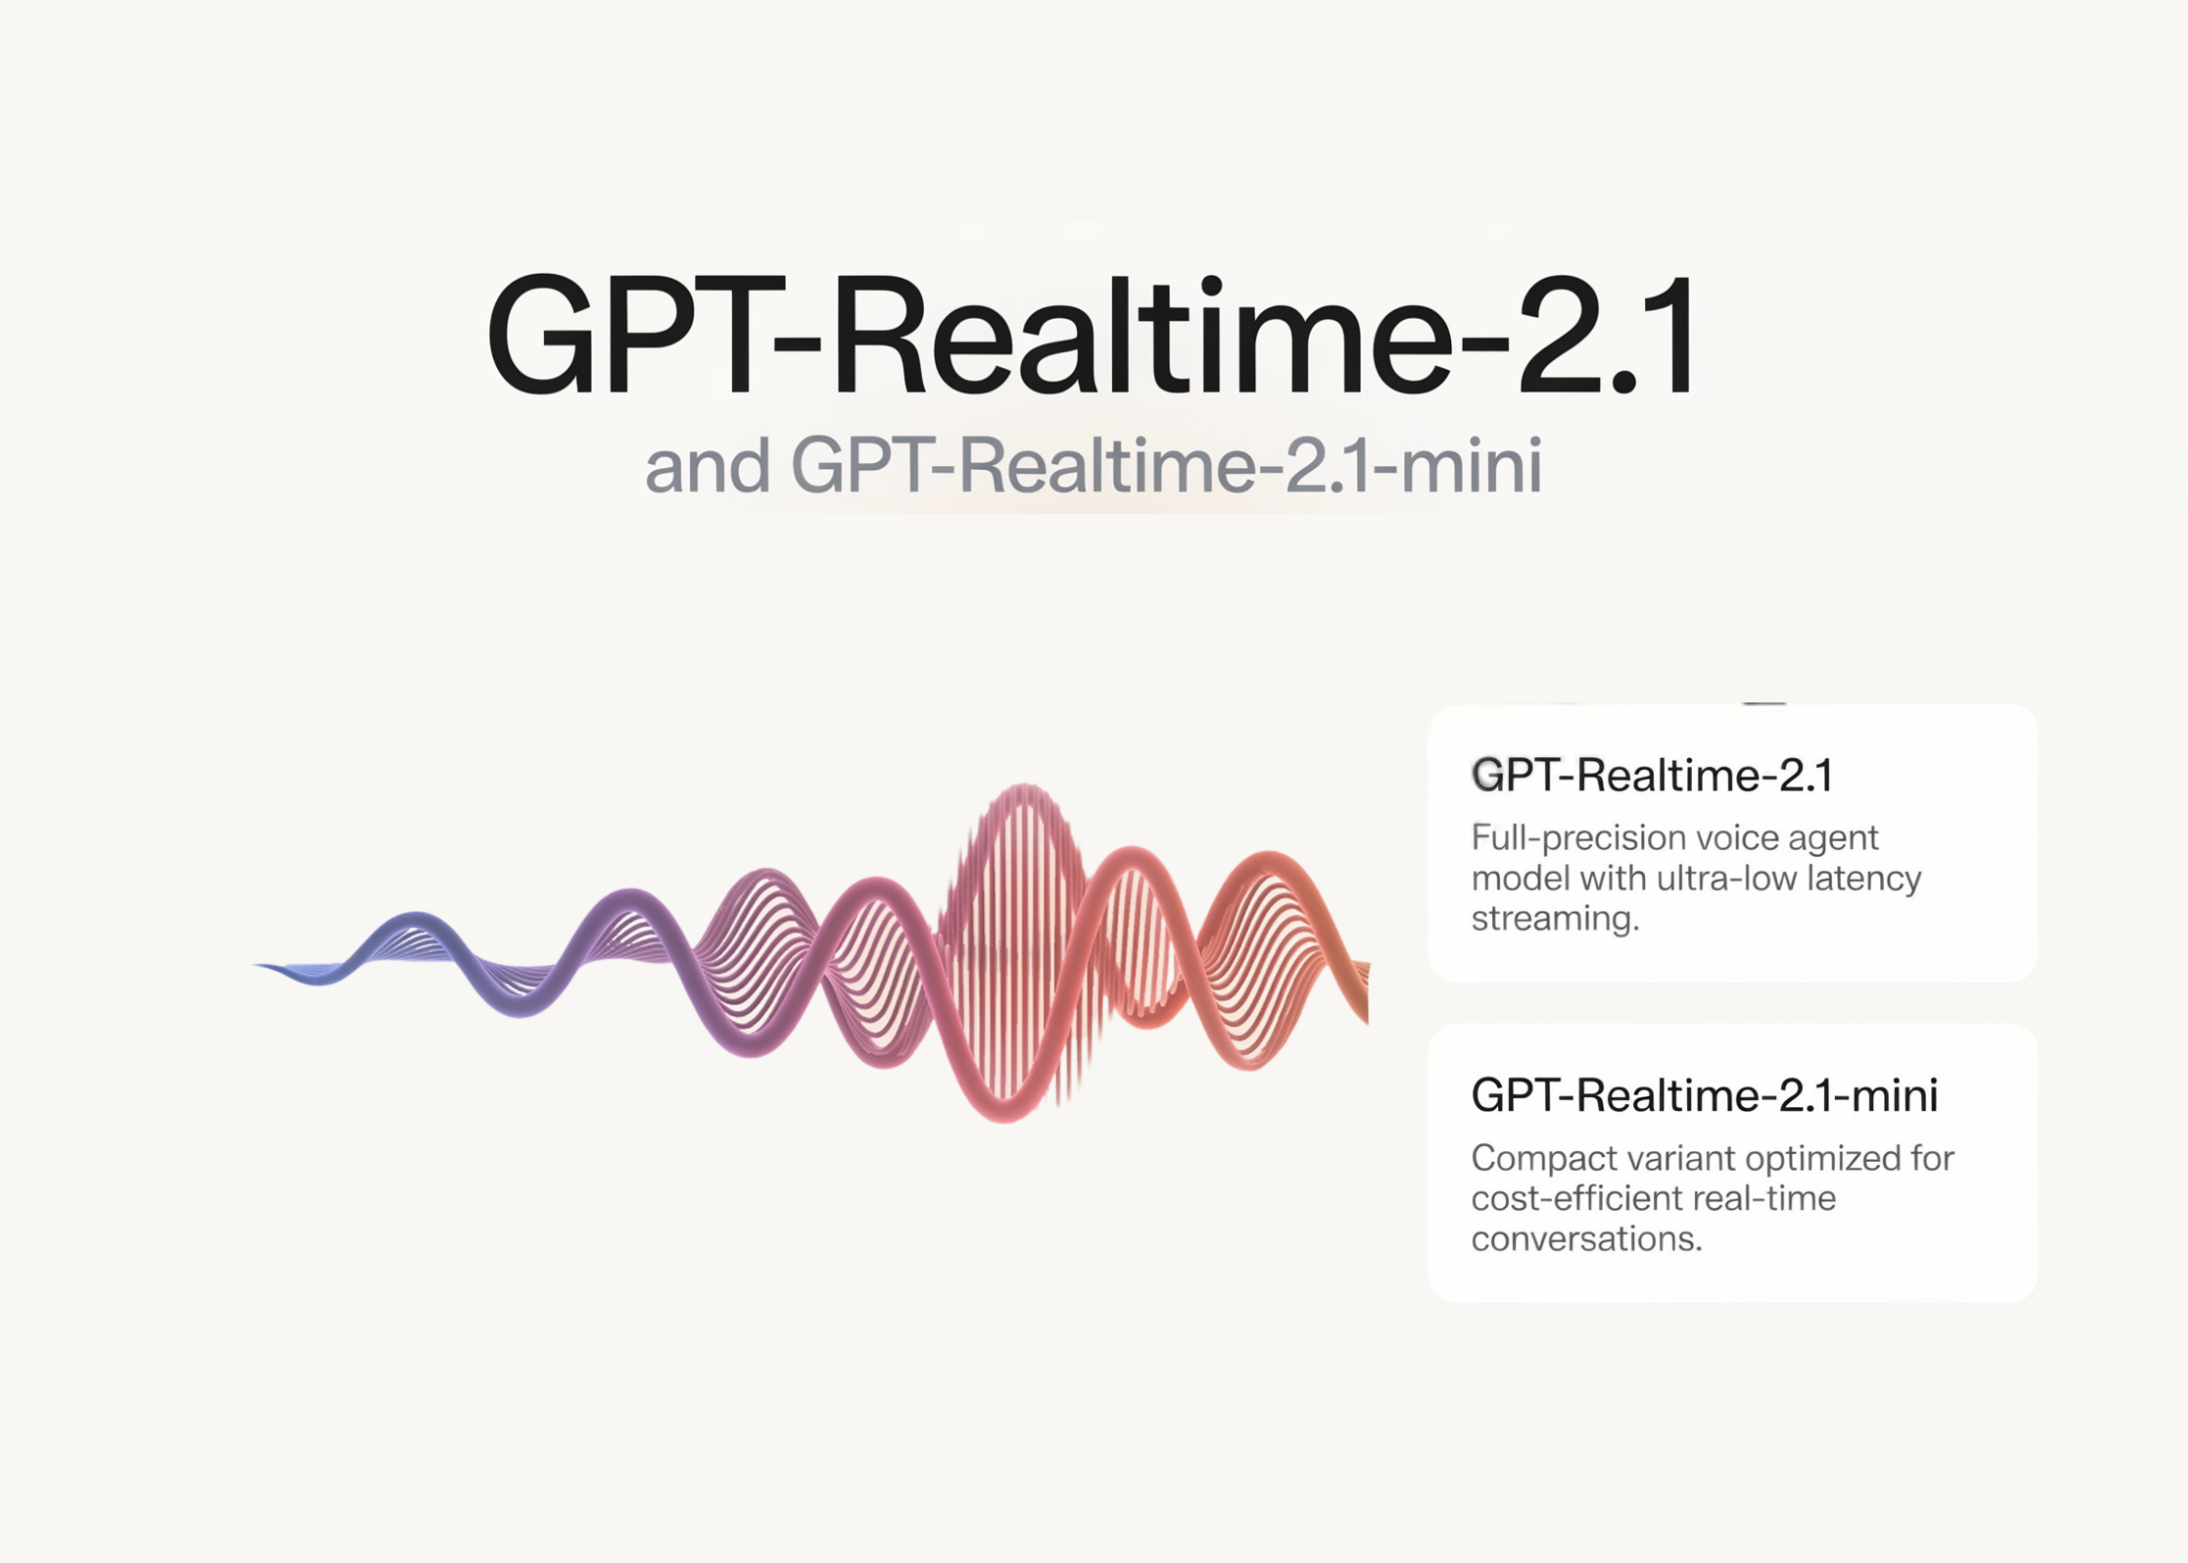
OpenAI Releases GPT-Realtime-2.1 and GPT-Realtime-2.1-mini for Low-Latency Voice Agents in the API
OpenAI has released two new Realtime models in its API. They are named gpt-realtime-2.1 and gpt-realtime-2.1-mini. Both target low-latency voice […]

Interfaze Ships diffusion-gemma-asr-small, an Open-Source Diffusion ASR Model Transcribing Six Languages via DiffusionGemma’s Parallel Denoising Decoder
Interfaze, a young YC’s startup, has open-sourced a new speech recognition model. It is called diffusion-gemma-asr-small. The model transcribes audio […]