Skip to content
Wednesday, September 9, 2026
The TechBriefs
  • Home
  • Technology
  • AI
  • Computers
  • Security
  • Internet
  • Press Releases
    • GlobeNewswire
    • PRNewswire
  • Contact

Category: Text to Audio

  • Home
  • Text to Audio
Lowest-Latency Inference APIs for Voice and Realtime Agents: A Time to First Token TTFT-First Benchmark
  • agentic AI
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Comparison
  • Editors Pick
  • Language Model
  • Staff
  • Technology
  • Text to Audio
  • Voice AI

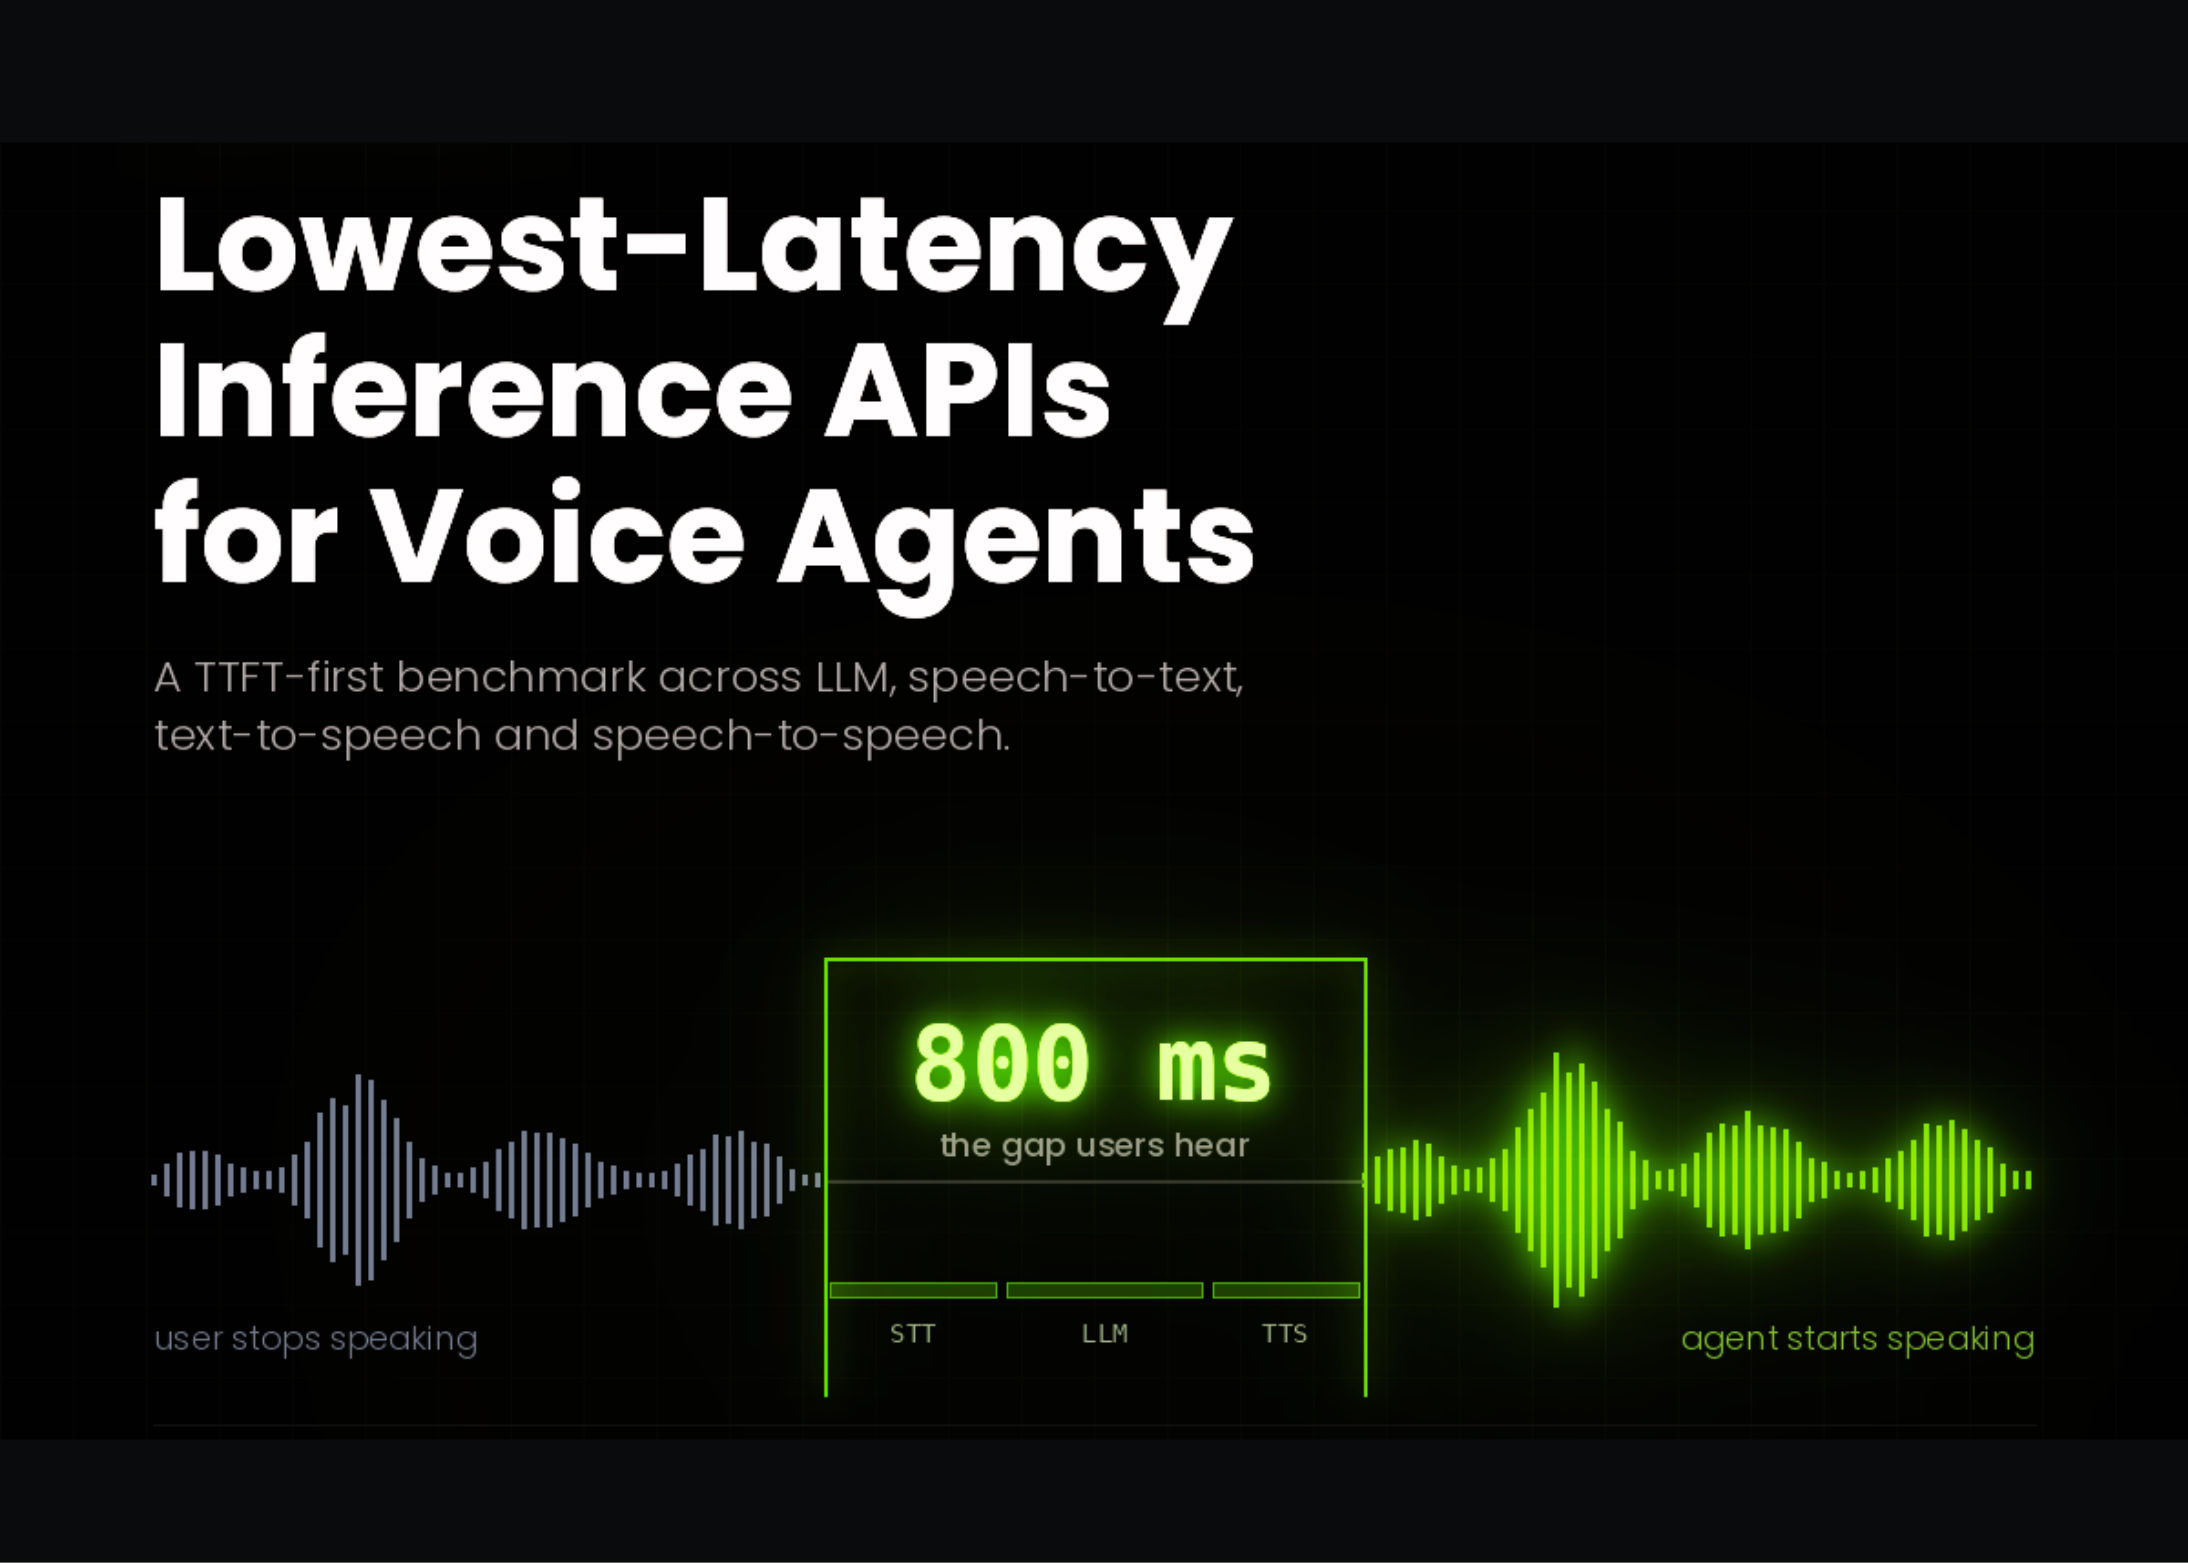
Lowest-Latency Inference APIs for Voice and Realtime Agents: A Time to First Token TTFT-First Benchmark

  • 0

Time to first token (TTFT) is the metric teams use to pick an inference API for voice. It is also […]

Best Text-to-Speech TTS Models in 2026: A Benchmark-Based Comparison
  • agentic AI
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • Staff
  • Technology
  • Text to Audio
  • Top
  • TTS
  • Voice AI

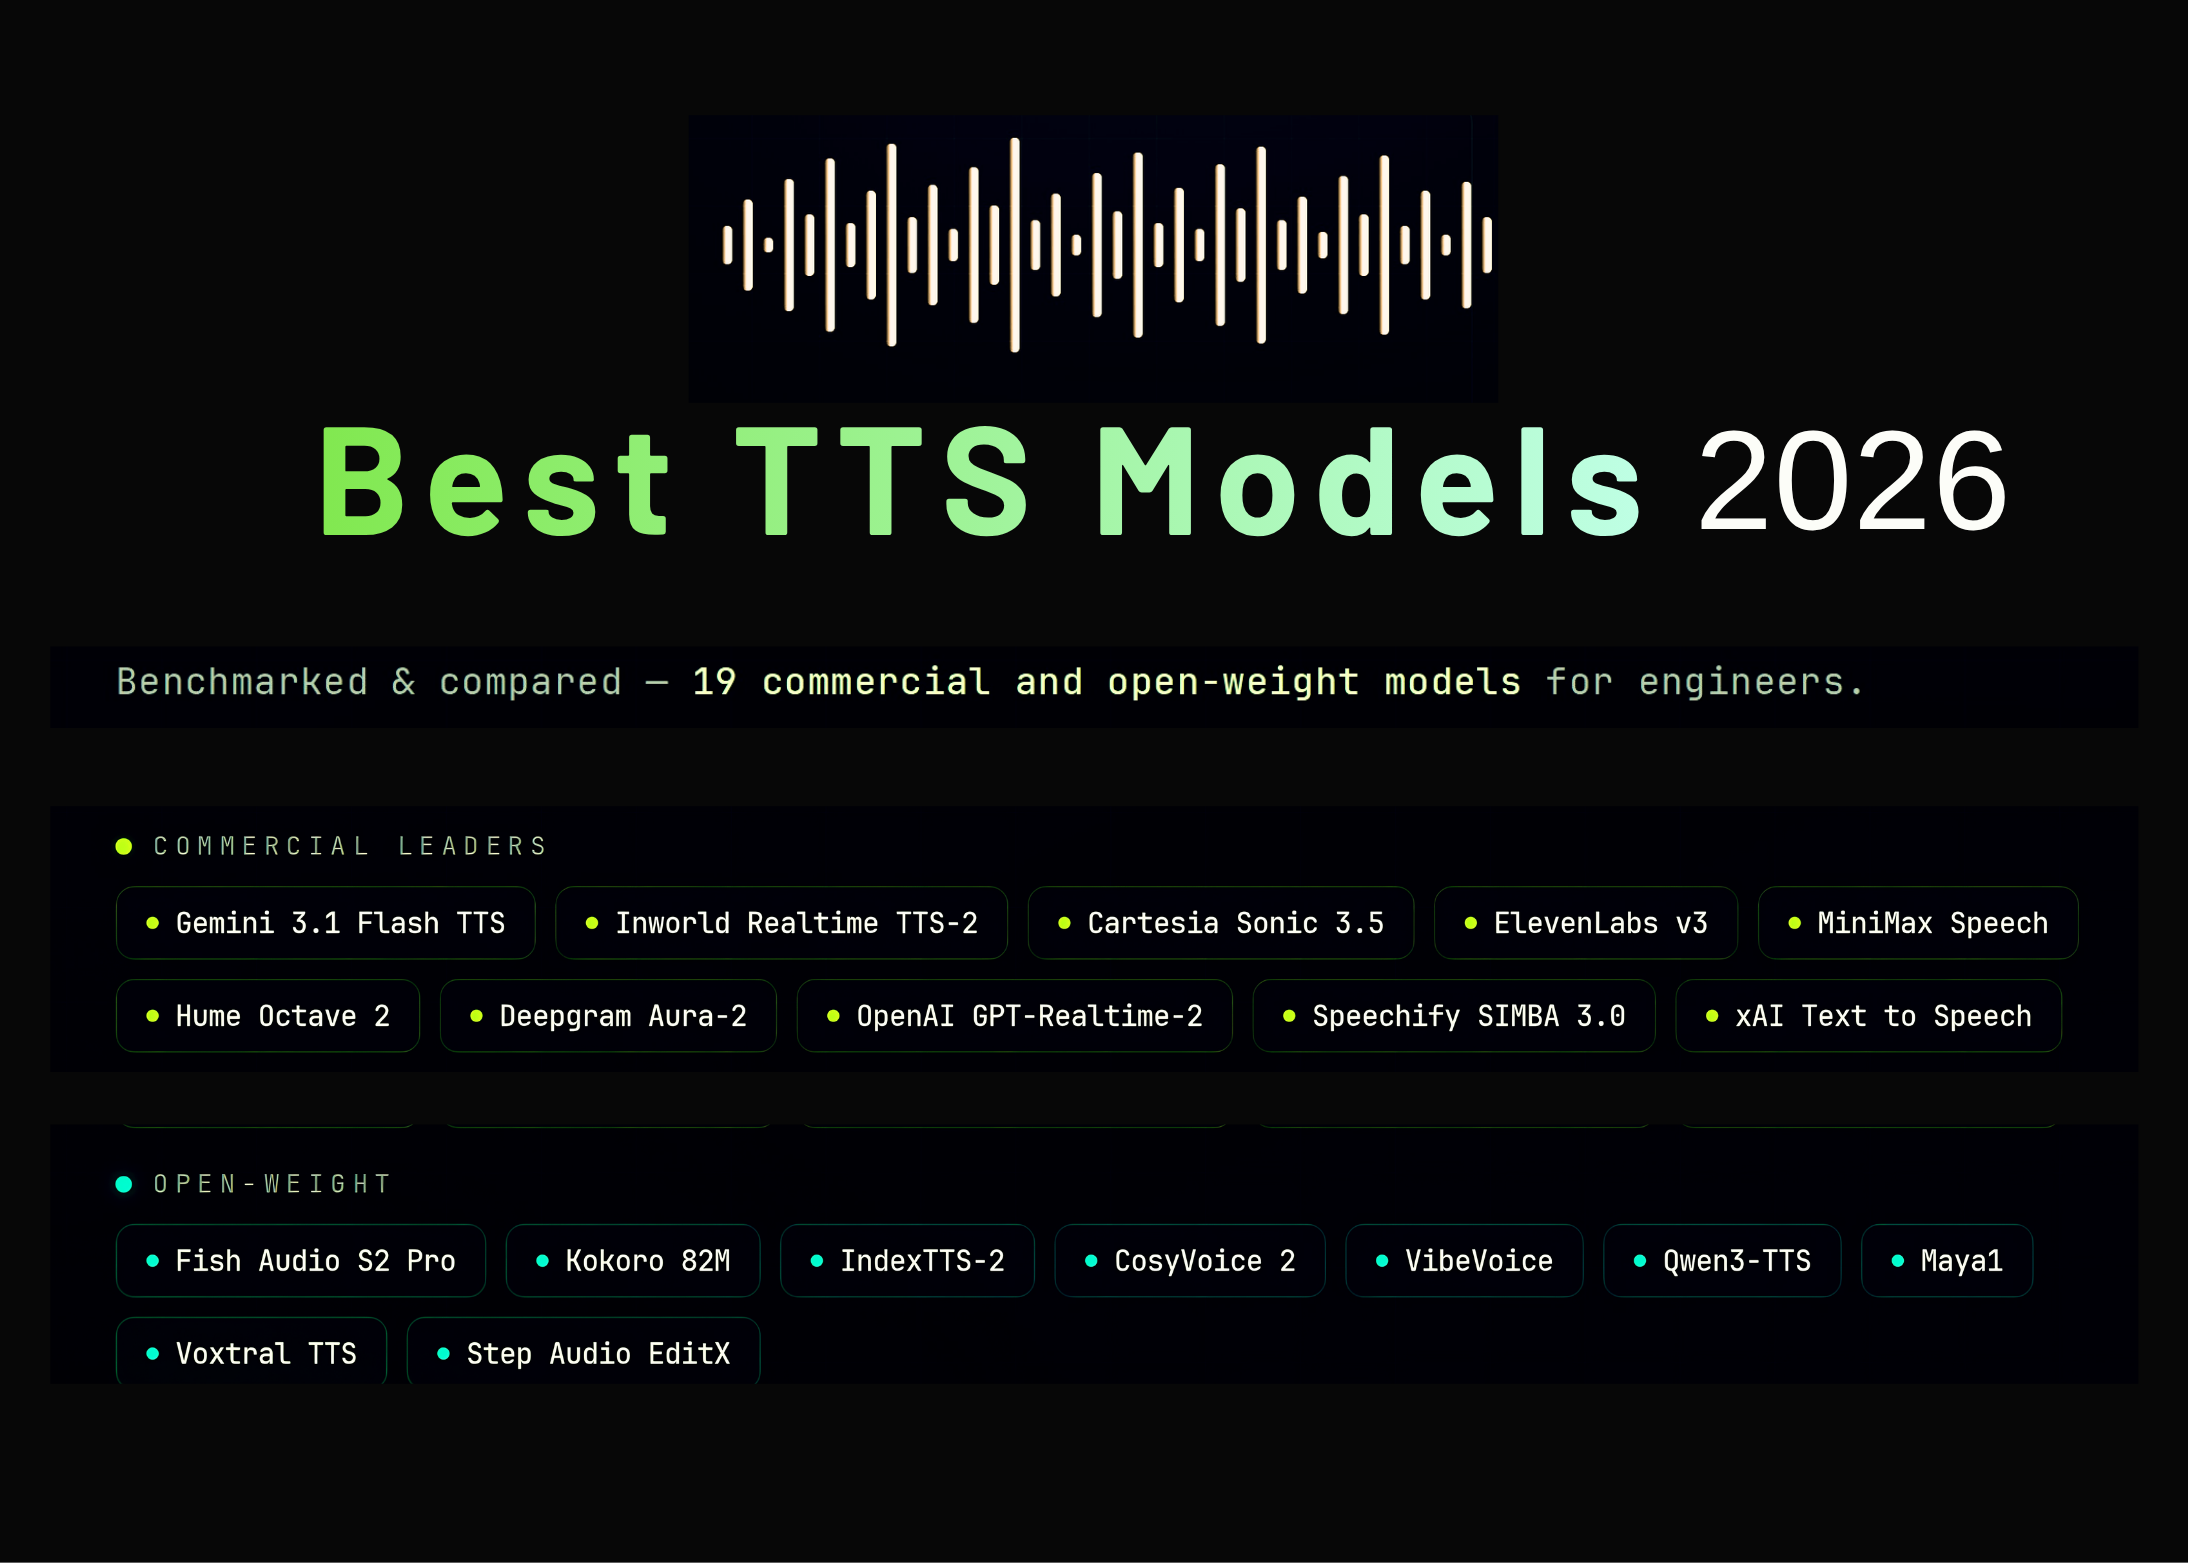
Best Text-to-Speech TTS Models in 2026: A Benchmark-Based Comparison

  • 0

Text-to-speech TTS moved fast over the past year. The line between synthetic and human speech narrowed. Latency dropped below 100 […]
Supertone Releases Supertonic v3: On-Device Text-to-Speech Model with 31-Language Support, Fewer Reading Failures, and Expression Tags
  • agentic AI
  • AI
  • AI Shorts
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Software Engineering
  • Staff
  • Tech News
  • Technology
  • Text to Audio
  • Voice AI

Supertone Releases Supertonic v3: On-Device Text-to-Speech Model with 31-Language Support, Fewer Reading Failures, and Expression Tags

  • 0

Supertone released Supertonic 3, the third generation of its on-device, ONNX-based text-to-speech system. Supertonic 3 ships with 31-language support, improved […]
Mistral AI Releases Voxtral TTS: A 4B Open-Weight Streaming Speech Model for Low-Latency Multilingual Voice Generation
  • agentic AI
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Staff
  • Technology
  • Text to Audio
  • TTS
  • Voice AI

Mistral AI Releases Voxtral TTS: A 4B Open-Weight Streaming Speech Model for Low-Latency Multilingual Voice Generation

  • 0

Mistral AI has released Voxtral TTS, an open-weight text-to-speech model that marks the company’s first major move into audio generation. […]

Google DeepMind Releases Lyria 3: An Advanced Music Generation AI Model that Turns Photos and Text into Custom Tracks with Included Lyrics and Vocals
  • agentic AI
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Staff
  • Technology
  • Text to Audio
  • TTS
  • Voice AI

Google DeepMind Releases Lyria 3: An Advanced Music Generation AI Model that Turns Photos and Text into Custom Tracks with Included Lyrics and Vocals

  • 0

Google DeepMind is pushing the boundaries of generative AI again. This time, the focus is not on text or images. […]

  • Privacy Policy
  • Terms of use
Theme: Terminal News By Adore Themes.