
Soniox has released Soniox STT v6, the latest generation of its speech-to-text API. Soniox STT v6 is a speech-to-text model […]
Category: Audio Language Model
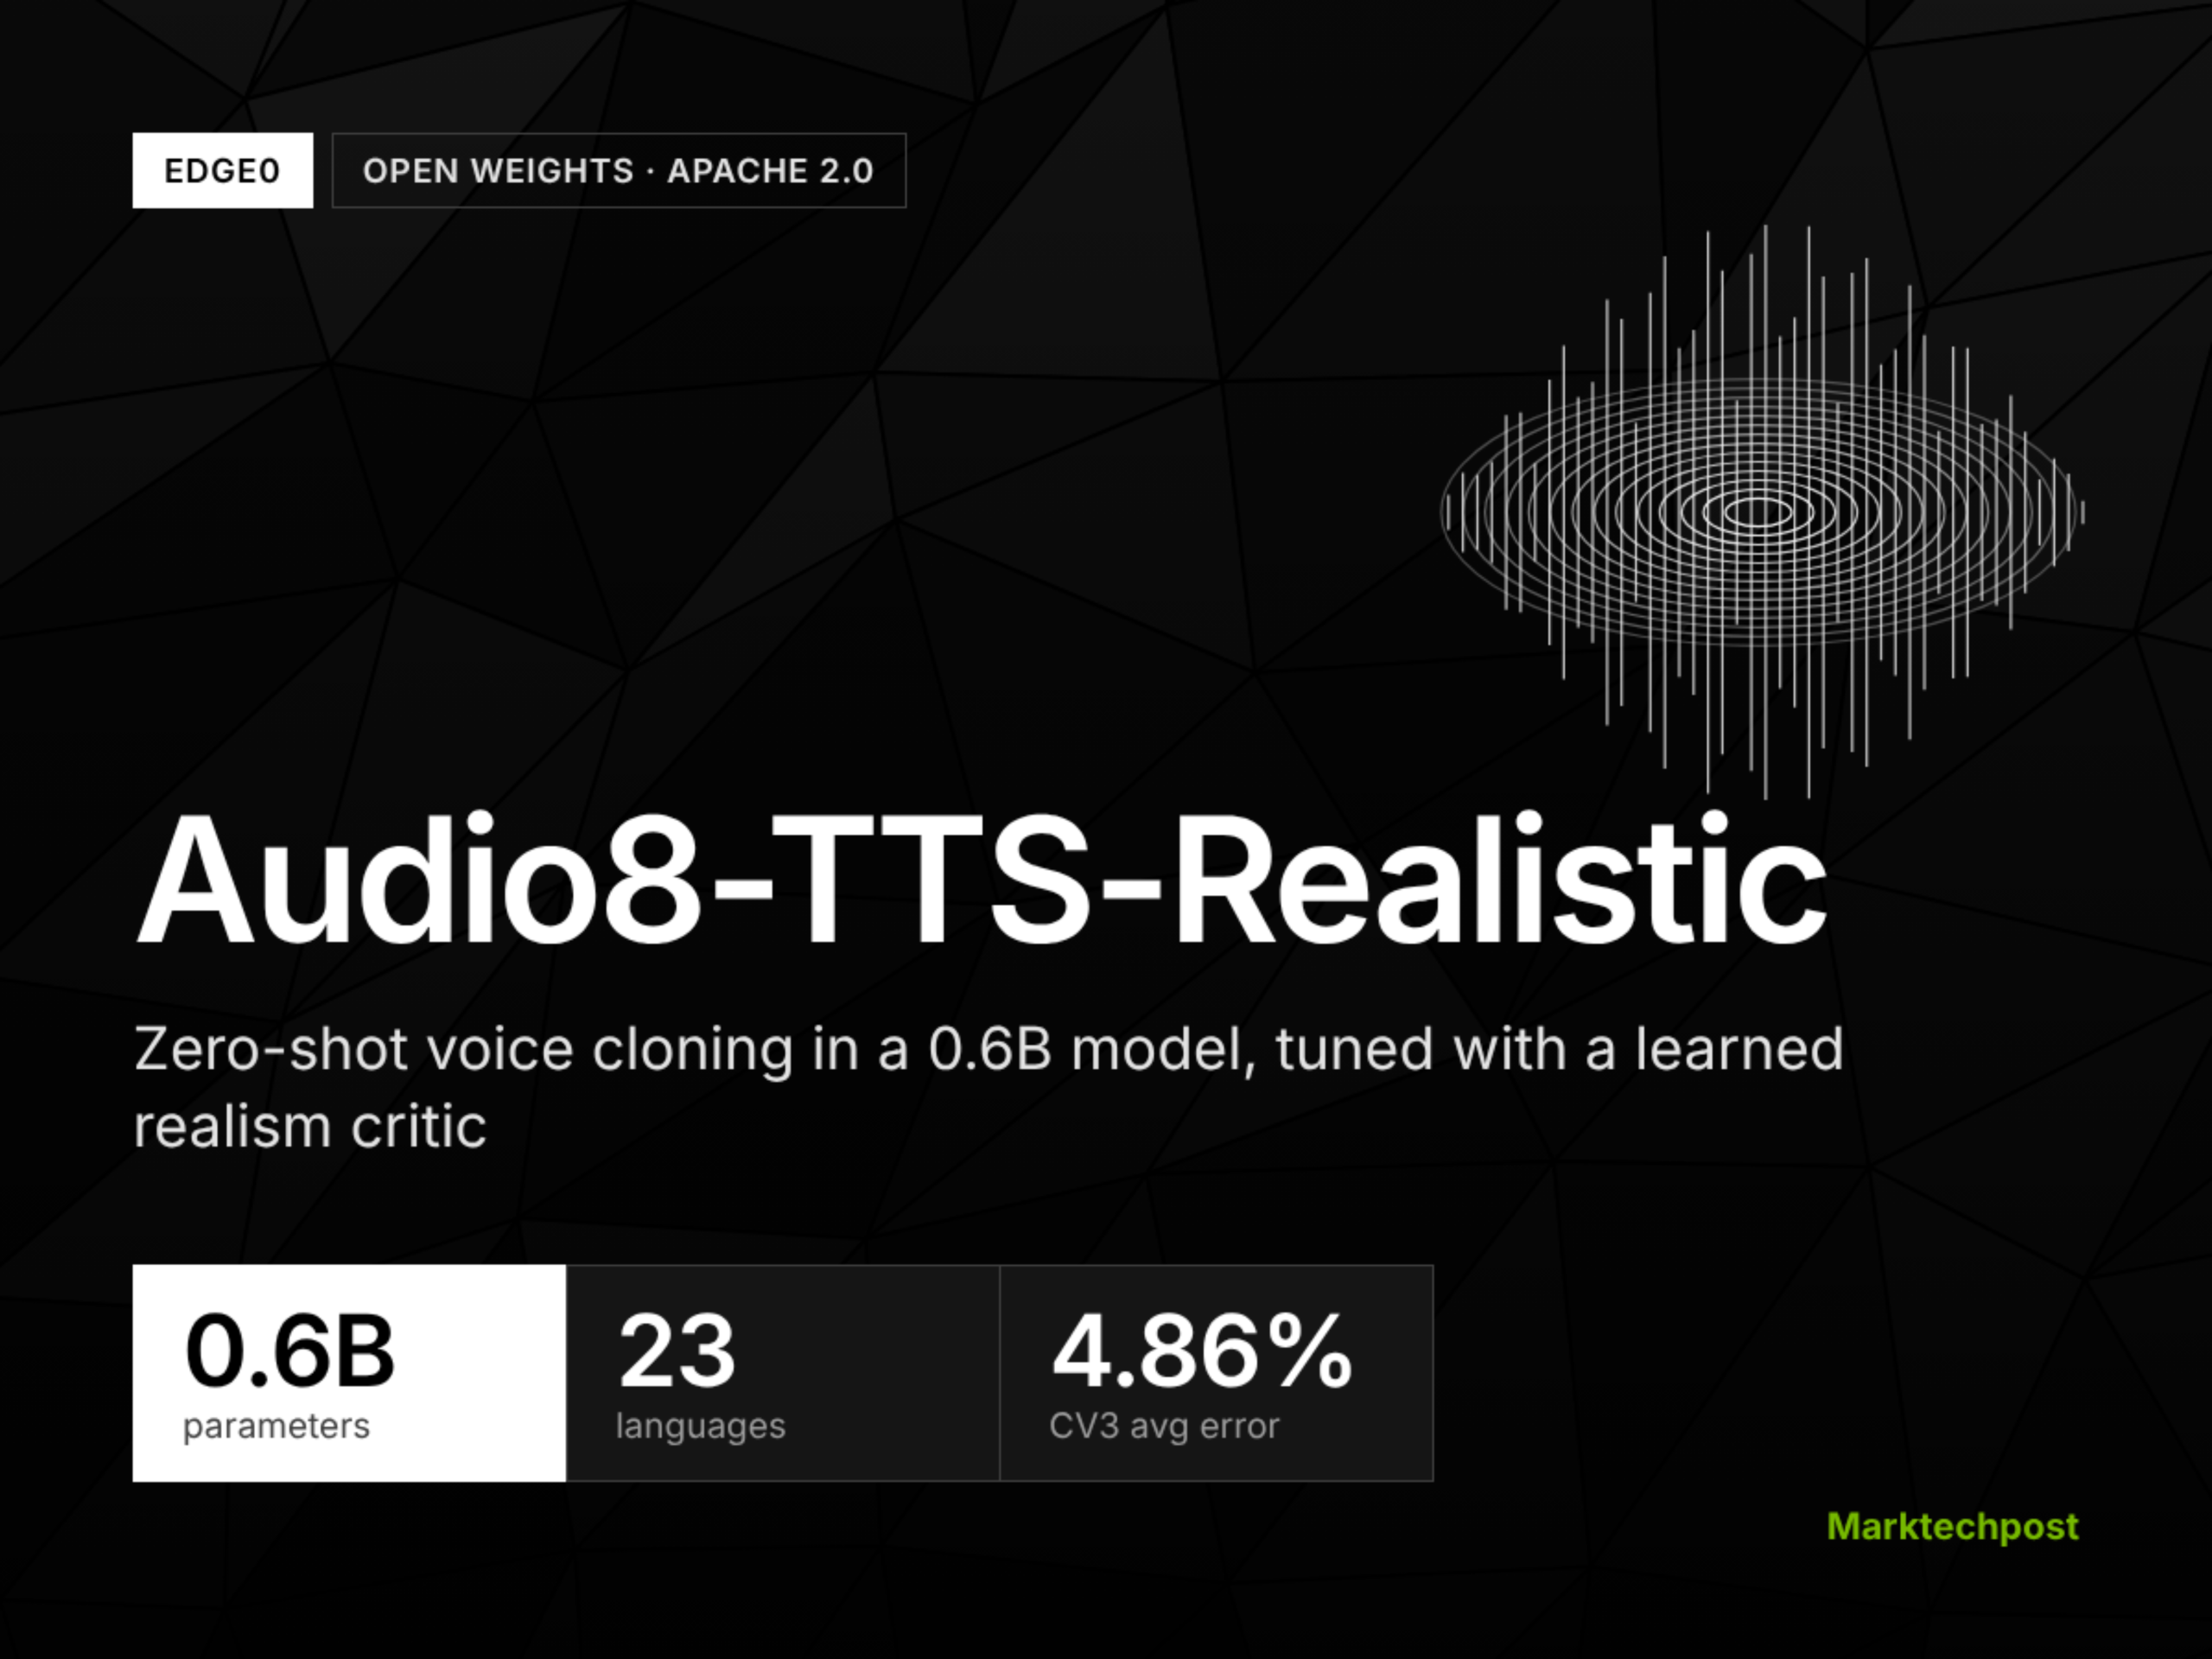
Edge0 Releases Audio8-TTS-Realistic, a 0.6B Voice Cloning TTS Model
Edge0 has released Audio8-TTS-Realistic, an open-weight text-to-speech model for zero-shot voice cloning. Audio8-TTS-Realistic is a 0.6B-parameter model that clones a […]
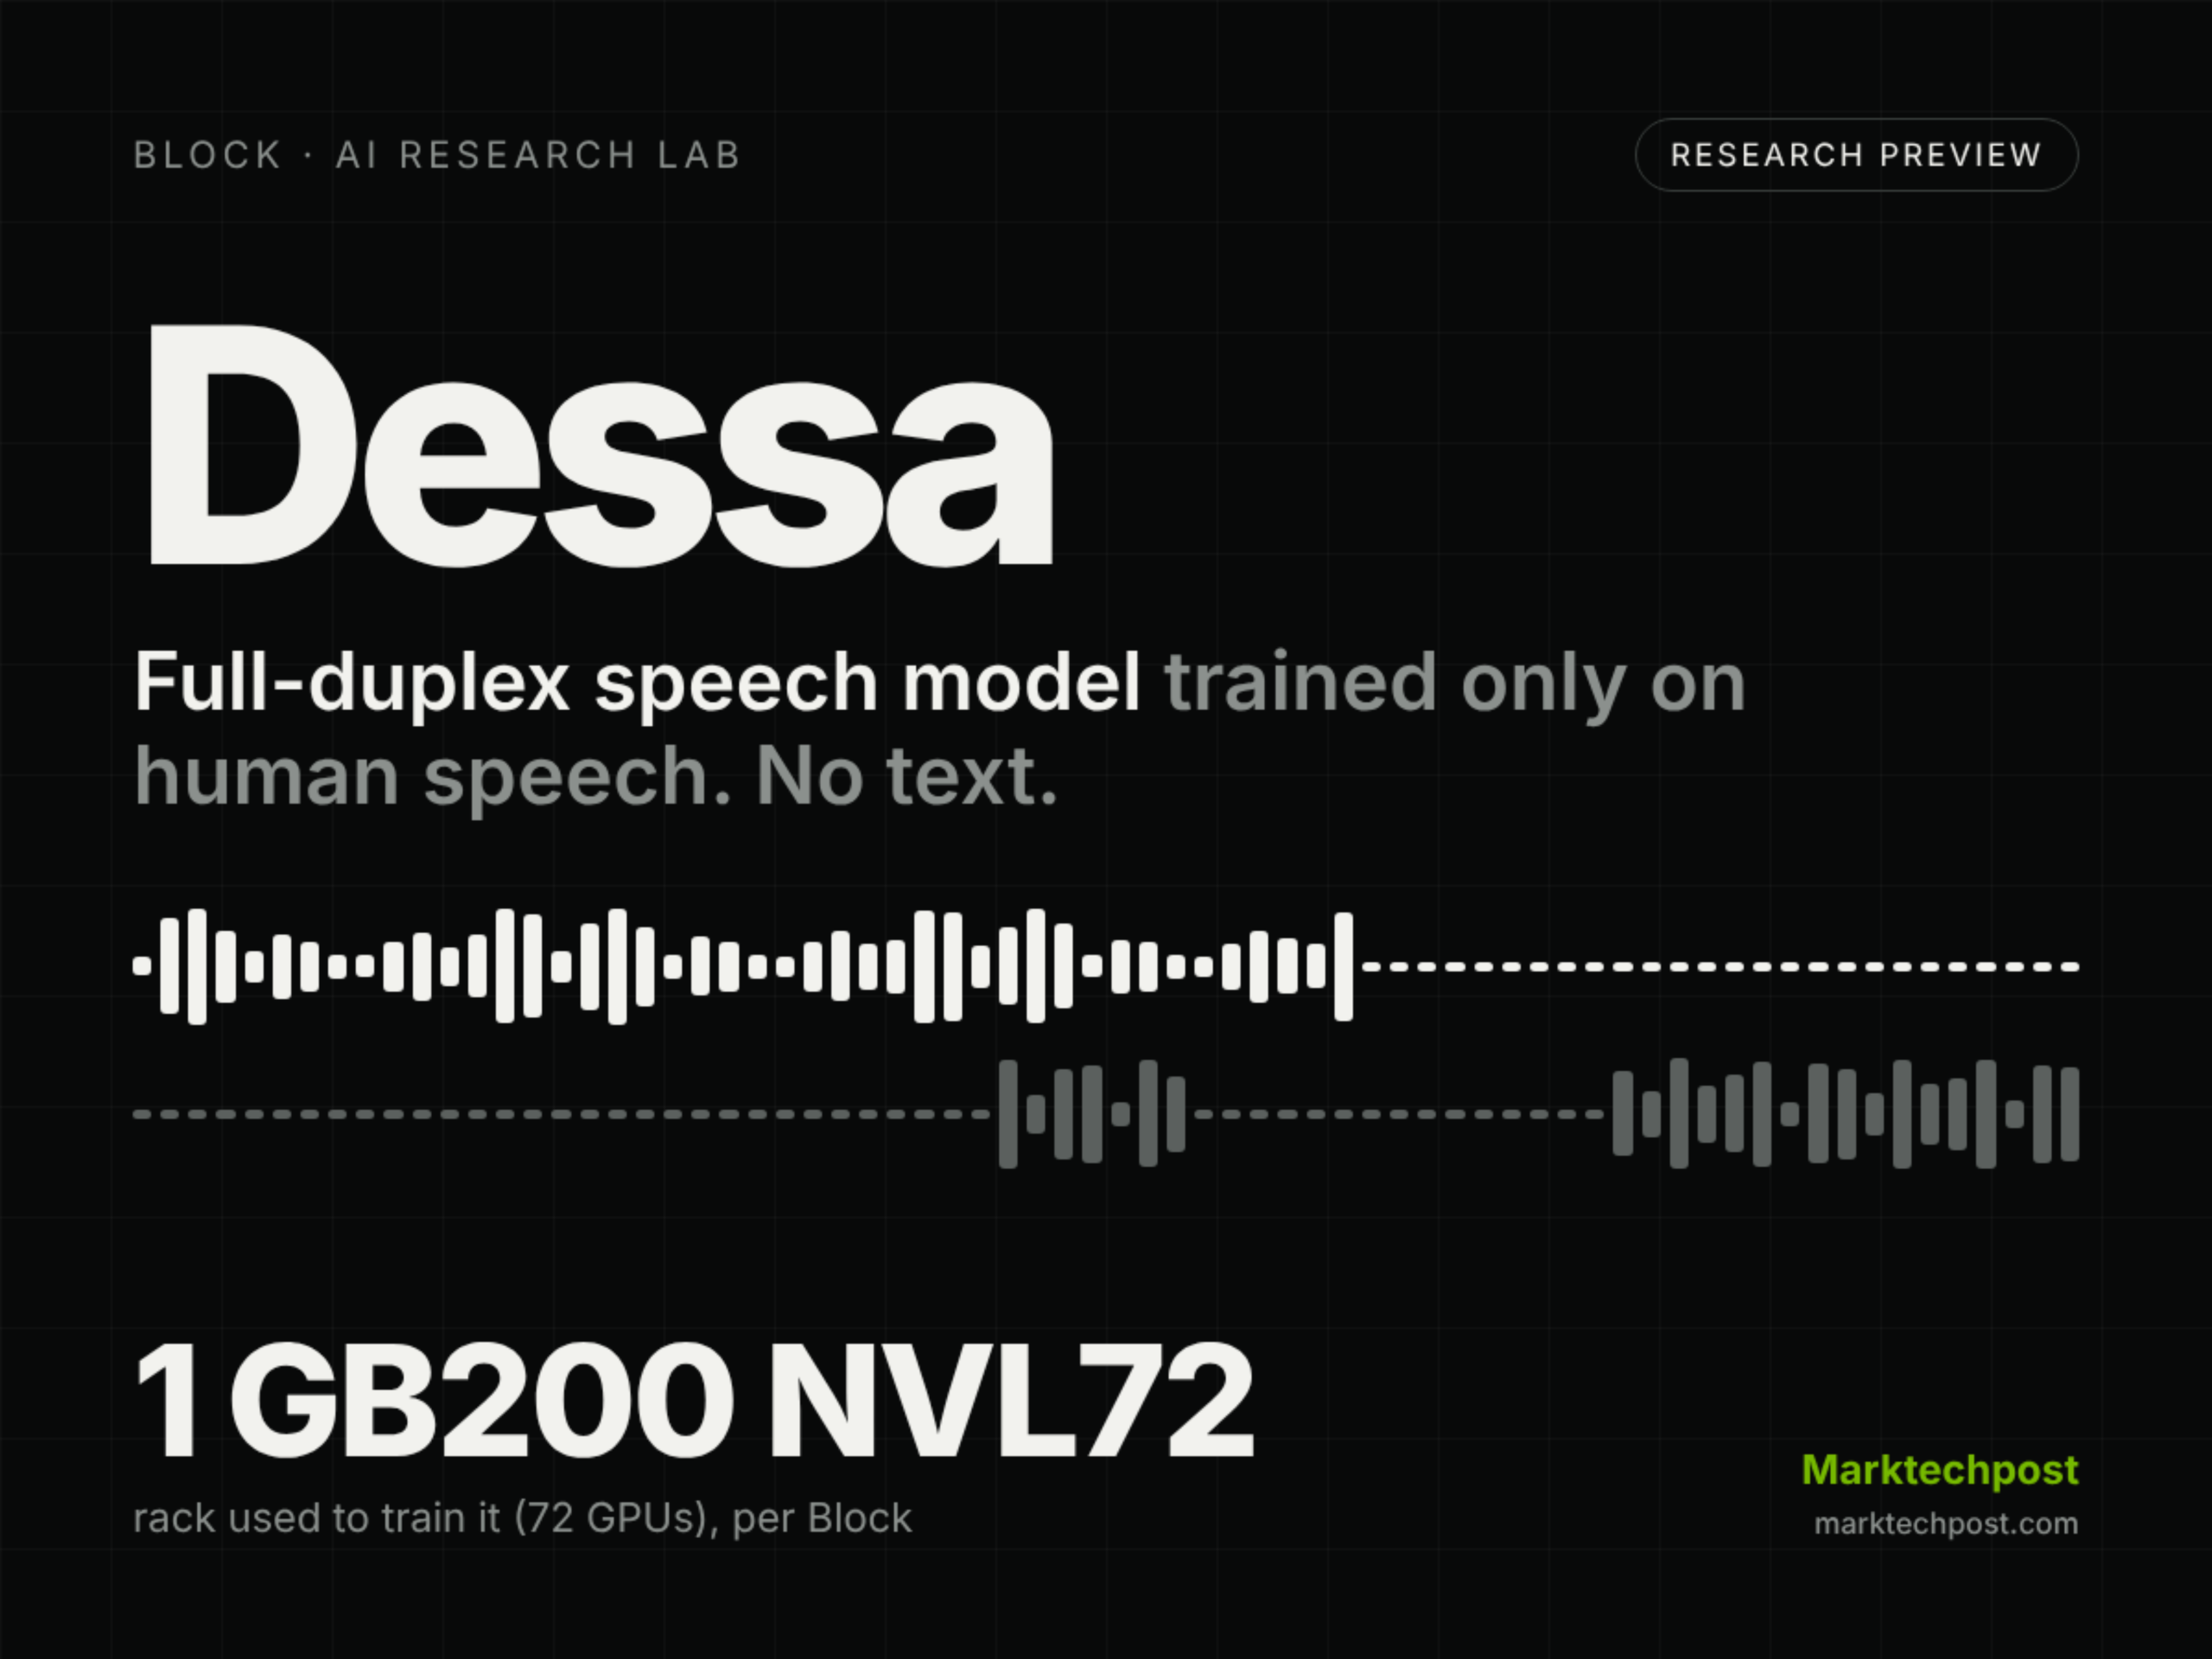
Block Unveils Dessa, a Full-Duplex Speech Model Trained Only on Speech
Block’s AI research lab has released Dessa, a full-duplex speech model trained only on human conversation. Block announced it on […]
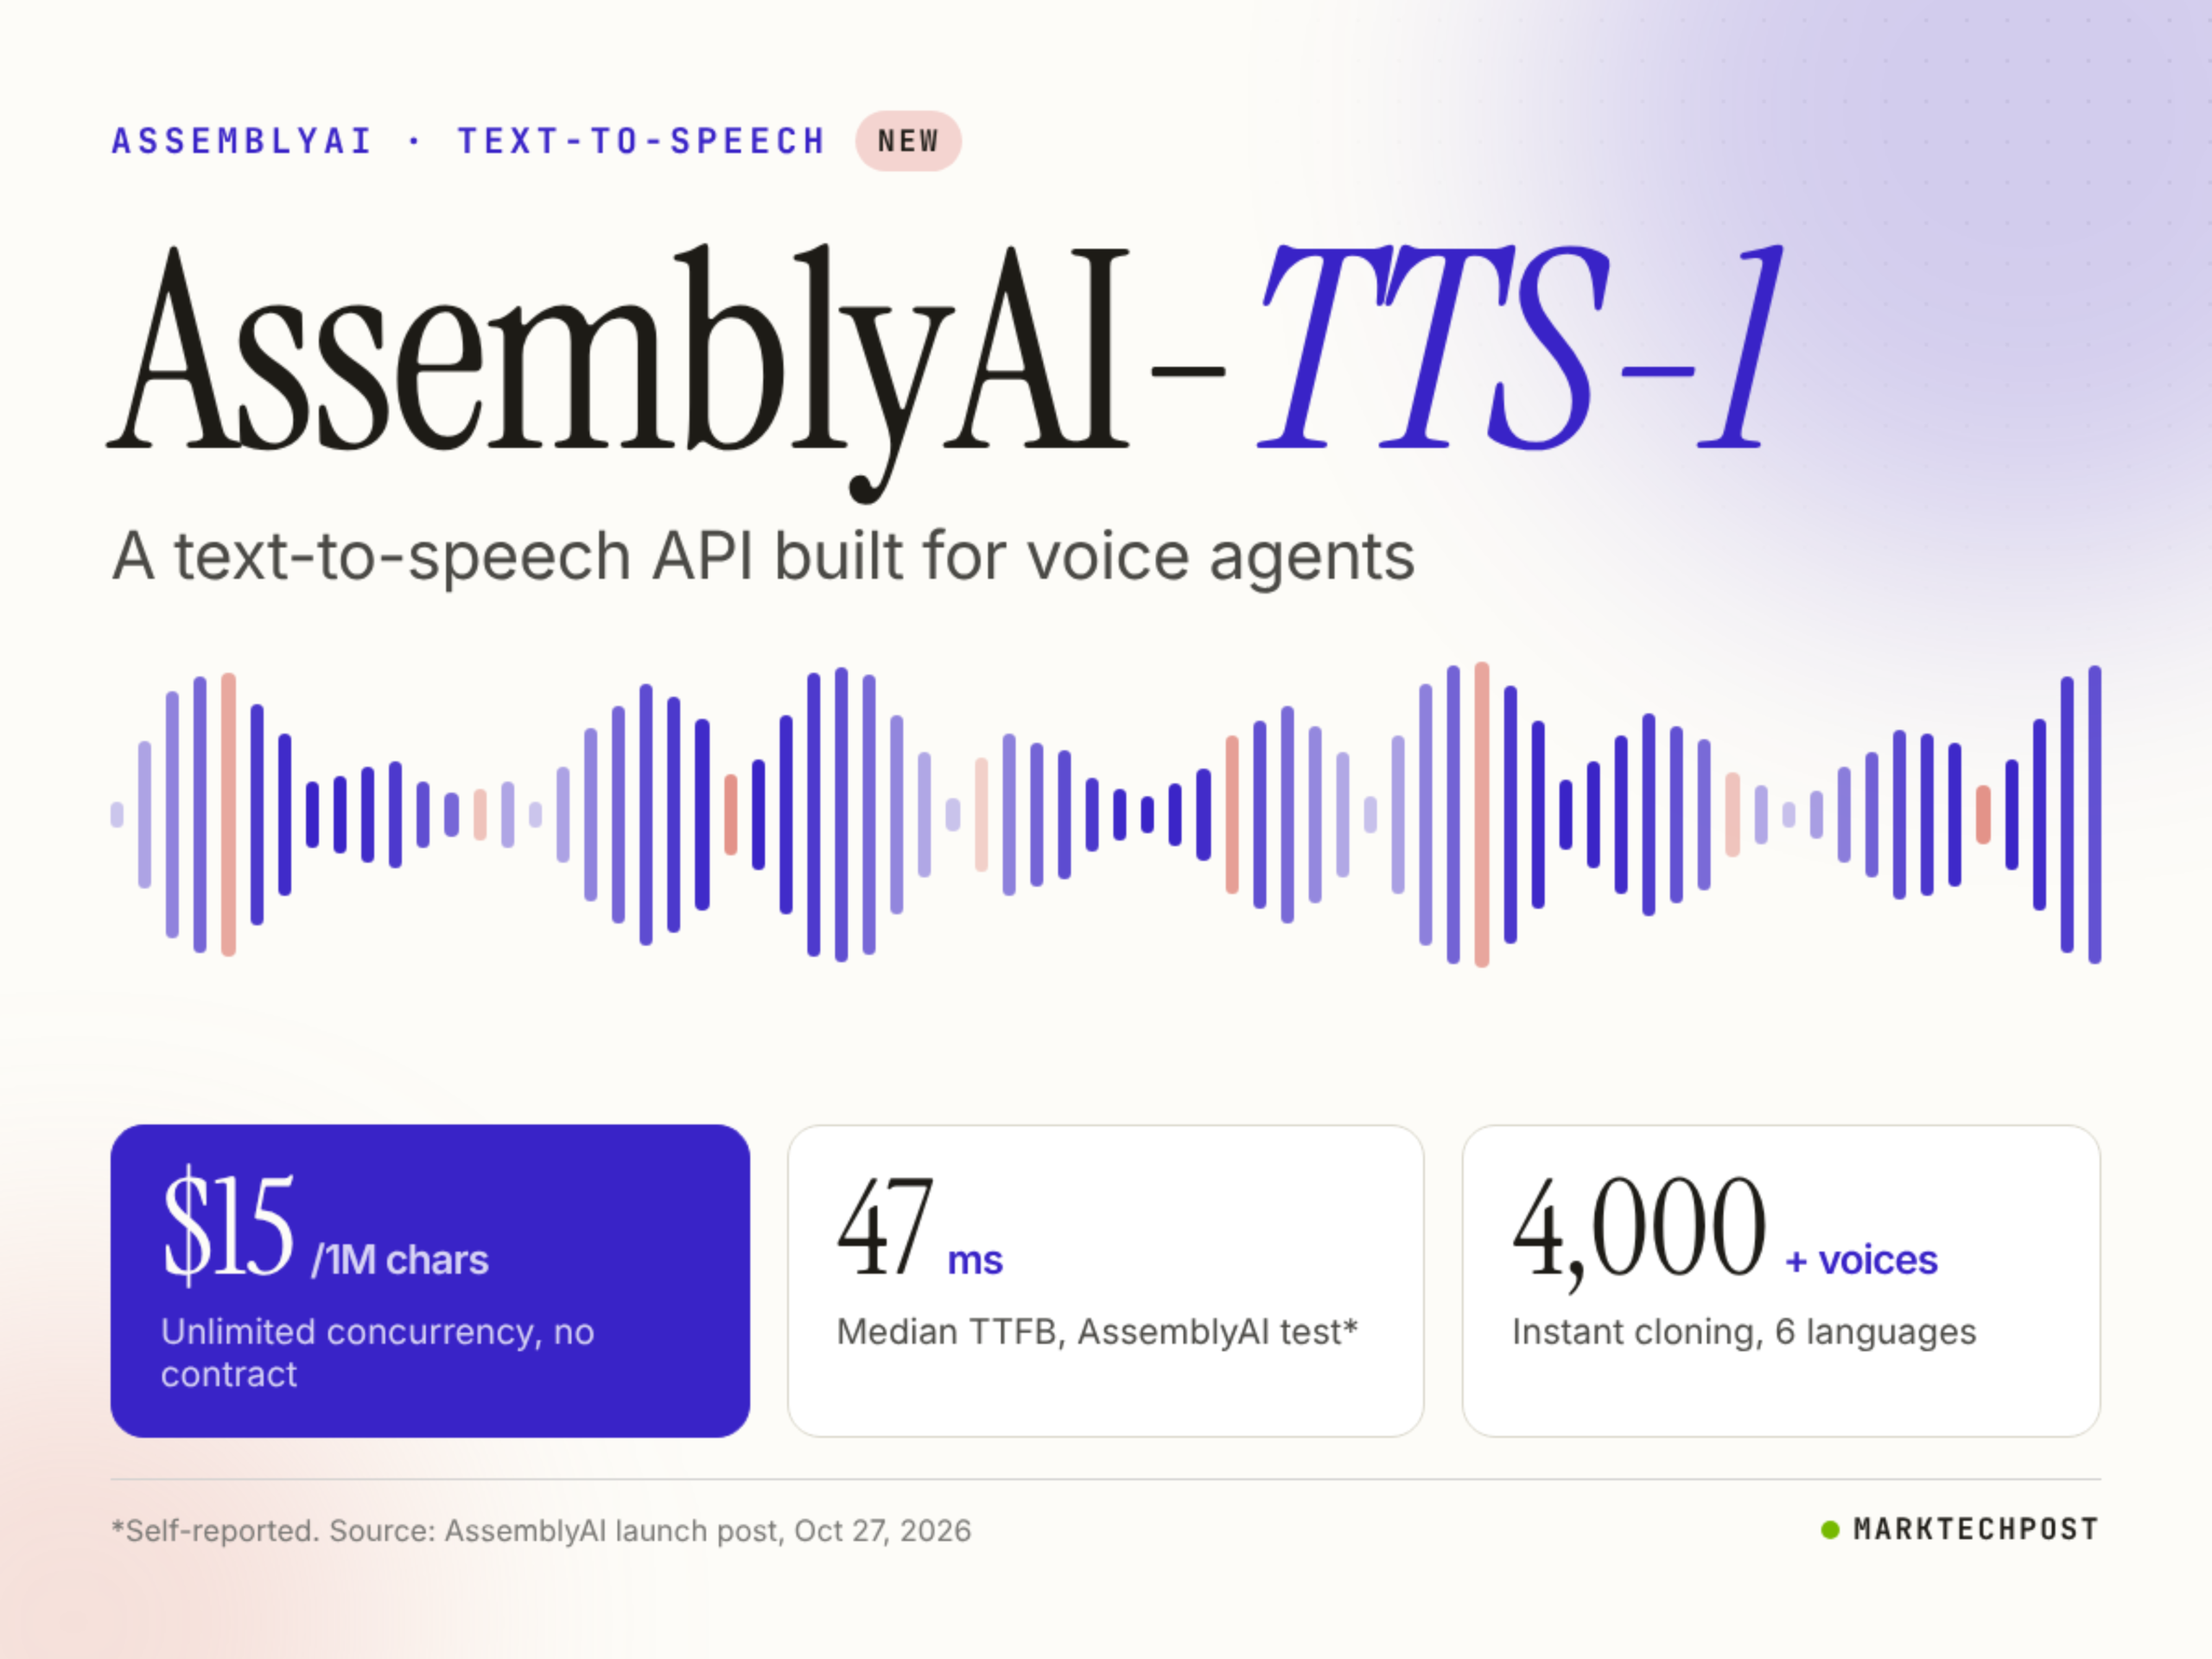
AssemblyAI Ships AssemblyAI-TTS-1: A $15 per 1M Character Text-to-Speech API for Voice Agents
AssemblyAI has released AssemblyAI-TTS-1, its first text-to-speech model, now generally available. The AssemblyAI-TTS-1 text-to-speech API targets voice agents running on […]
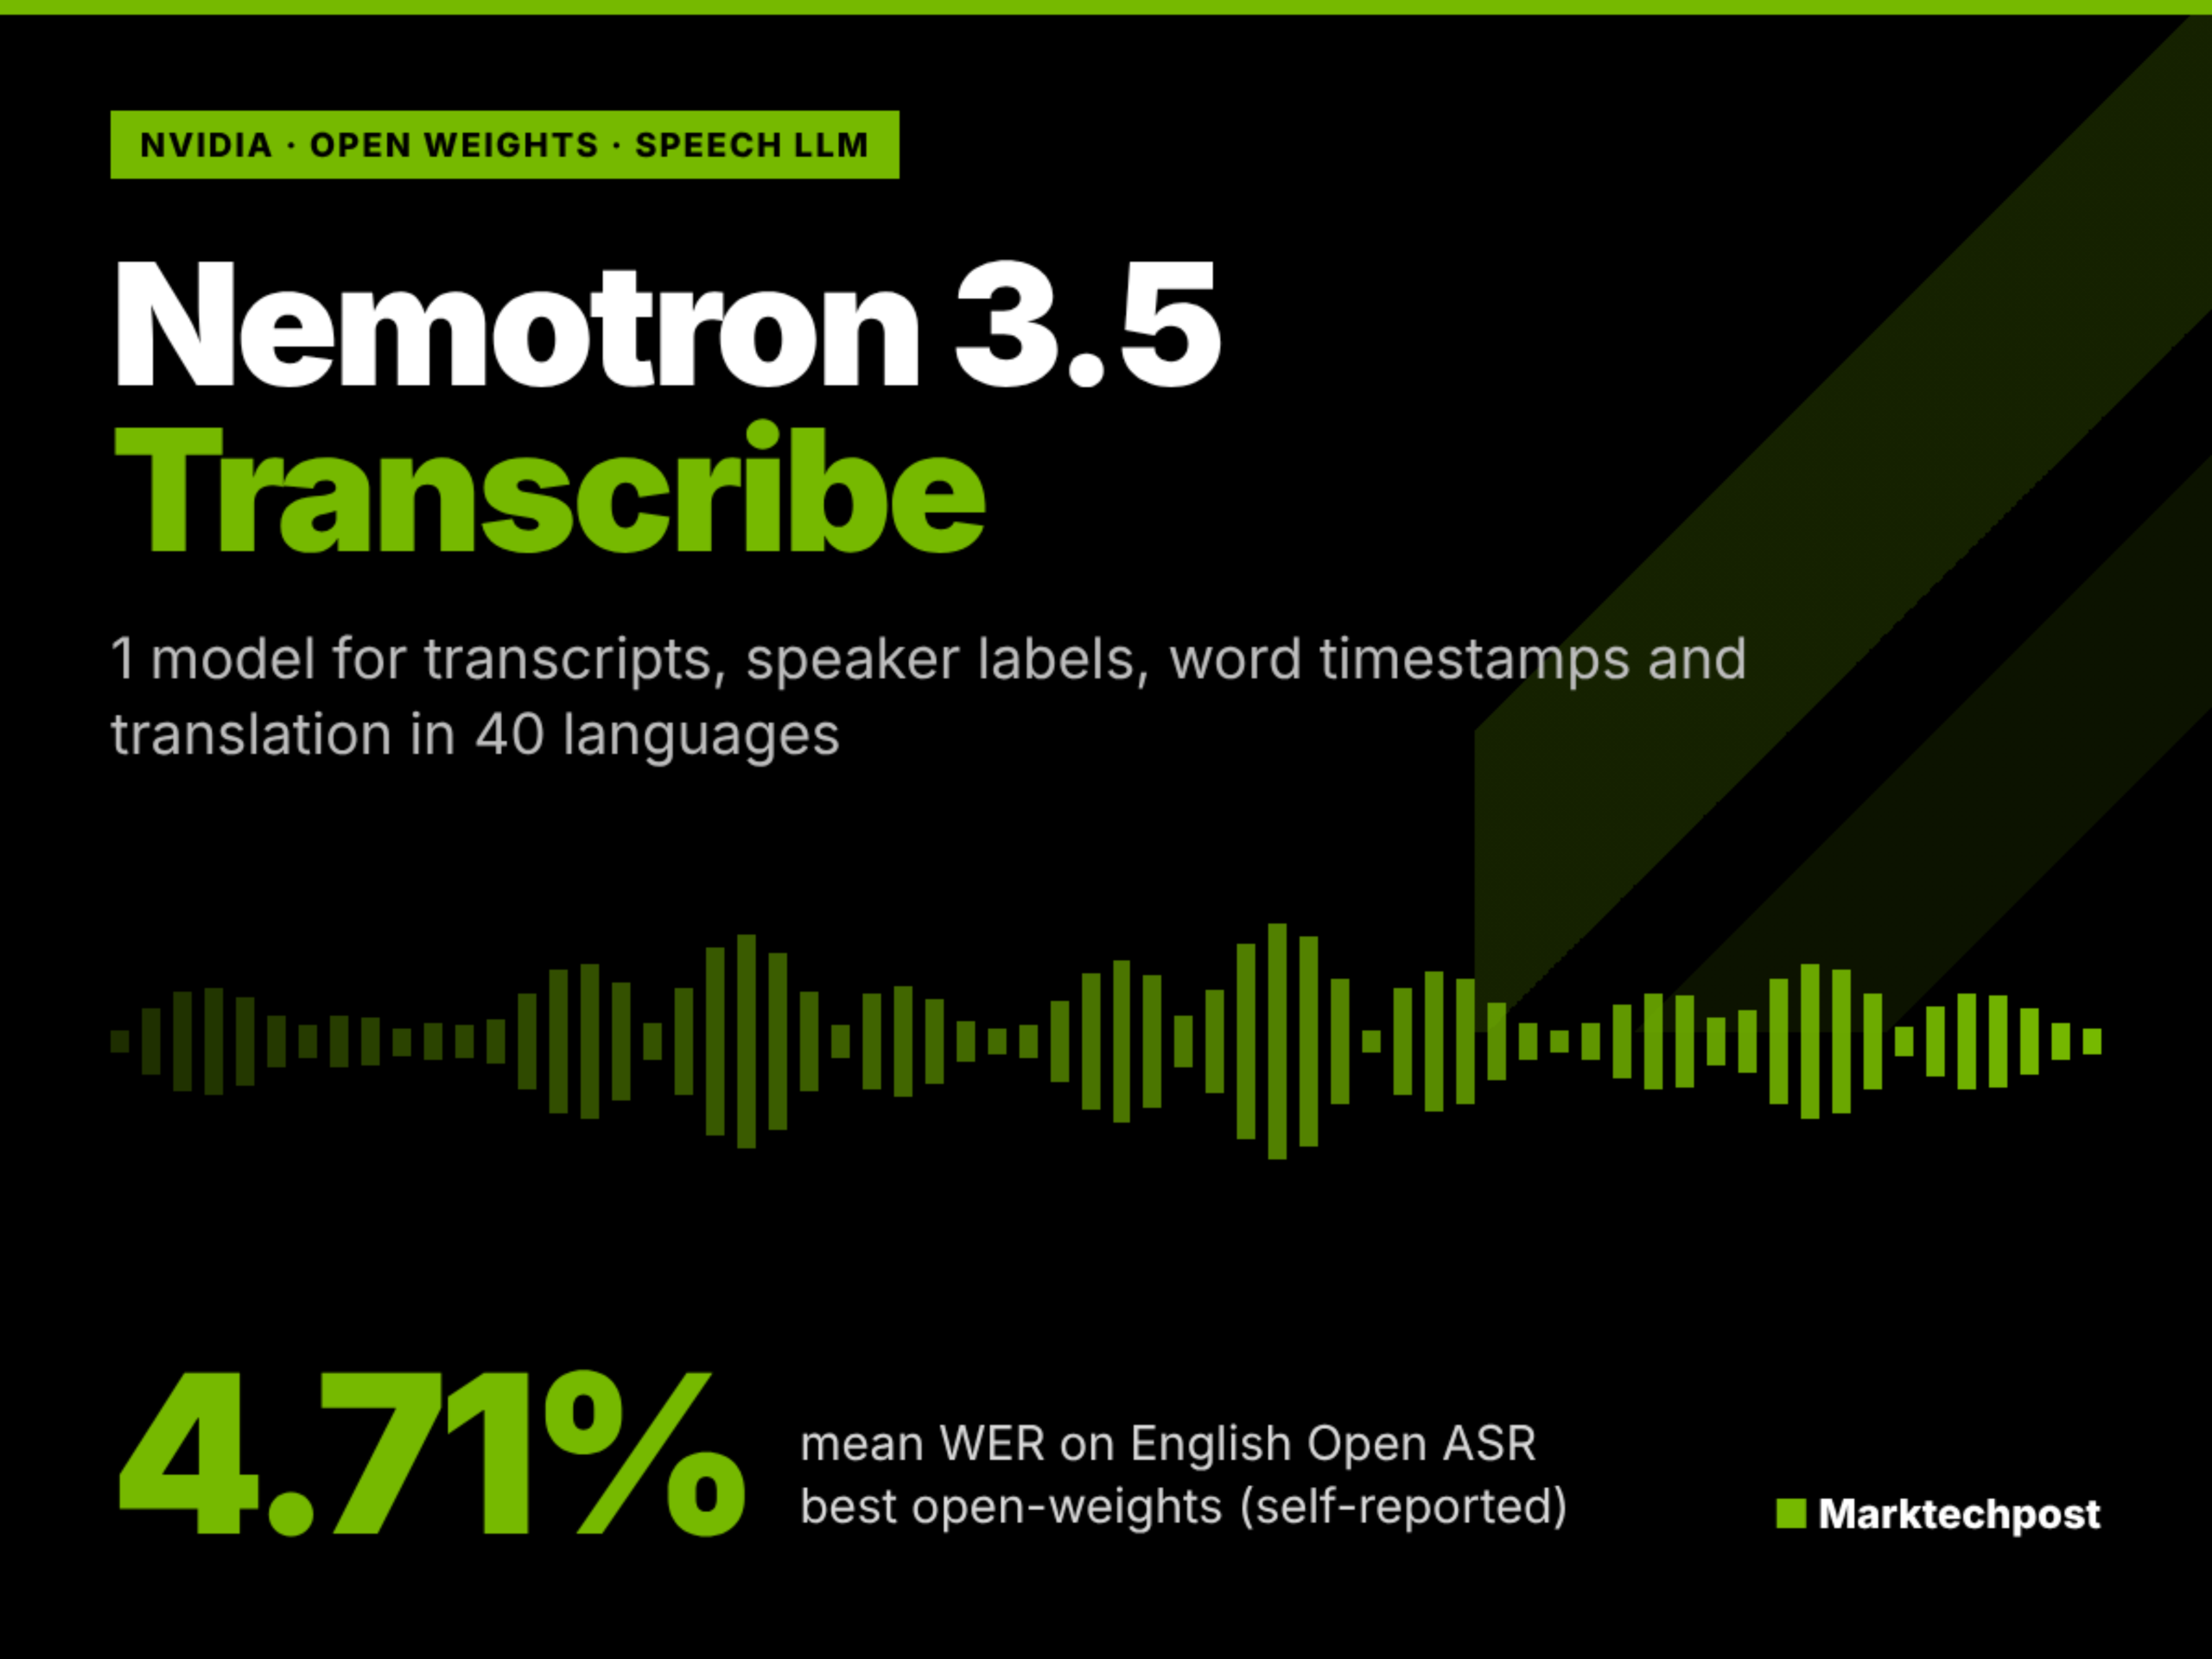
NVIDIA Releases Nemotron 3.5 Transcribe: An Open 30B MoE Model for 40-Language Transcription with ~4B Active Parameters
NVIDIA has released Nemotron 3.5 Transcribe, an open-weights speech LLM built for transcription. One model handles 40 languages and recordings […]
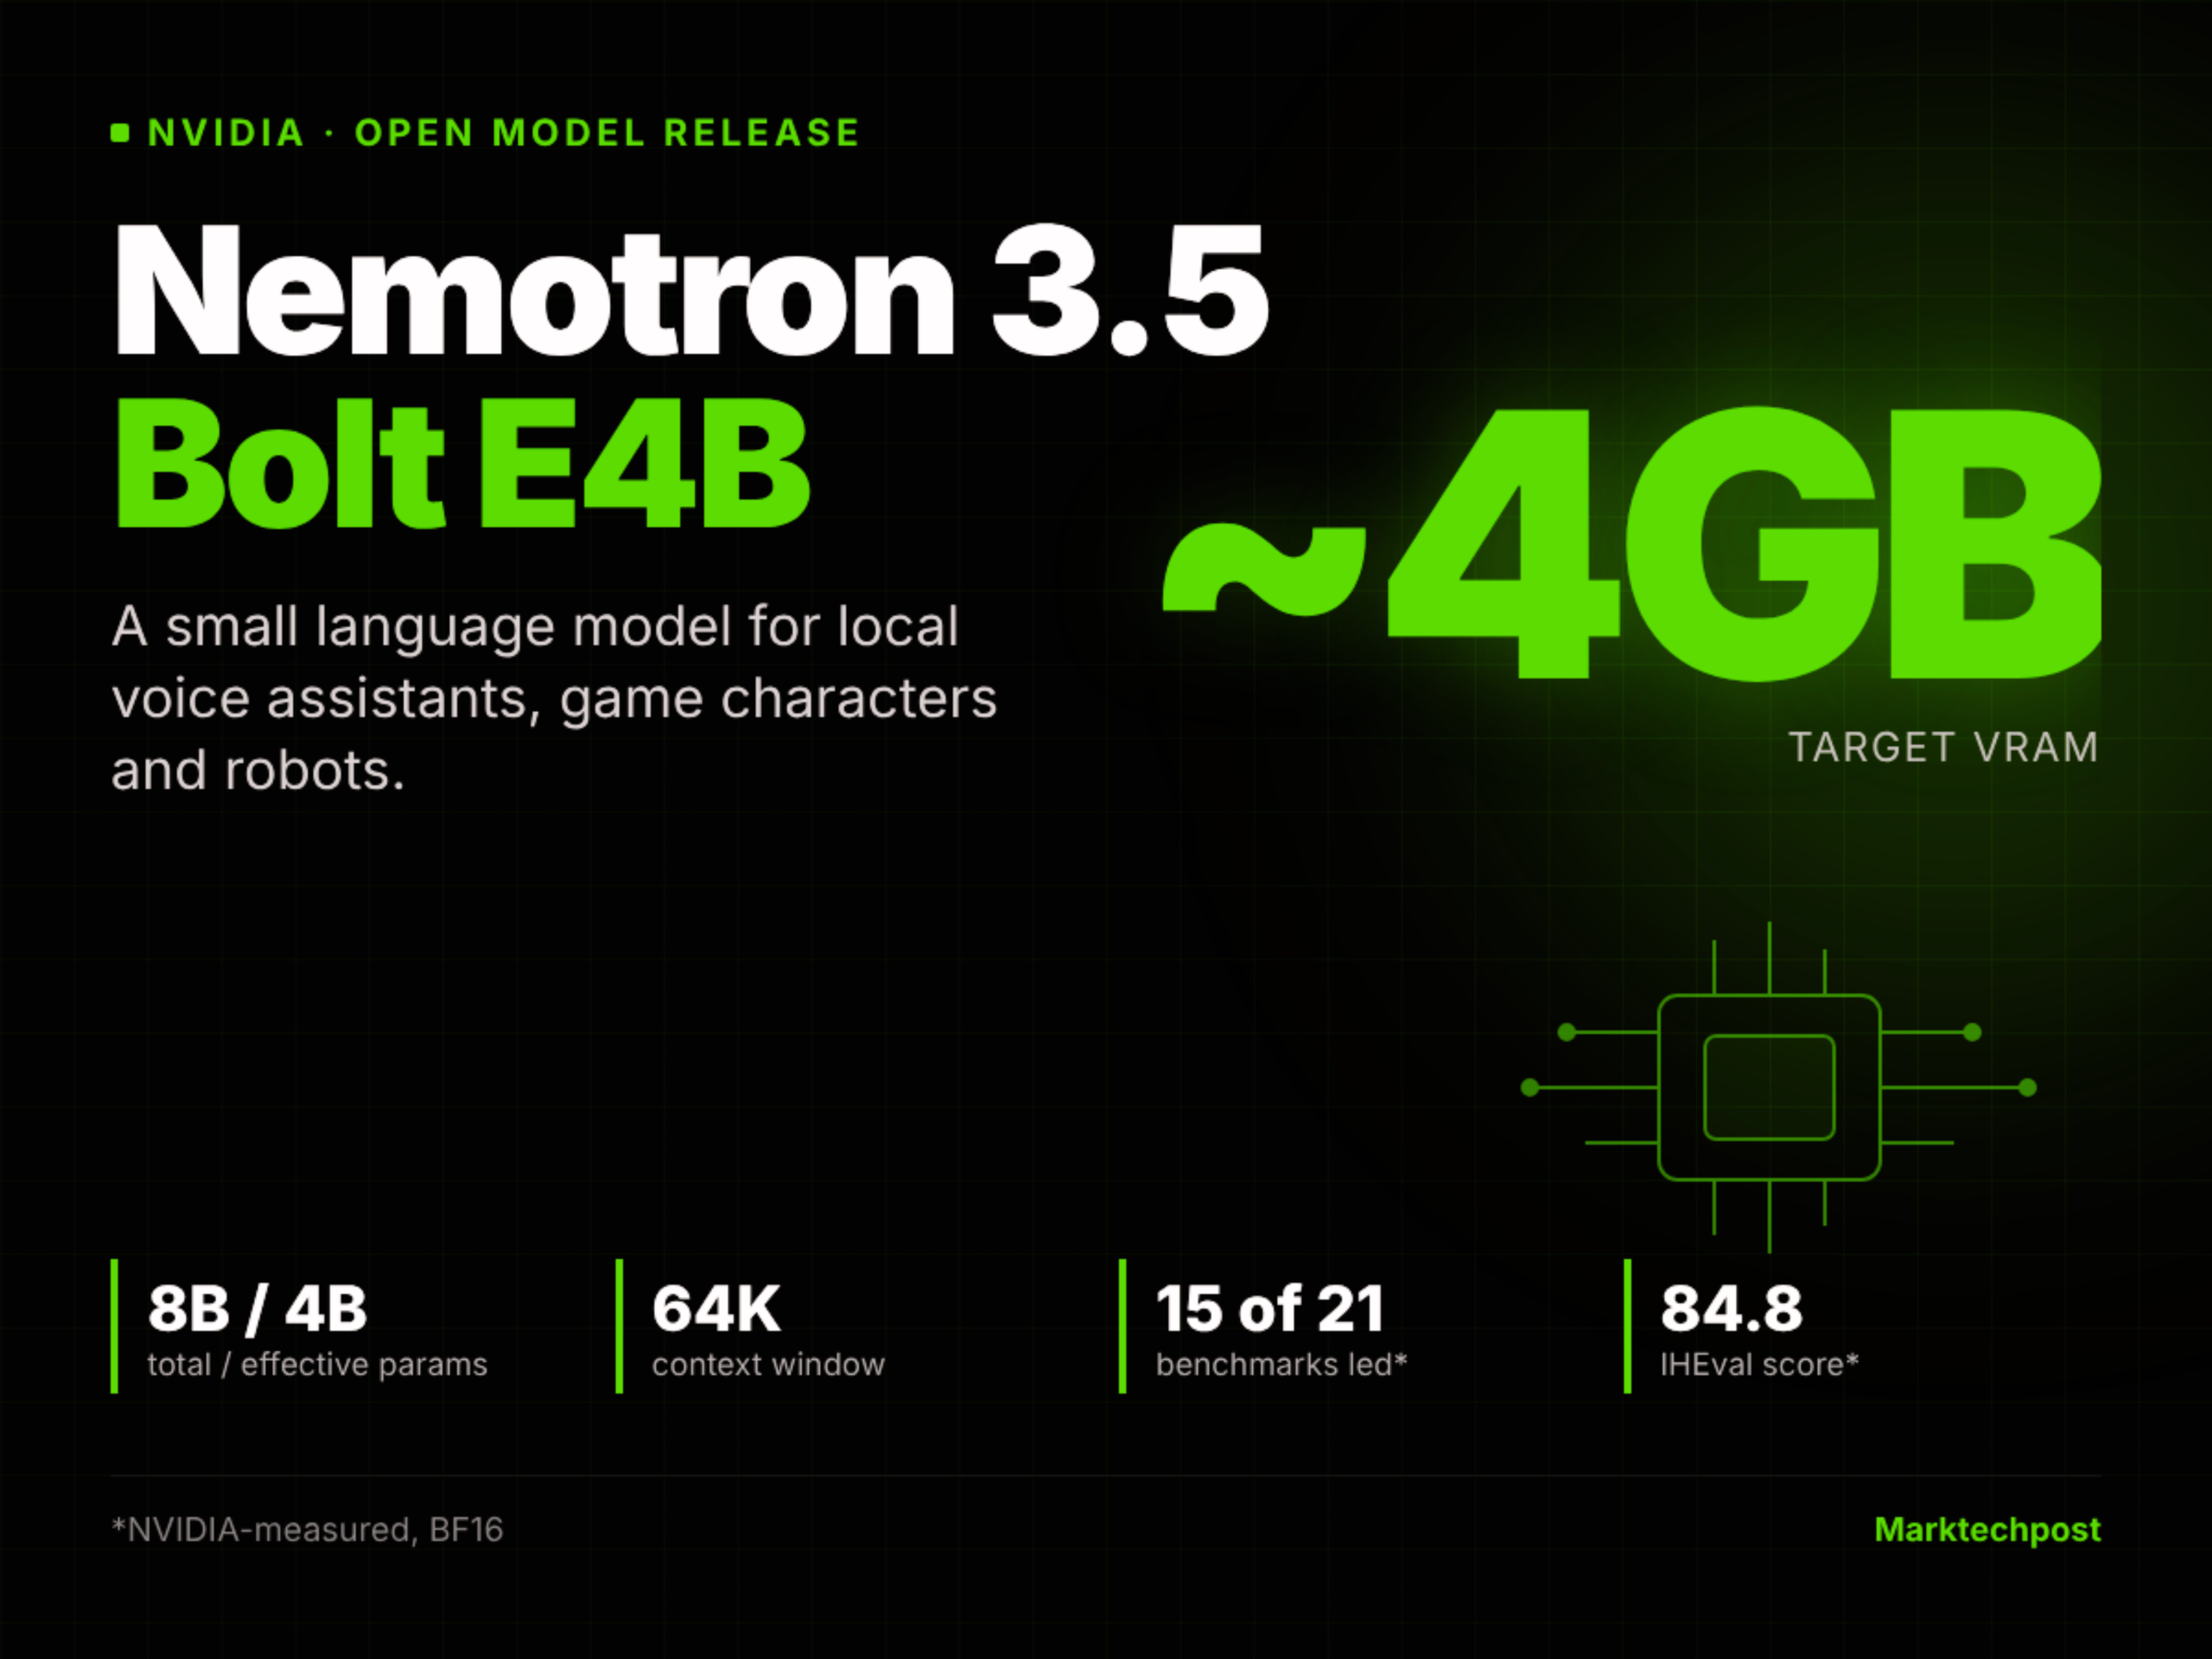
NVIDIA Releases Nemotron 3.5 Bolt E4B 4GB: An Open Small Language Model for Local Voice Agents, Game Characters and Robots
NVIDIA has just released Nemotron 3.5 Bolt E4B 4GB, an open small language model for fast conversational agents. It targets […]
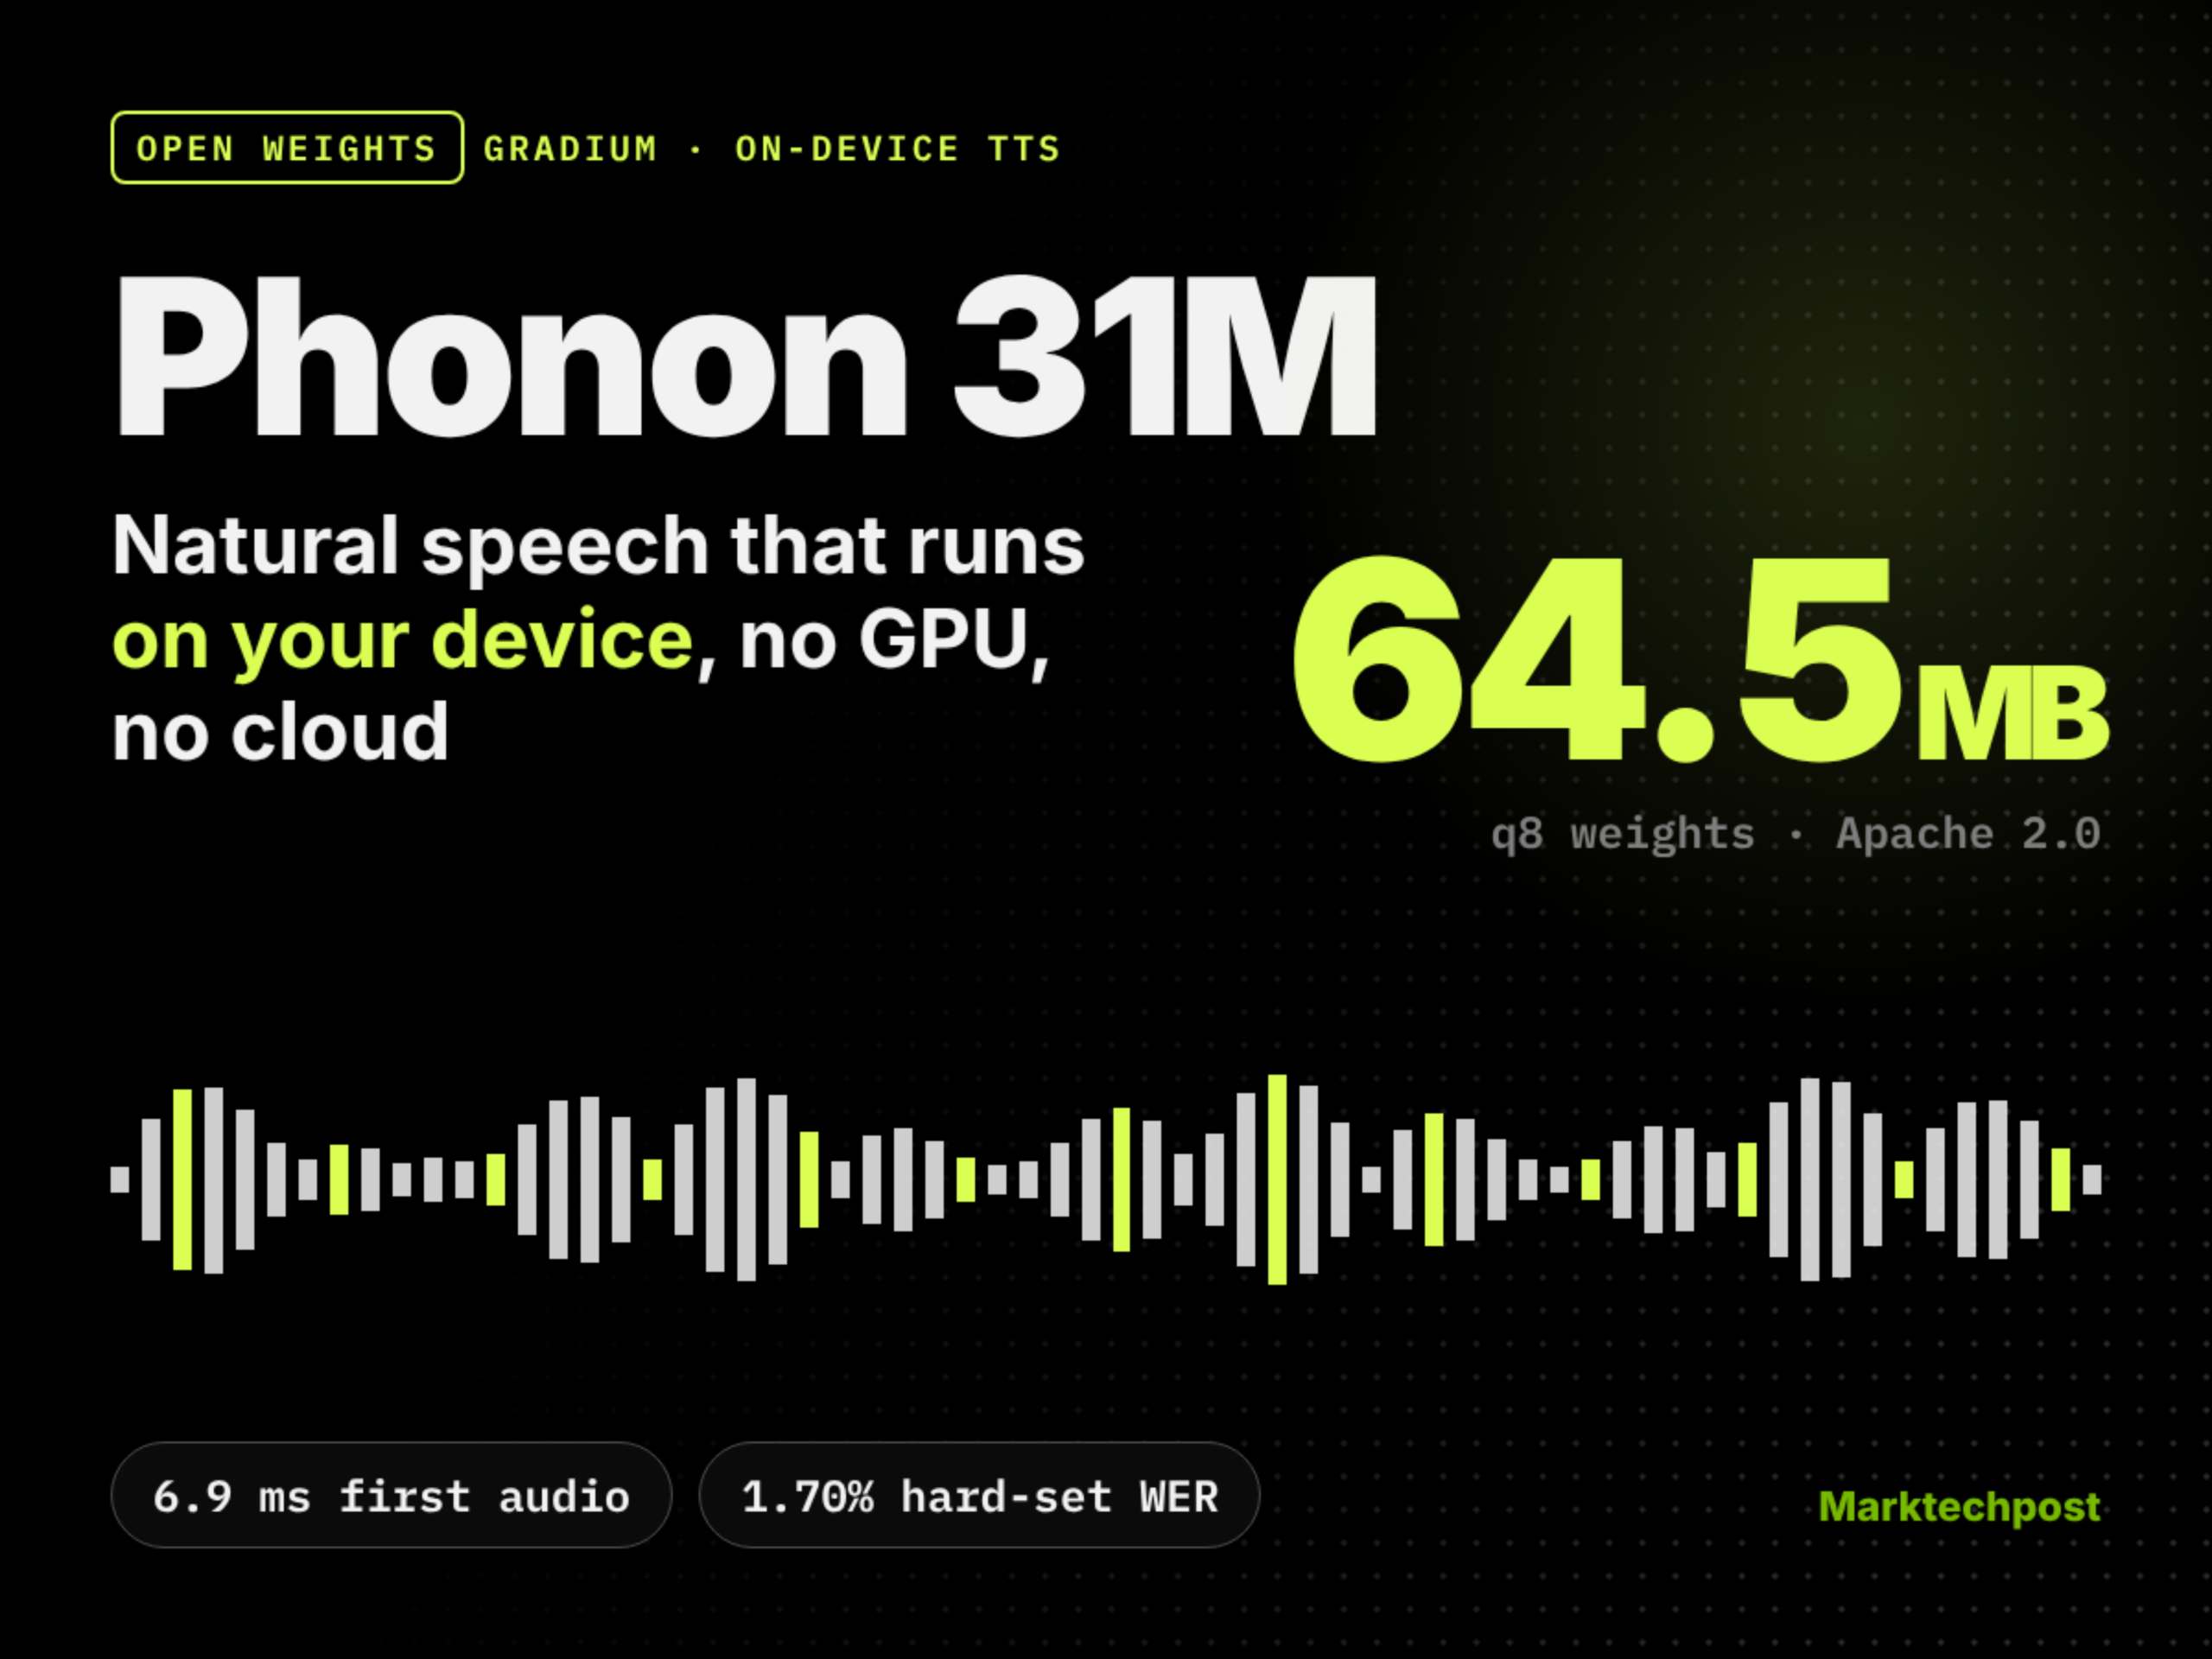
Gradium Open-Sources Phonon, a 31M-Parameter On-Device TTS Model Under Apache 2.0
Gradium has open-sourced Phonon, a family of small text-to-speech models built to run on the device. The Gradium Phonon on-device […]
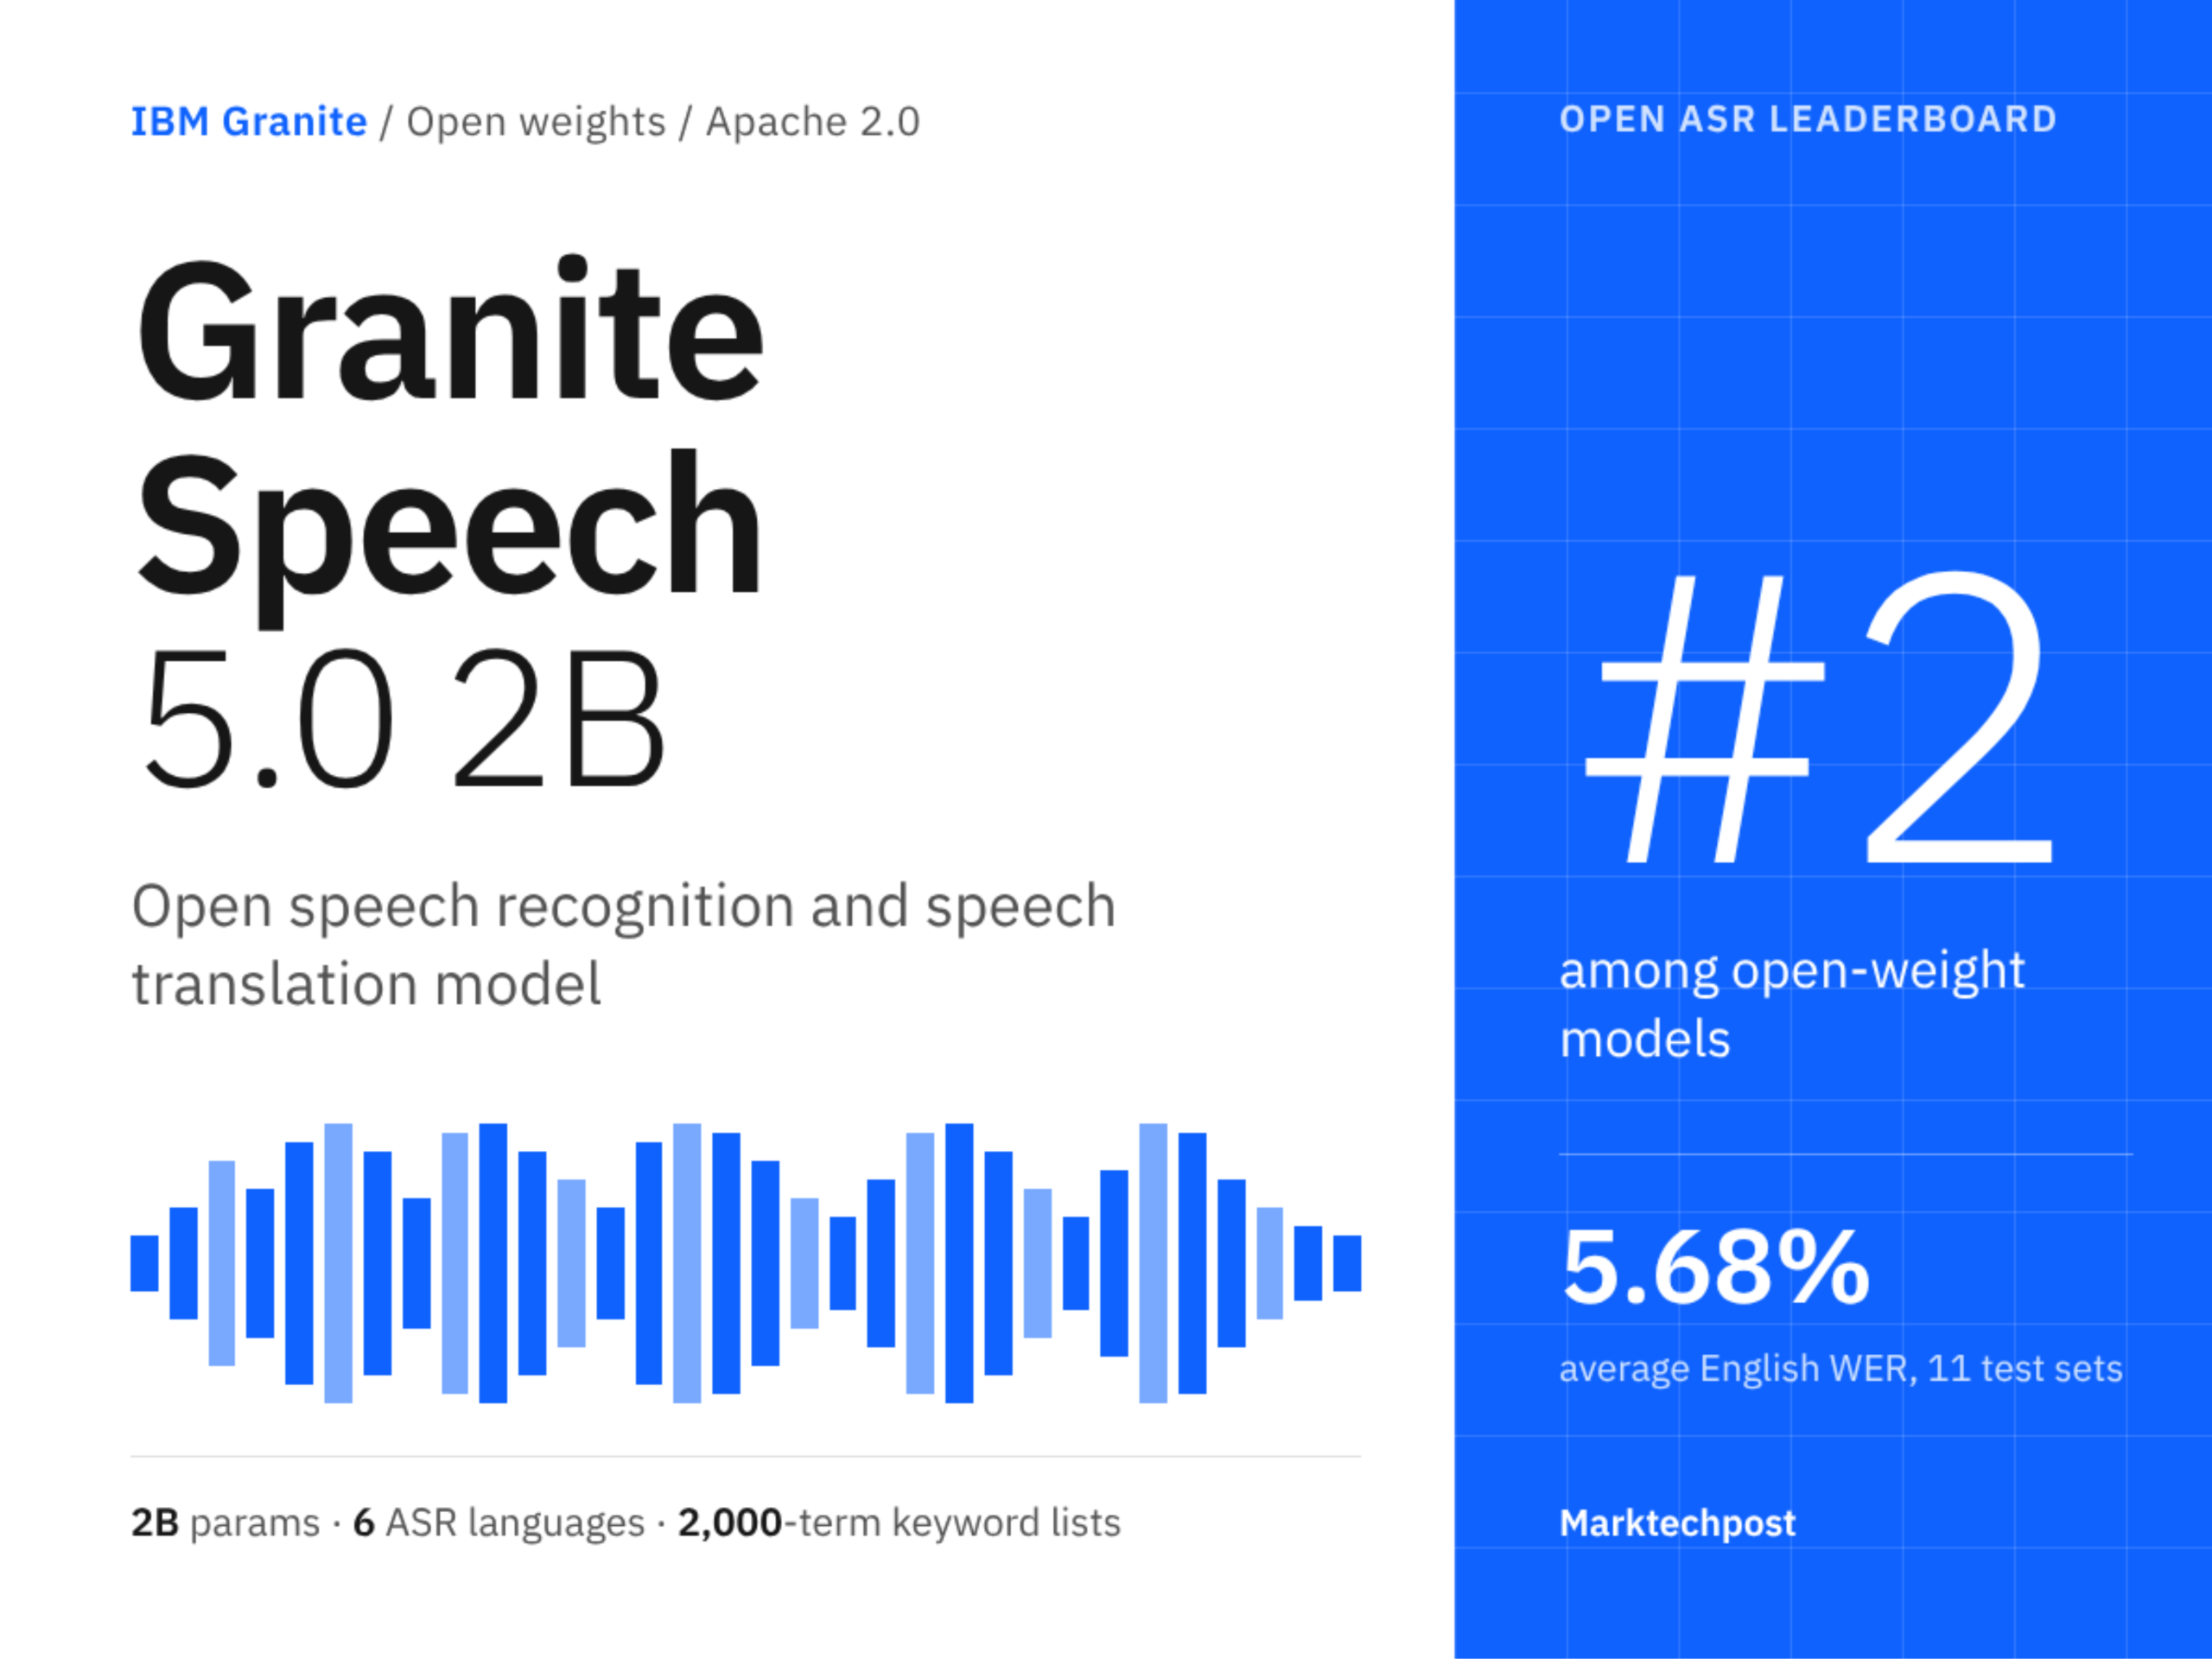
IBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and Translation
IBM has released Granite Speech 5.0 2B, a new open speech-language model for transcription and translation. Granite Speech 5.0 2B […]

A Coding Guide to Cactus Whistle: Does a 16.9 MB Speech Model Hold Up Against Whisper Base? Word Error Rate, Speed, Streaming, Timestamps, Keywords, and Speech-to-Tool Calls on a CPU
In this tutorial, we use Whistle, Cactus Compute’s speech-to-text model, a 16.9 MB file that runs on a CPU, transcribes […]
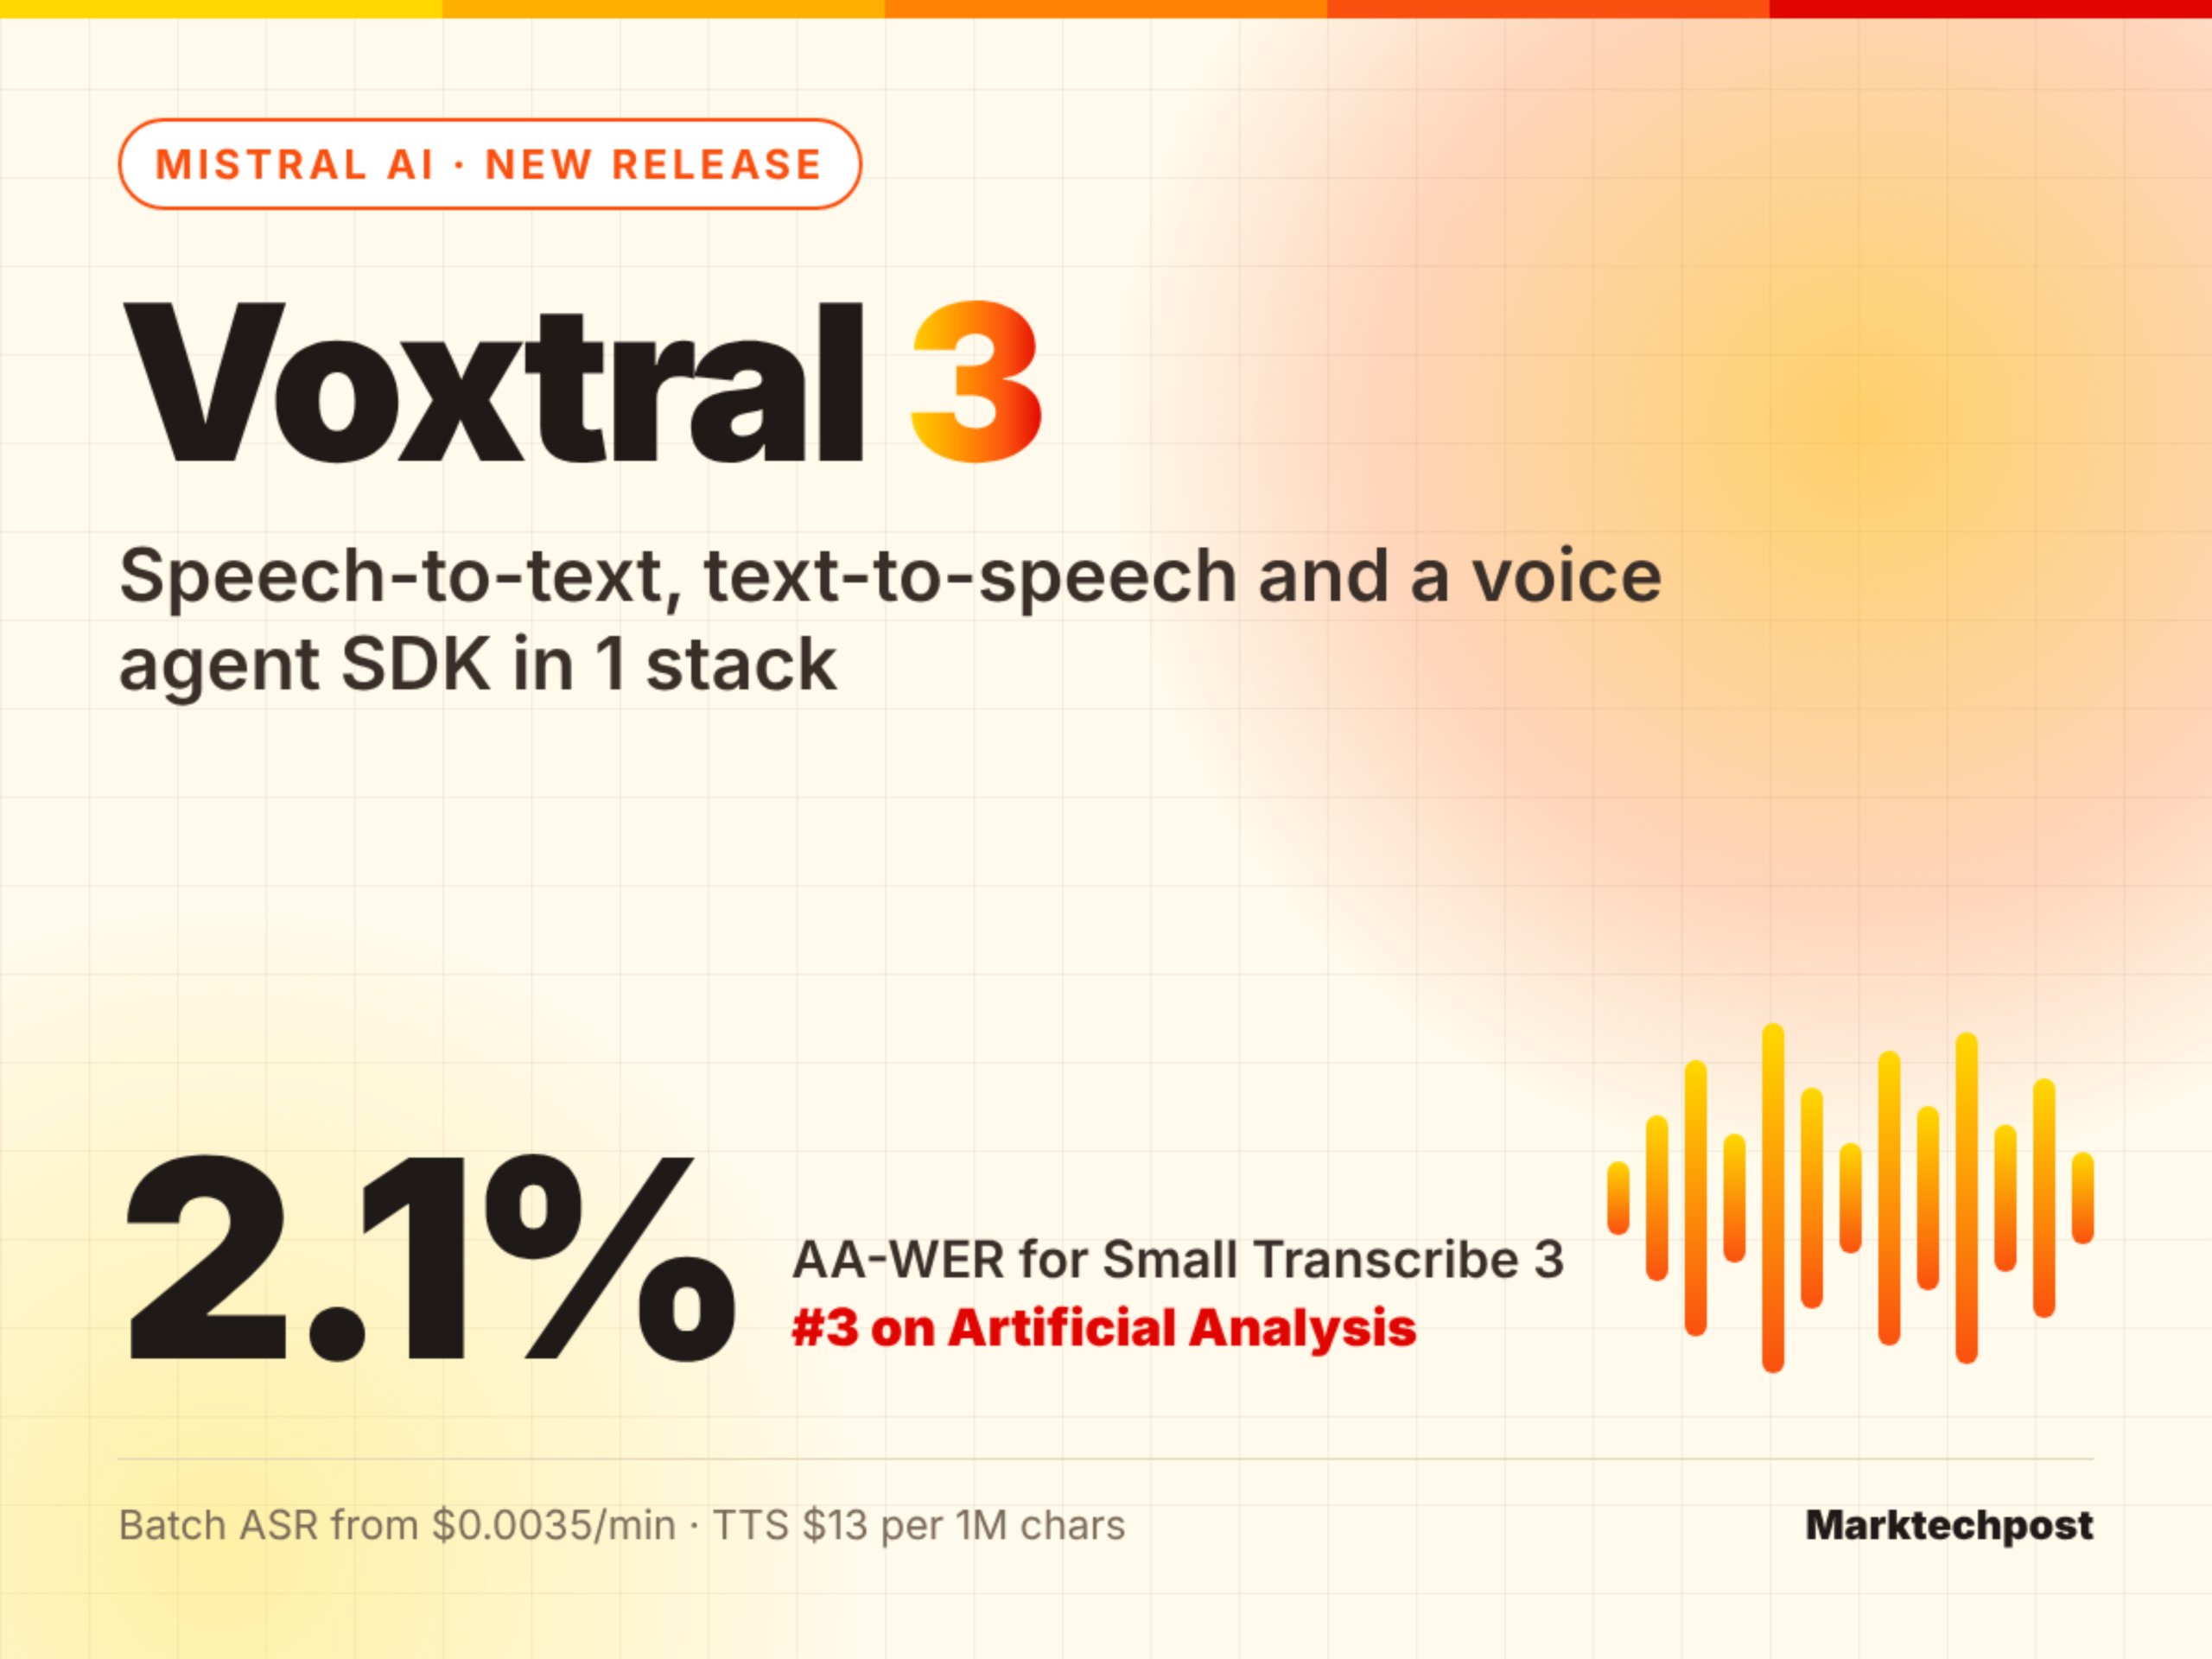
Mistral AI Releases Voxtral 3: Speech-to-Text, TTS and a Voice Agent SDK
Mistral AI just released Voxtral 3. Mistral Voxtral 3 is a speech model family paired with a voice agent SDK. […]