Voice agents fail on exactly the parts of a call that matter most: the order number, the callback digits, the […]
Category: Voice AI
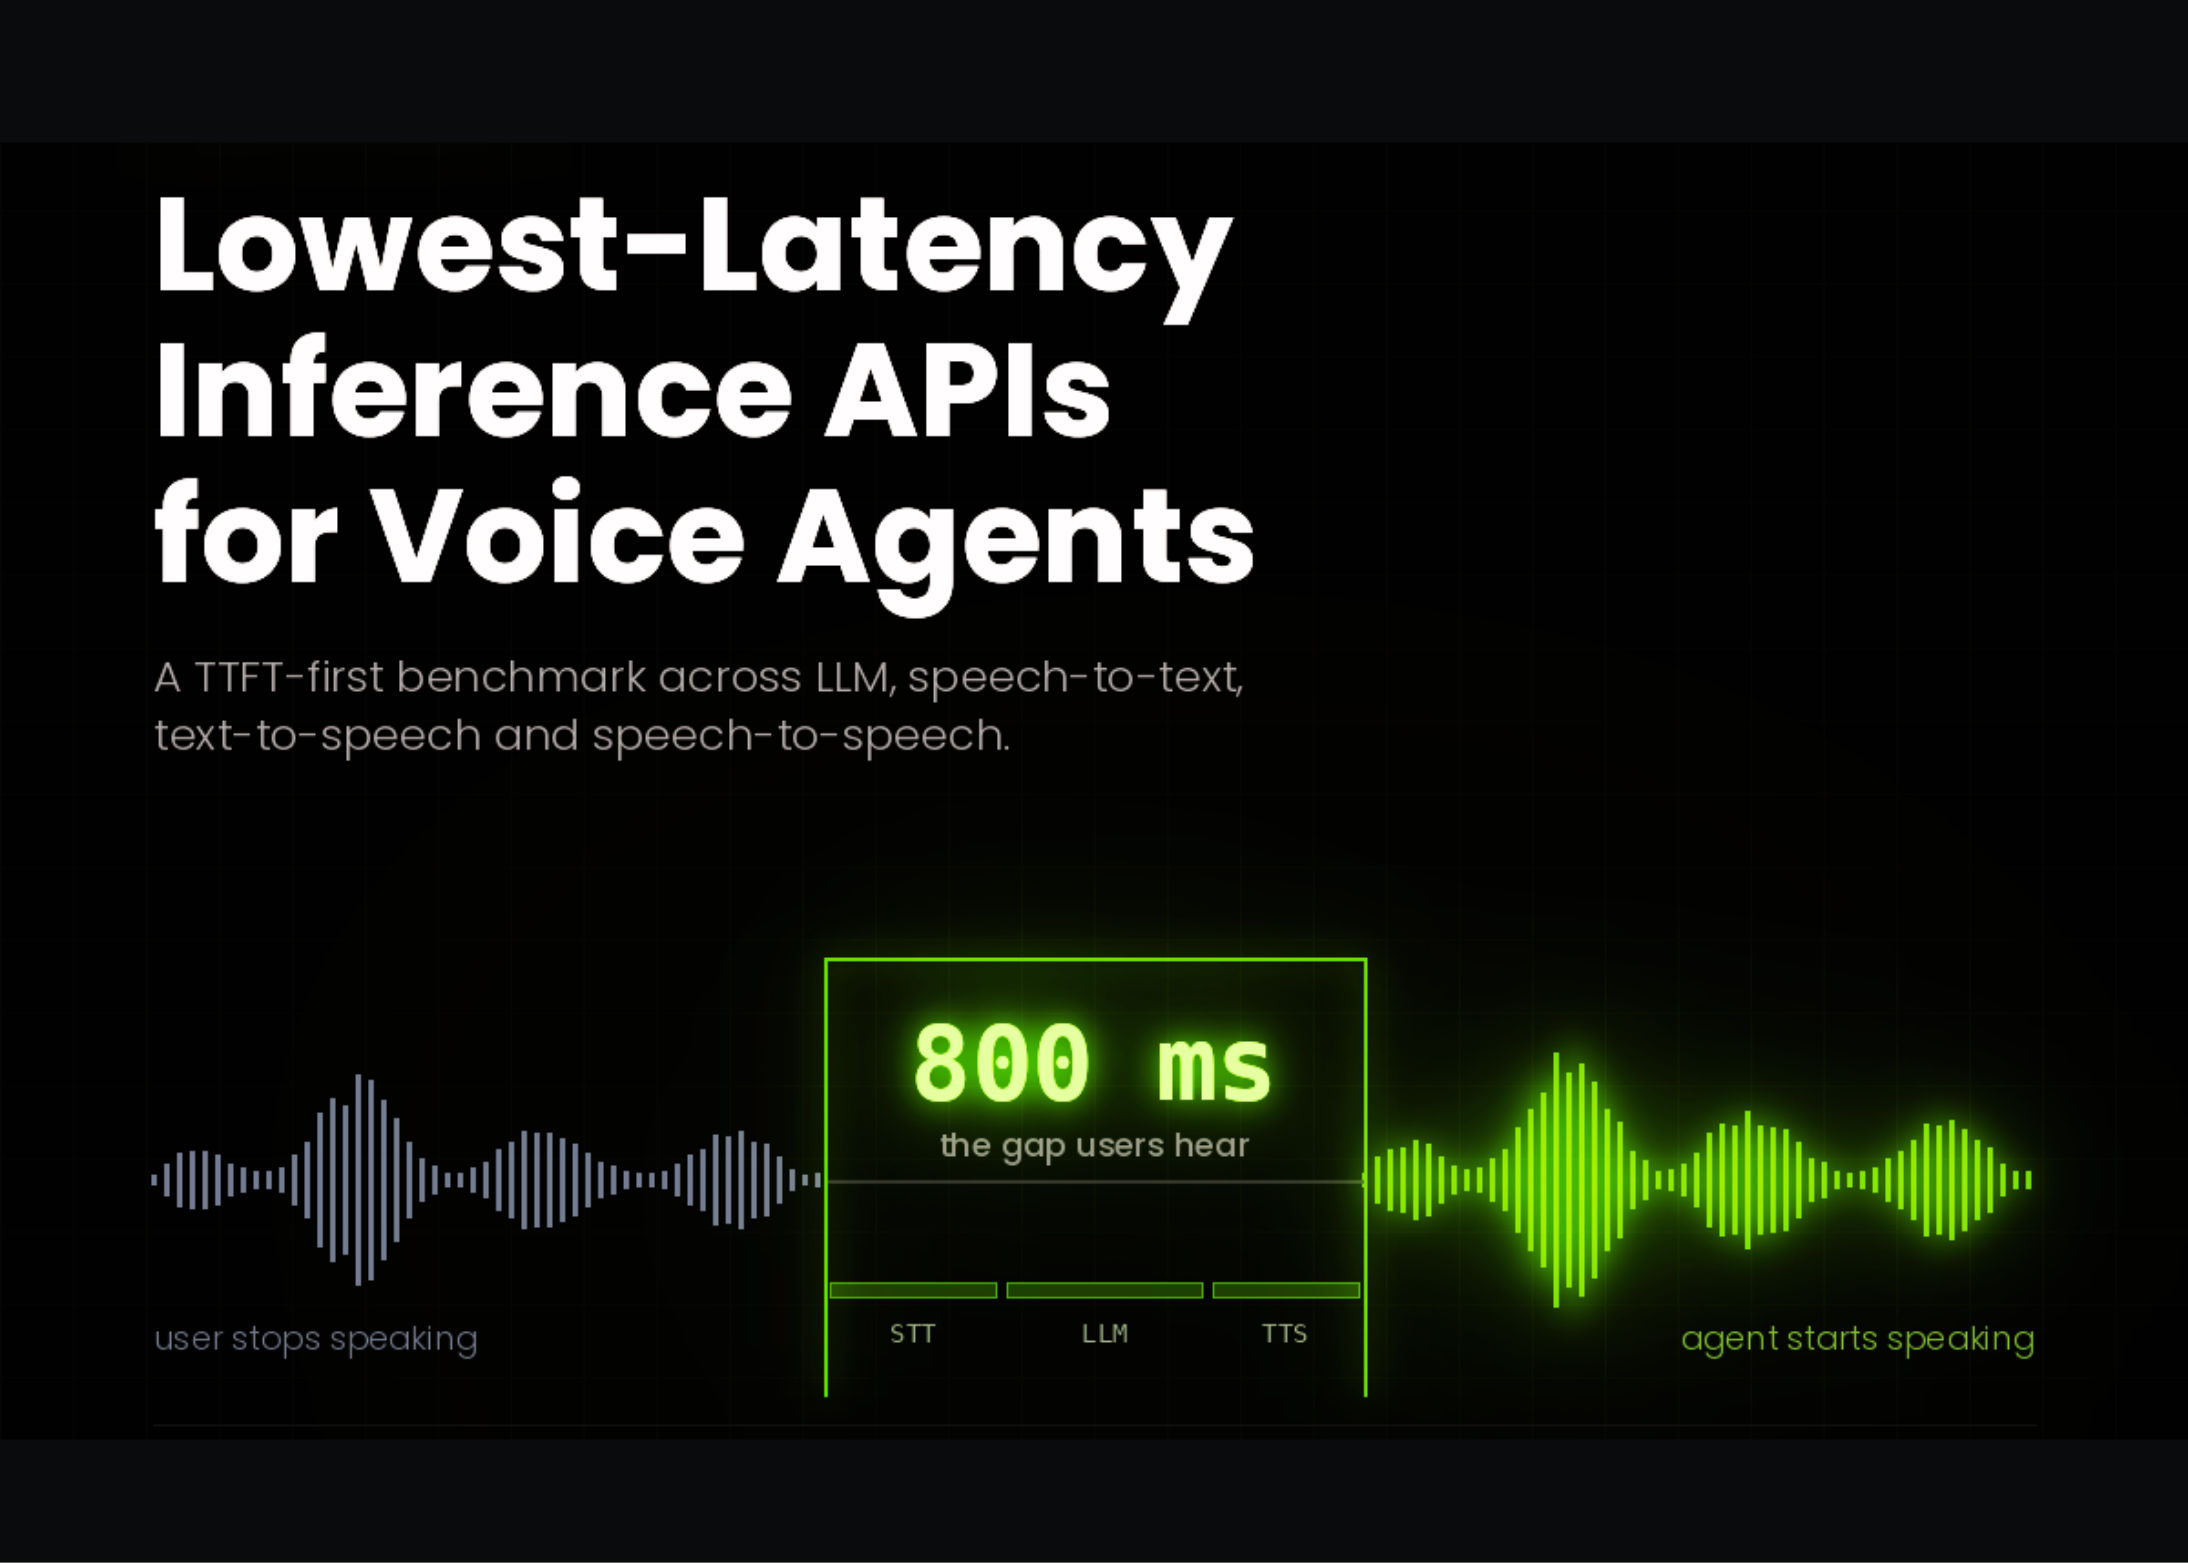
Lowest-Latency Inference APIs for Voice and Realtime Agents: A Time to First Token TTFT-First Benchmark
Time to first token (TTFT) is the metric teams use to pick an inference API for voice. It is also […]
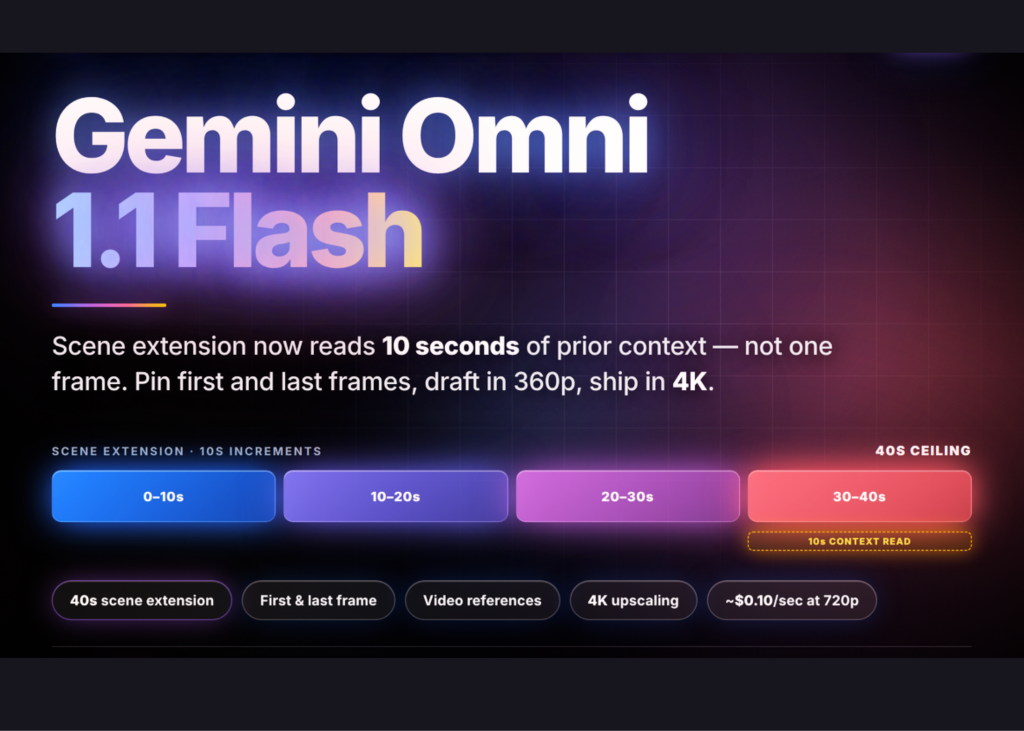
Google AI Releases Gemini Omni 1.1 Flash: 40-Second Scene Extension, First/Last Frame Control, and 4K Upscaling
Google has released Gemini Omni 1.1 Flash (gemini-omni-1.1-flash), a production update to its native multimodal video generation and editing model. […]
Google AI Releases Gemini 3.5 Transcribe: A Speech-to-Text Model Reporting 2.6% Average WER Across 85+ Languages
Google has released Gemini 3.5 Transcribe, a speech-to-text model for real-time voice interfaces and recorded audio. It ships as two […]
Meet S1-mini: Superwhisper’s 462 MB Open-Weights Text Normalizer That Turns Raw ASR Transcripts Into Clean Written Text
Superwhisper has released the S1 family of models: S1-Voice, S1-Language, and S1-mini. S1-Voice is a cloud speech-to-text model, and S1-Language […]

Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both Artificial Analysis Speech Arenas
Cartesia has released Sonic-3.6, the newest version of its real-time text-to-speech model. It arrives roughly three months after Sonic-3.5. The […]
NVIDIA Releases NemotronLabs VoiceChat 11B: An Open Full-Duplex Speech-to-Speech Model with ~450 ms Turn-Taking and Live Tool Calling
NVIDIA has released NemotronLabs VoiceChat 11B, an open 11B end-to-end speech-to-speech model for real-time, full-duplex conversation. Instead of chaining ASR, […]
MiniMax Releases MiniMax H3: An Omni-Modal Video Model That Generates 15-Second 2K Clips With Native Stereo Audio
MiniMax releases MiniMax H3, a general-purpose multimodal generation model. MiniMax H3 is not a text-to-video model with add-ons. MiniMax describes […]

PolyAI Releases Dialog-RSN-1: An Audio-Native Dialog Model That Fuses Turn-Taking, Speech Recognition, Function Calling, And Response
PolyAI has introduced Dialog-RSN-1, a dialog model that perceives the caller’s audio directly instead of reading a transcript. It fuses […]
Best Open Speech Recognition (ASR) Models in 2026: WER, Languages, Latency, and License Compared
Open speech recognition stopped being a Whisper monoculture some time in the last twelve months. In March 2026 Cohere released […]