Open speech recognition stopped being a Whisper monoculture some time in the last twelve months. In March 2026 Cohere released […]
Category: Voice AI

Alibaba’s Tongyi Lab Releases Qwen-Audio-3.0-TTS, a Hosted Text-to-Speech Model in Flash and Plus Tiers Across 16 Languages
Alibaba’s Tongyi Lab has released Qwen-Audio-3.0-TTS, a production-oriented text-to-speech (TTS) system. The model ships in two variants from the same […]
OpenAI Releases GPT-Live and GPT-Live-1 mini: Full-Duplex Voice Models That Delegate Deeper Reasoning to GPT-5.5
Today, OpenAI released GPT-Live. It is a new generation of voice models. GPT-Live now powers the ChatGPT Voice experience. The […]
NVIDIA Releases Audex (Nemotron-Labs-Audex-30B-A3B): A Unified Audio-Text LLM That Preserves the Text Intelligence of Its Backbone
NVIDIA has released Audex (Nemotron-Labs-Audex-30B-A3B), a unified audio-text large language model. It understands and generates both audio and speech. It […]
OpenAI Releases GPT-Realtime-2.1 and GPT-Realtime-2.1-mini for Low-Latency Voice Agents in the API
OpenAI has released two new Realtime models in its API. They are named gpt-realtime-2.1 and gpt-realtime-2.1-mini. Both target low-latency voice […]

Interfaze Ships diffusion-gemma-asr-small, an Open-Source Diffusion ASR Model Transcribing Six Languages via DiffusionGemma’s Parallel Denoising Decoder
Interfaze, a young YC’s startup, has open-sourced a new speech recognition model. It is called diffusion-gemma-asr-small. The model transcribes audio […]
Gradium Launches stt-translate and s2s-translate, Real-Time Speech Translation Models Beating gpt-realtime-translate on Accuracy and Latency
Gradium today released two real-time speech translation models: stt-translate and s2s-translate. Both run across five languages and stream results live […]
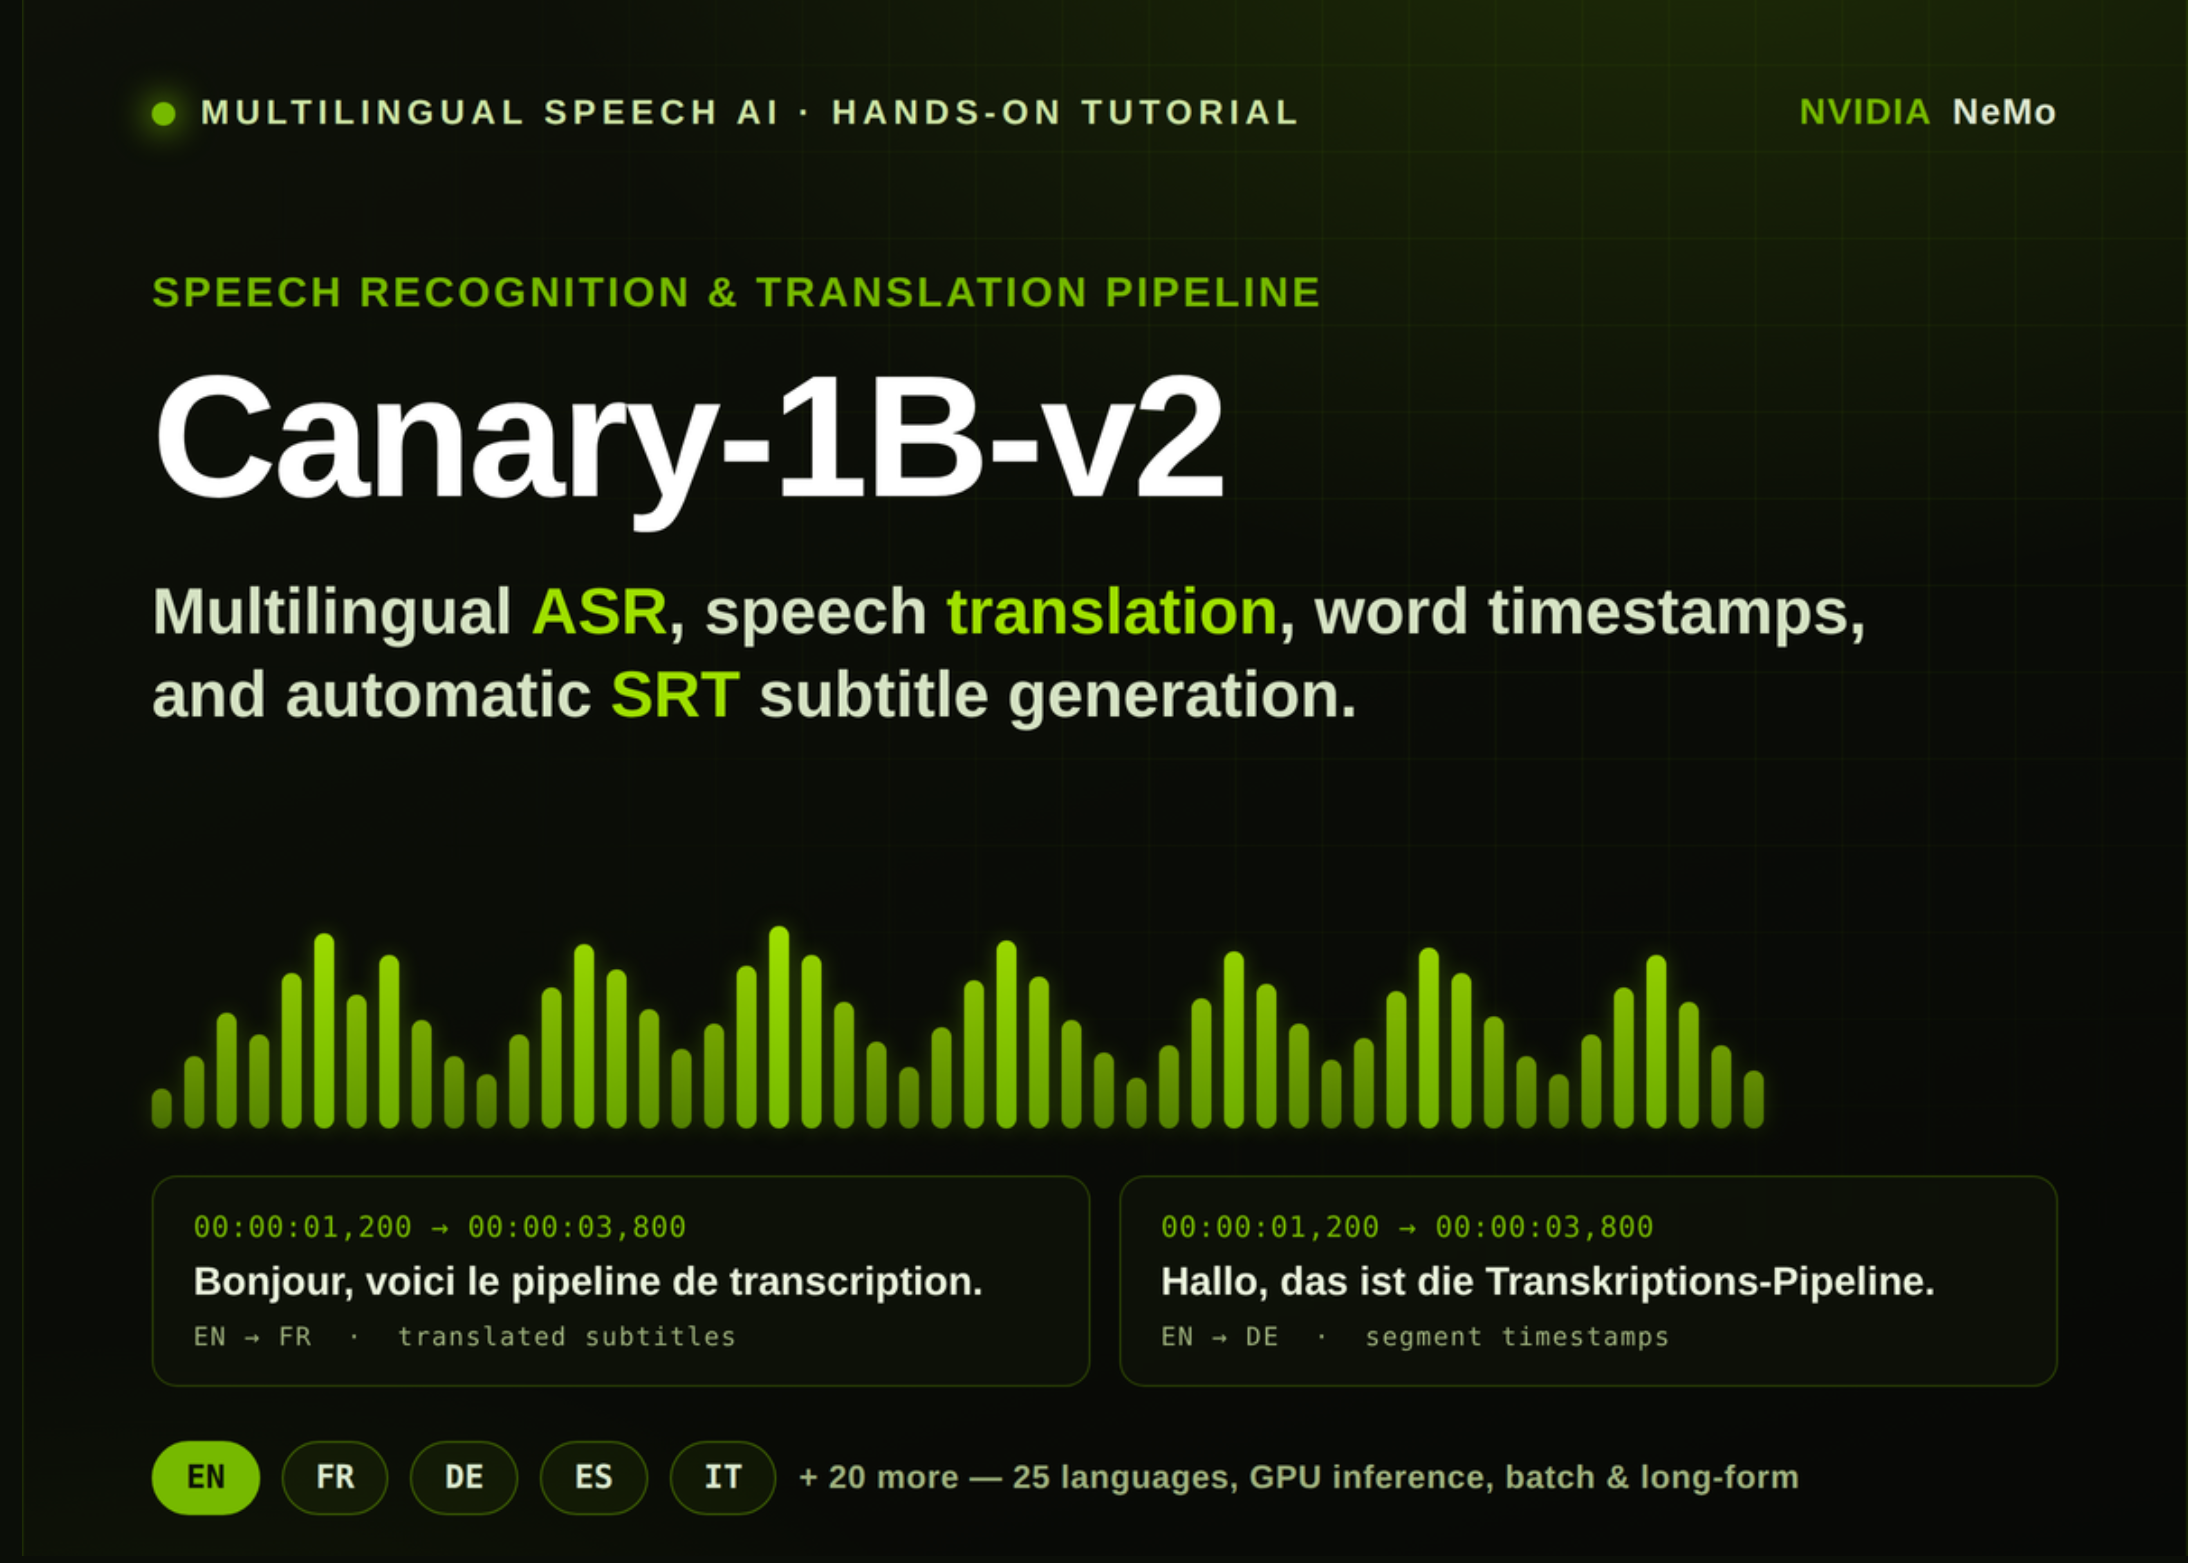
How to Use NVIDIA Canary-1B-v2 for ASR, Translation, and Automatic SRT Subtitle Export in Python
In this tutorial, we build a speech recognition and translation workflow using NVIDIA Canary-1B-v2. We begin by setting up the […]
Google Releases Gemini 3.5 Live Translate, a Streaming Speech-to-Speech Audio Model Covering 70+ Languages Across Meet, Translate, and the Live API
Google just announced Gemini 3.5 Live Translate. It is their latest audio model for live speech-to-speech translation. Speech-to-speech means spoken […]
Microsoft AI Introduces MAI-Transcribe-1.5: 2.4% WER on Artificial Analysis, Best-in-Class FLEURS Accuracy, and Up to 5x Faster Long-Audio Transcription
Last week Microsoft AI has announced MAI-Transcribe-1.5. It is the second iteration of the company’s in-house speech-to-text family. The model […]