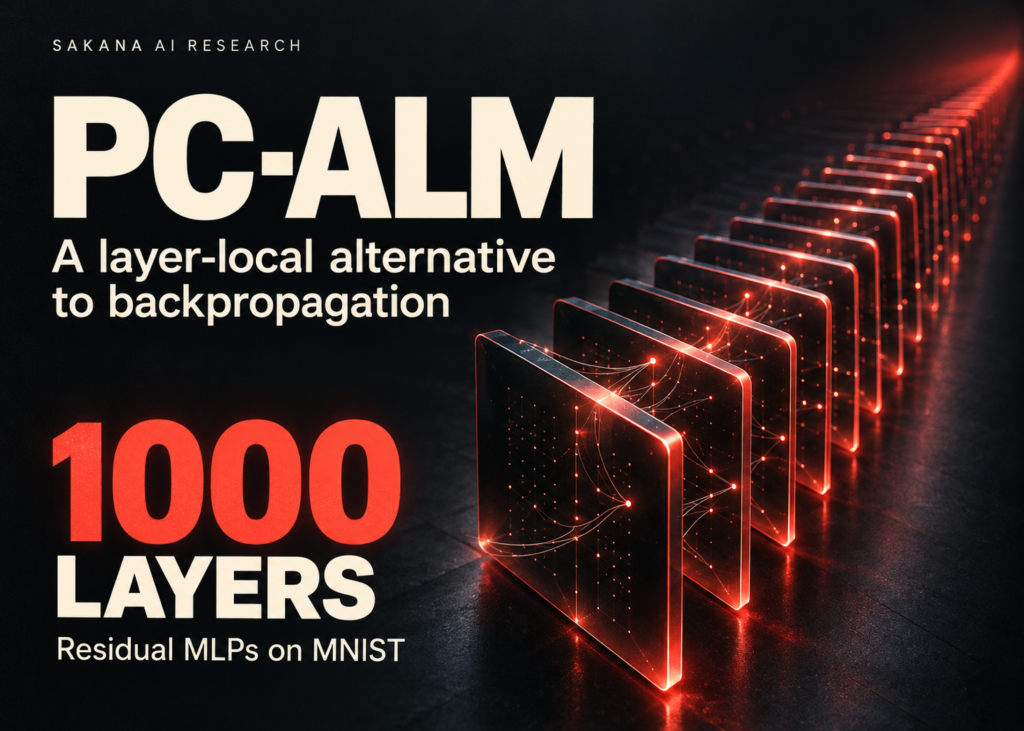
Backpropagation is a global algorithm: a forward pass, then a backward pass, then a weight update, each locked behind the […]
Category: AI infrastructure
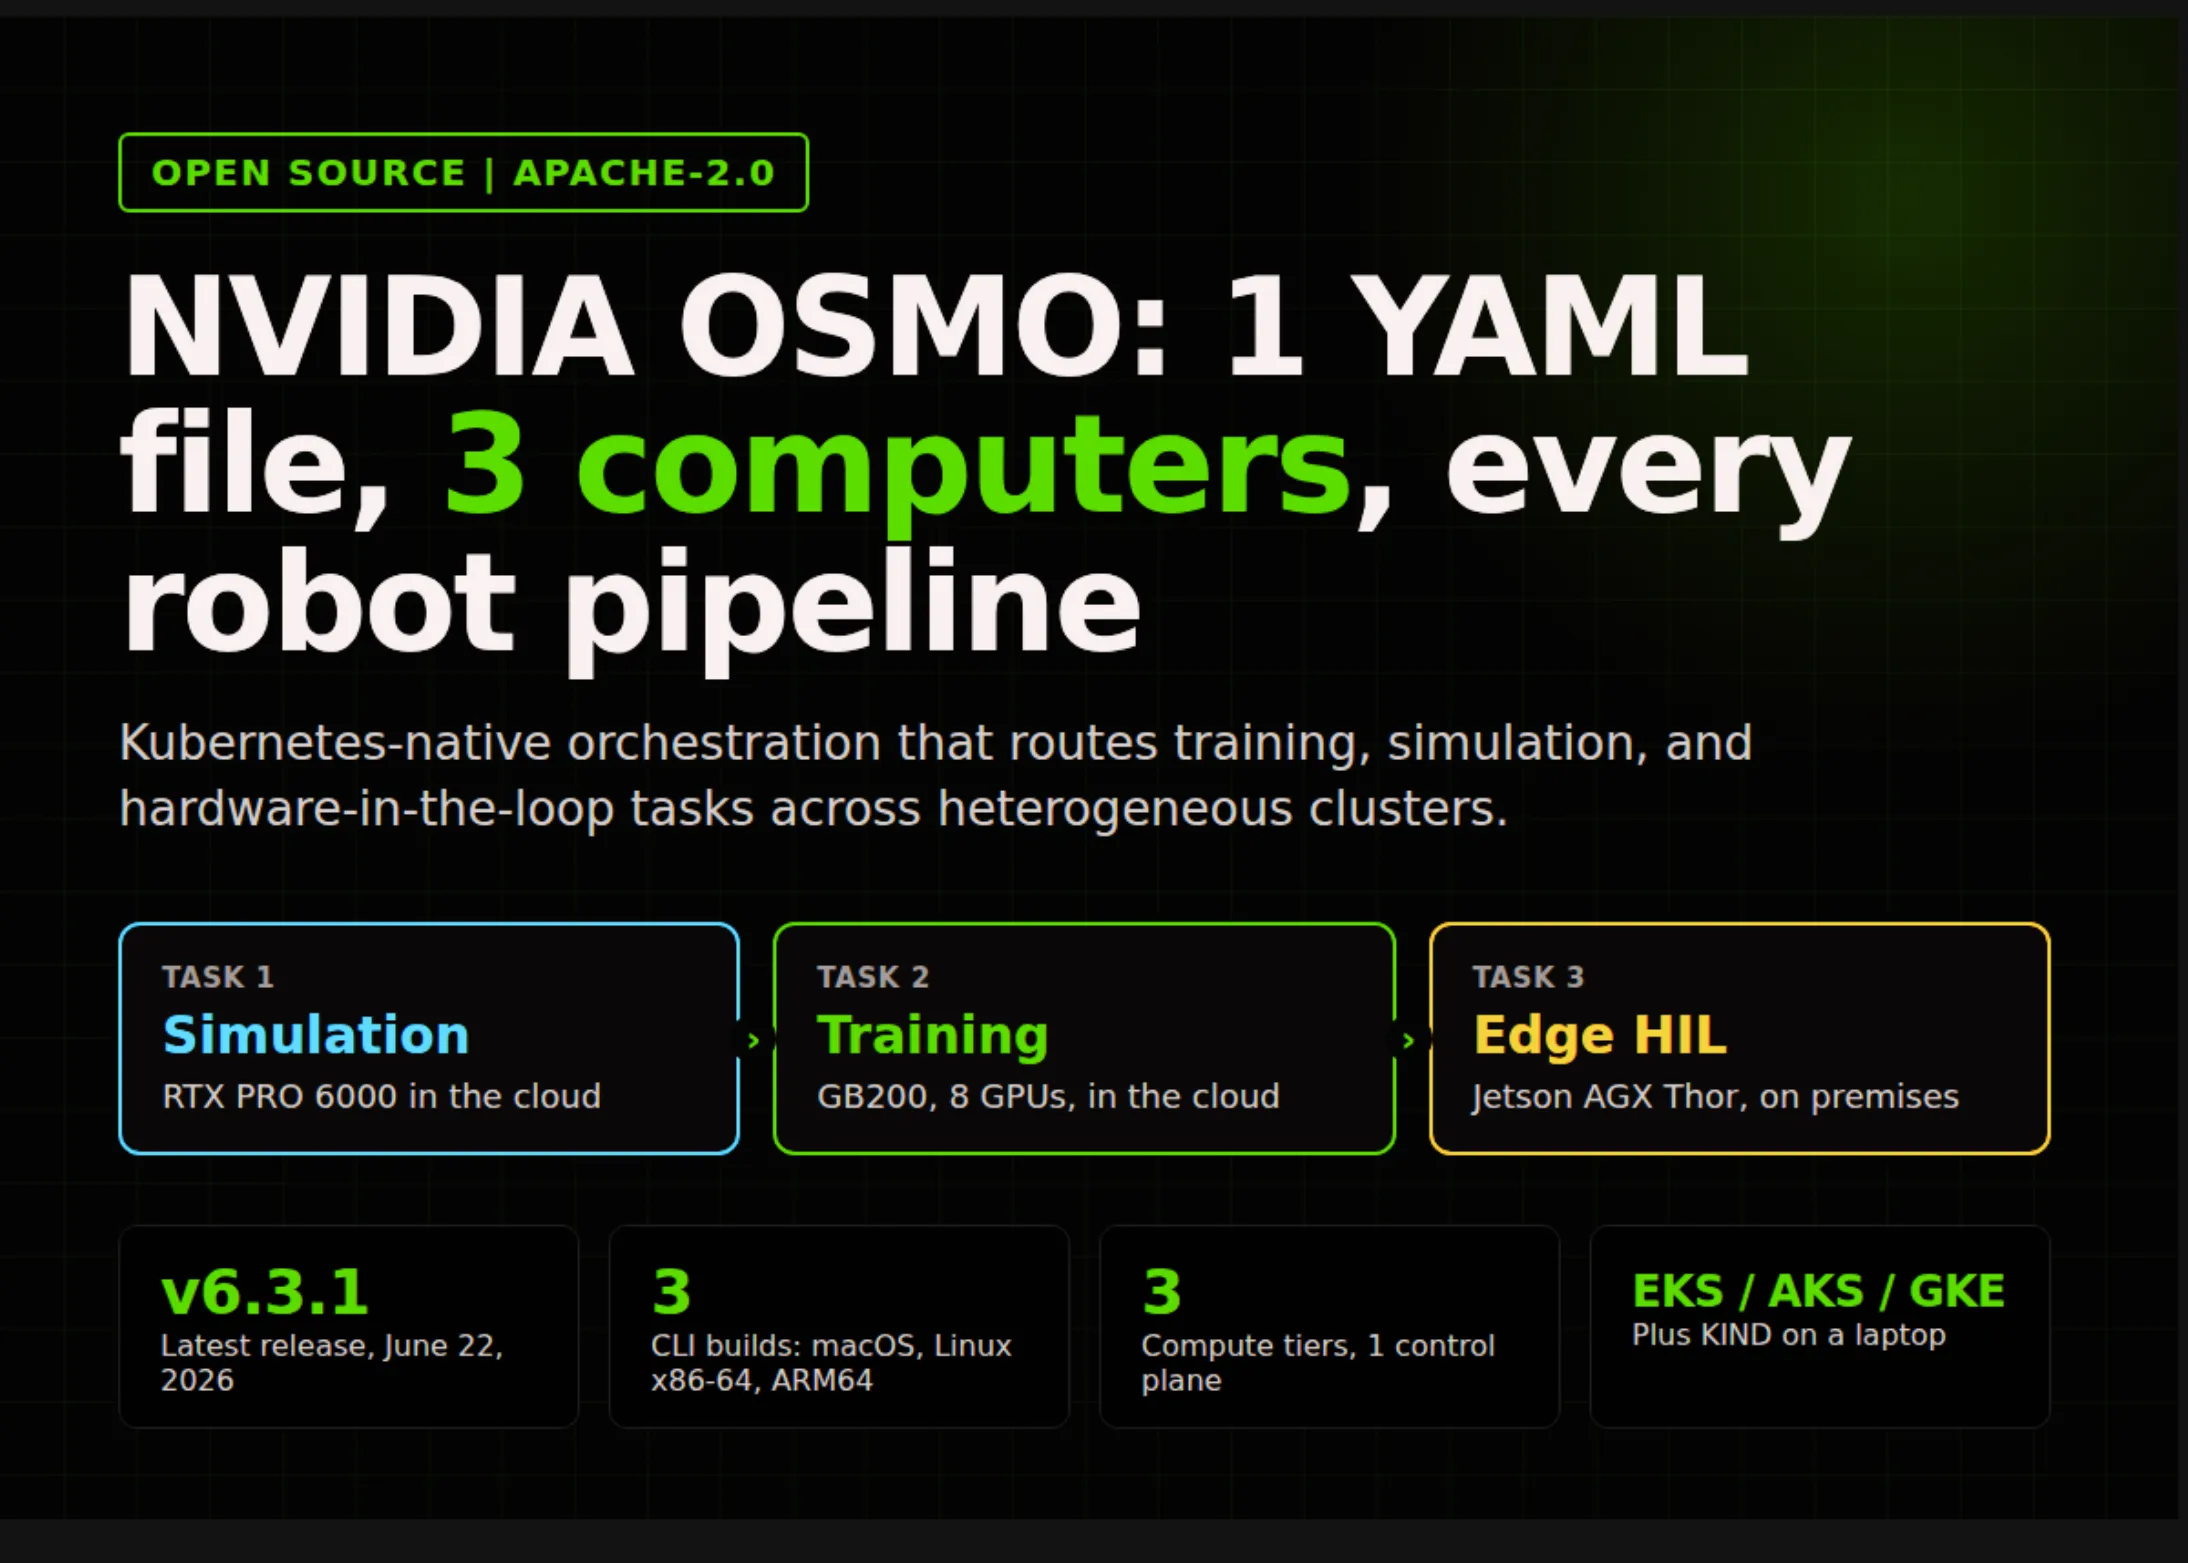
NVIDIA Open-Sources OSMO: One YAML Orchestrates Physical AI Training, Simulation, and Robot Testing
Robot developers do not have one compute problem. They have 3. A policy is trained on GB200 or H100 clusters, […]
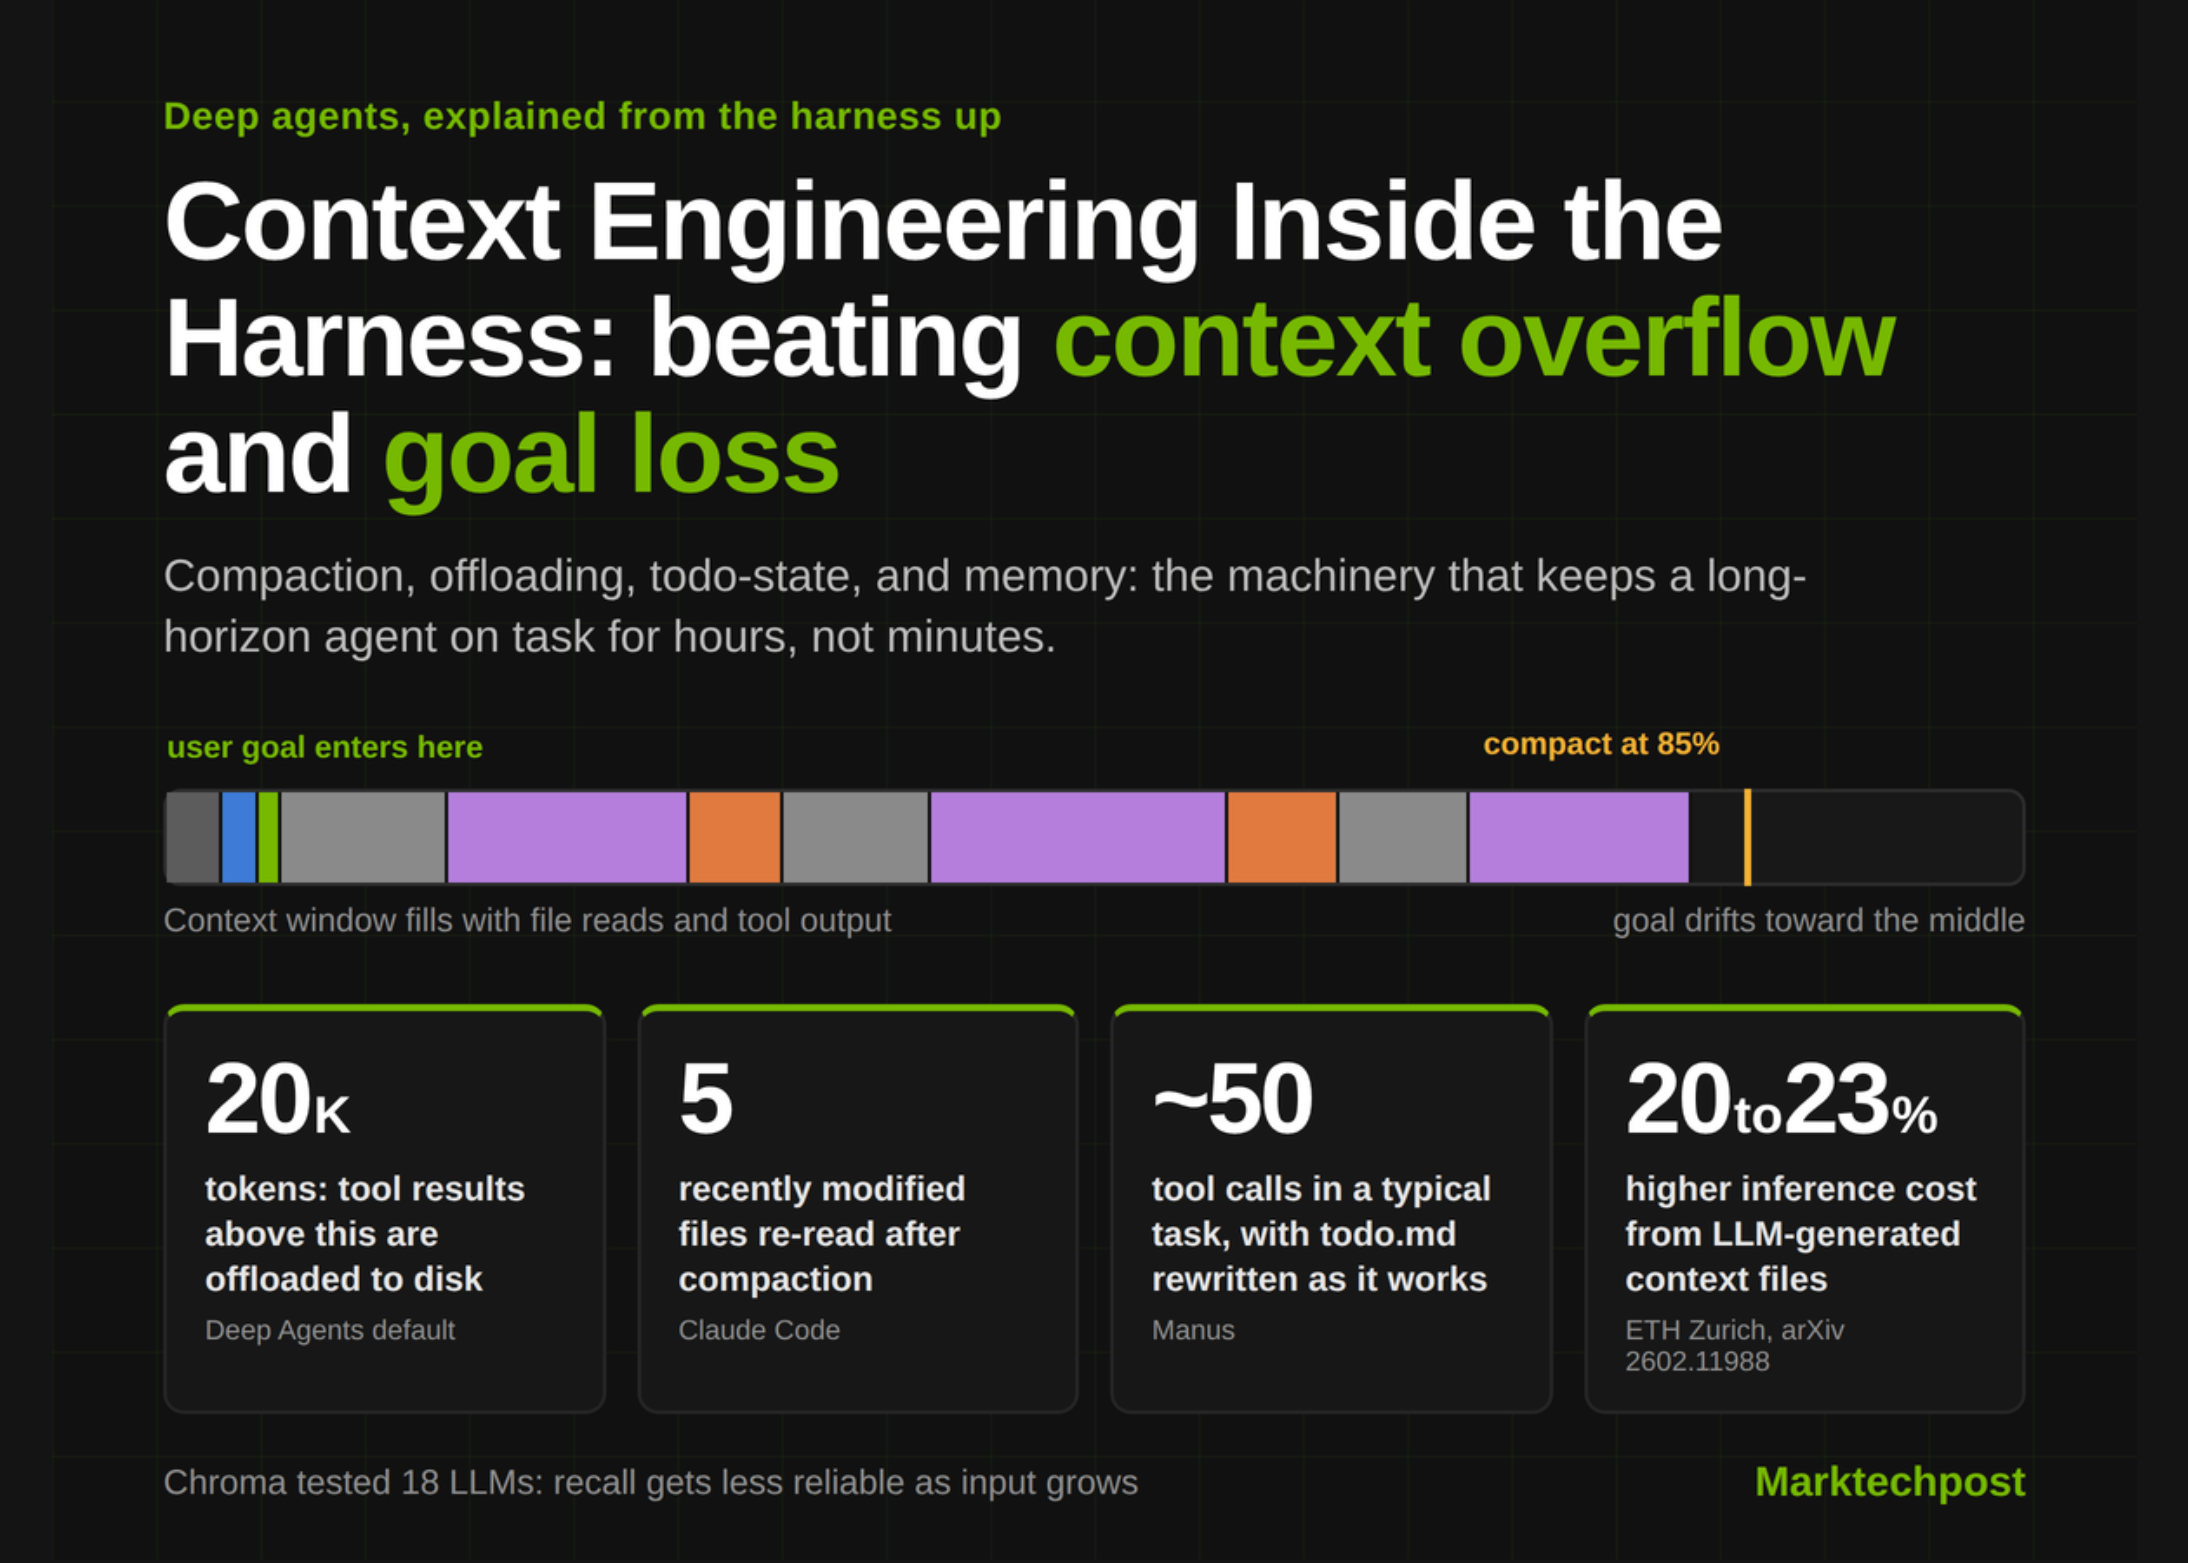
Context Engineering Inside the Harness: 4 Mechanisms That Beat Context Overflow and Goal Loss on Long-Horizon Tasks
An agent, in its simplest form, is an LLM calling tools in a loop. That loop works for short jobs. […]
Implementation of Machine Learning Workflows with NVIDIA cuML, RAPIDS, GPU Benchmarking, Explainability, Clustering, and Model Inference
In this tutorial, we implement NVIDIA cuML as a GPU-accelerated machine learning framework and build a practical workflow that demonstrates […]
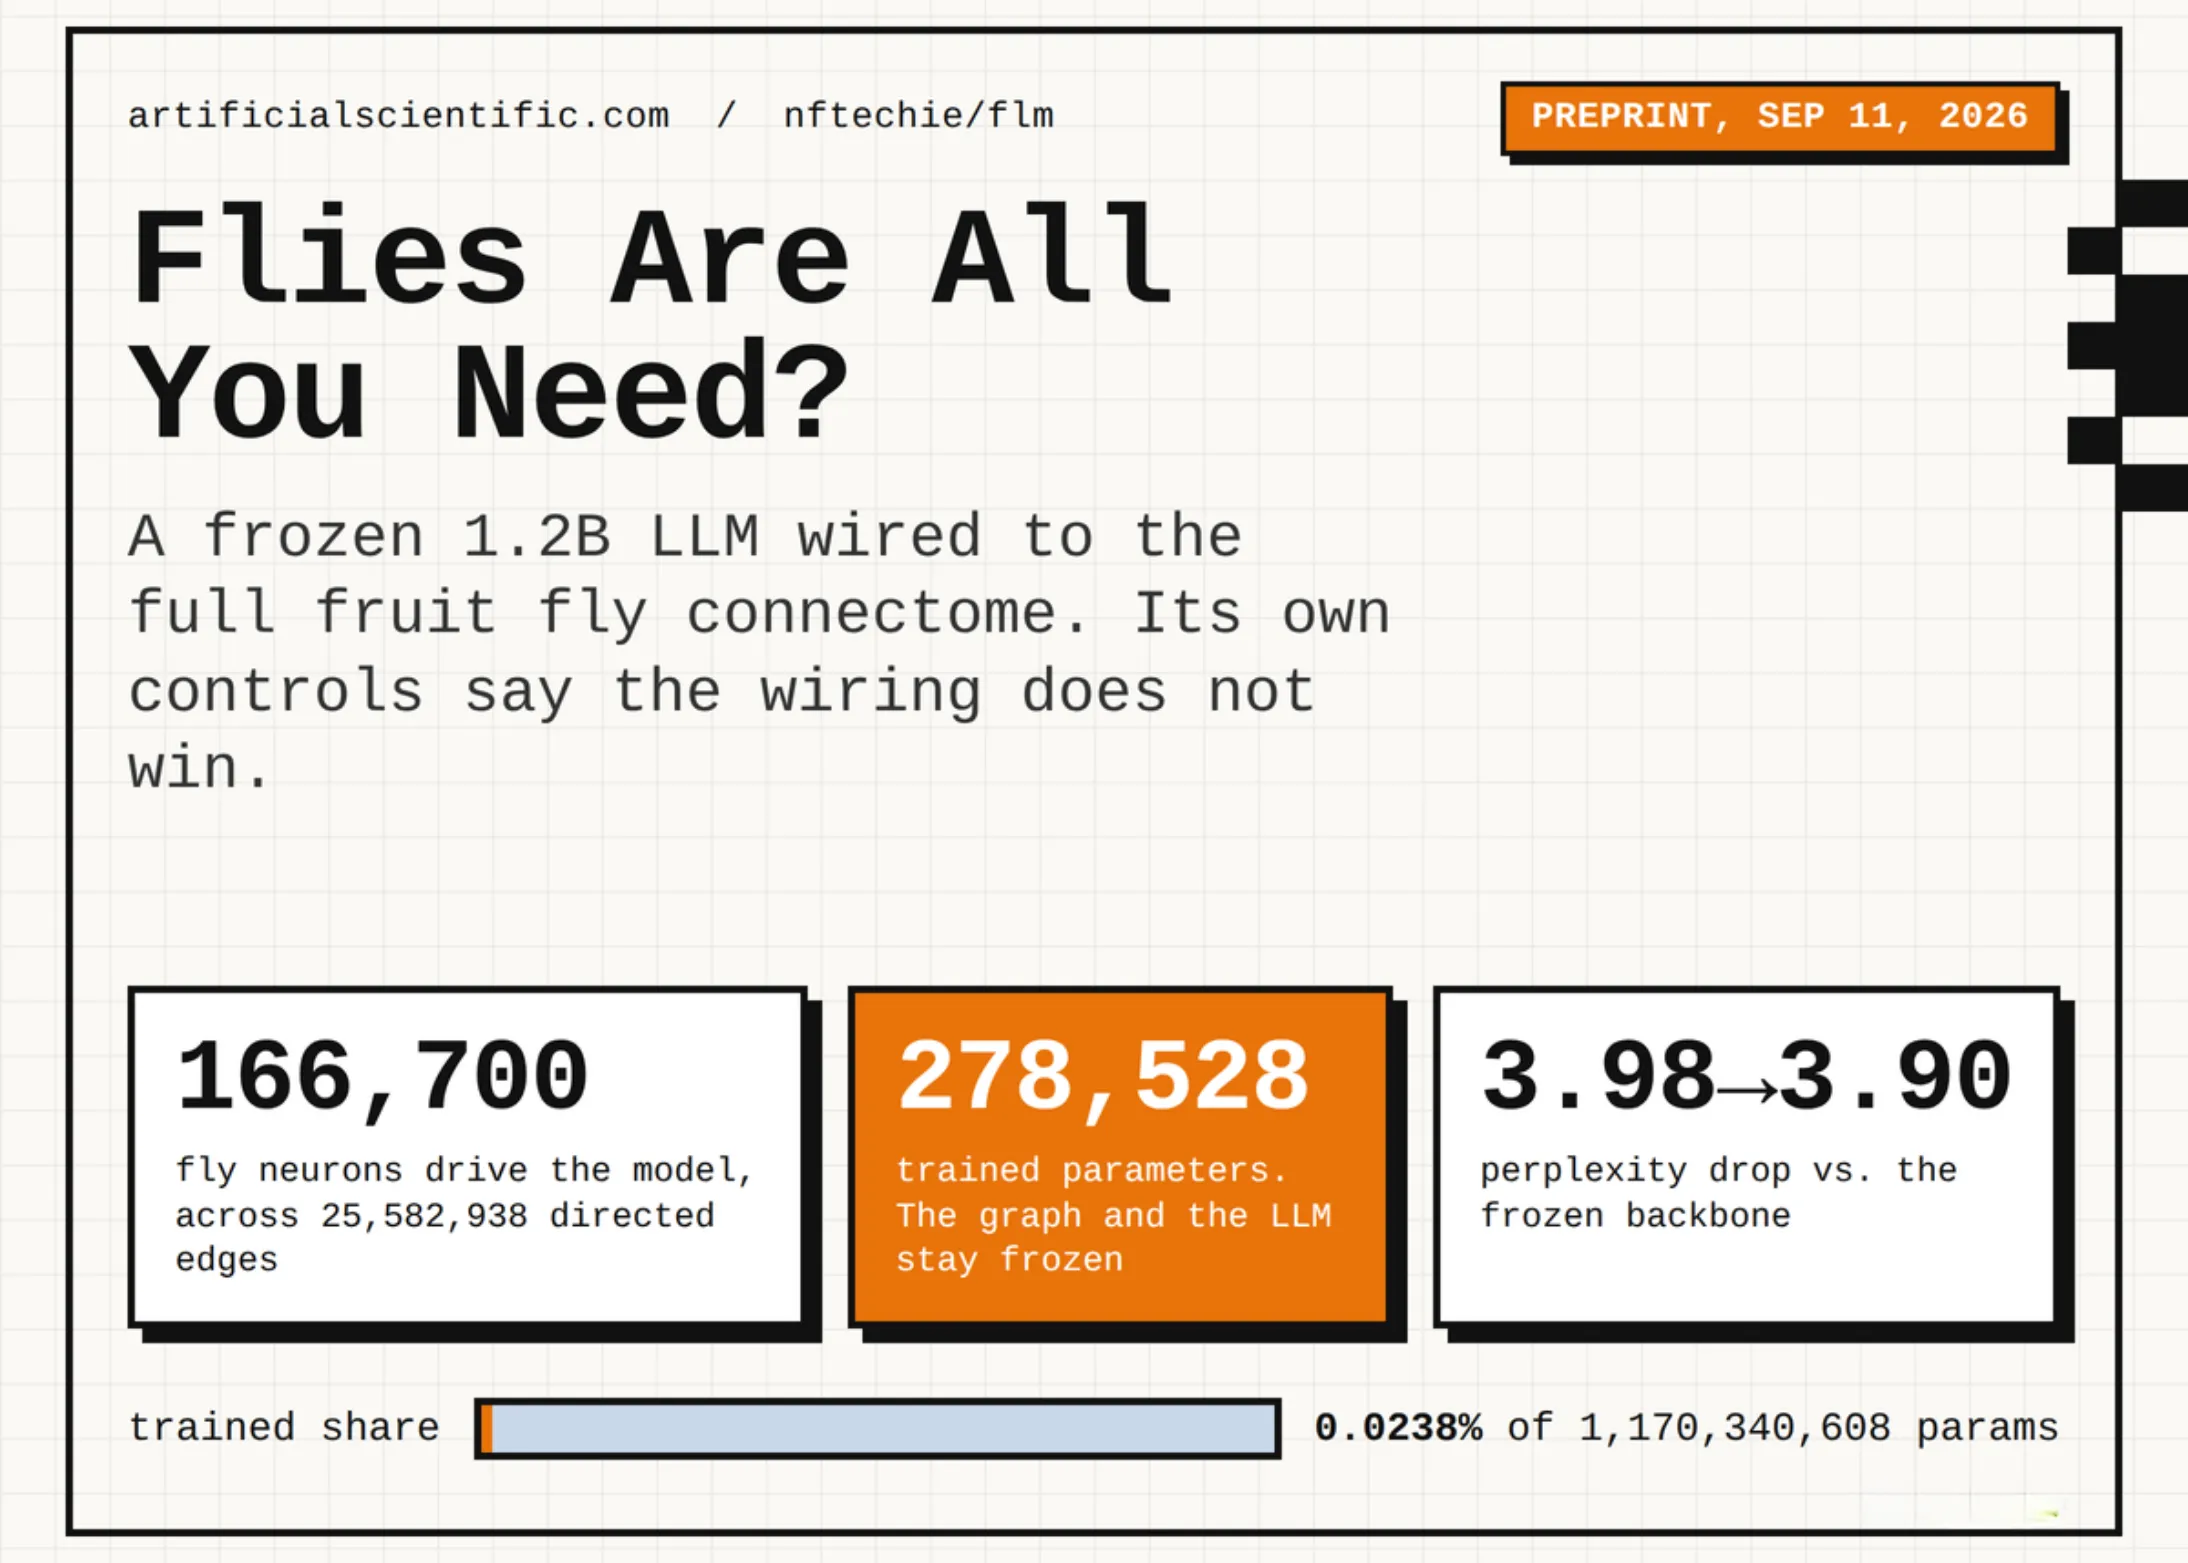
Fly Language Model (FLM) Wires the Full Fruit Fly Connectome Into a Frozen 1.2B LLM, and Its Own Controls Show the Wiring Does Not Help
The Fly Language Model (FLM) is a public chatbot that couples the complete retained MaleCNS v1.0 fruit fly connectome to […]

Anthropic Adds Plugin Evals to Claude Code: 6 Grader Types, a No-Plugin Baseline, and a CI Gate for Skills
Anthropic has published a new plugin evals workflow for Claude Code. The claude plugin eval command runs a plugin against […]

Sakana AI Launches Fugu Max and Fugu Ultra v2 for Cheaper, Stronger Multi-Agent Orchestration
Sakana AI has released Fugu Max and Fugu Ultra v2, 2 new models in its Sakana Fugu family. Fugu is […]

Meet Redis LangCache: A Managed Semantic Cache That Cuts LLM API Costs by Up to 90% and Returns Cache Hits Up to 15x Faster
Production LLM applications rarely receive a question nobody has asked before. Support assistants and RAG pipelines field the same intents […]

NVIDIA Details BioNeMo Inference Runtime (BioIR): 2.90x Higher Boltz-2 Folding Throughput and 58.5K Residues per GPU-Hour on 8xH100
Biomolecular structure prediction has shifted from single-target runs to proteome-scale worklists. The bottleneck is no longer whether a model can […]
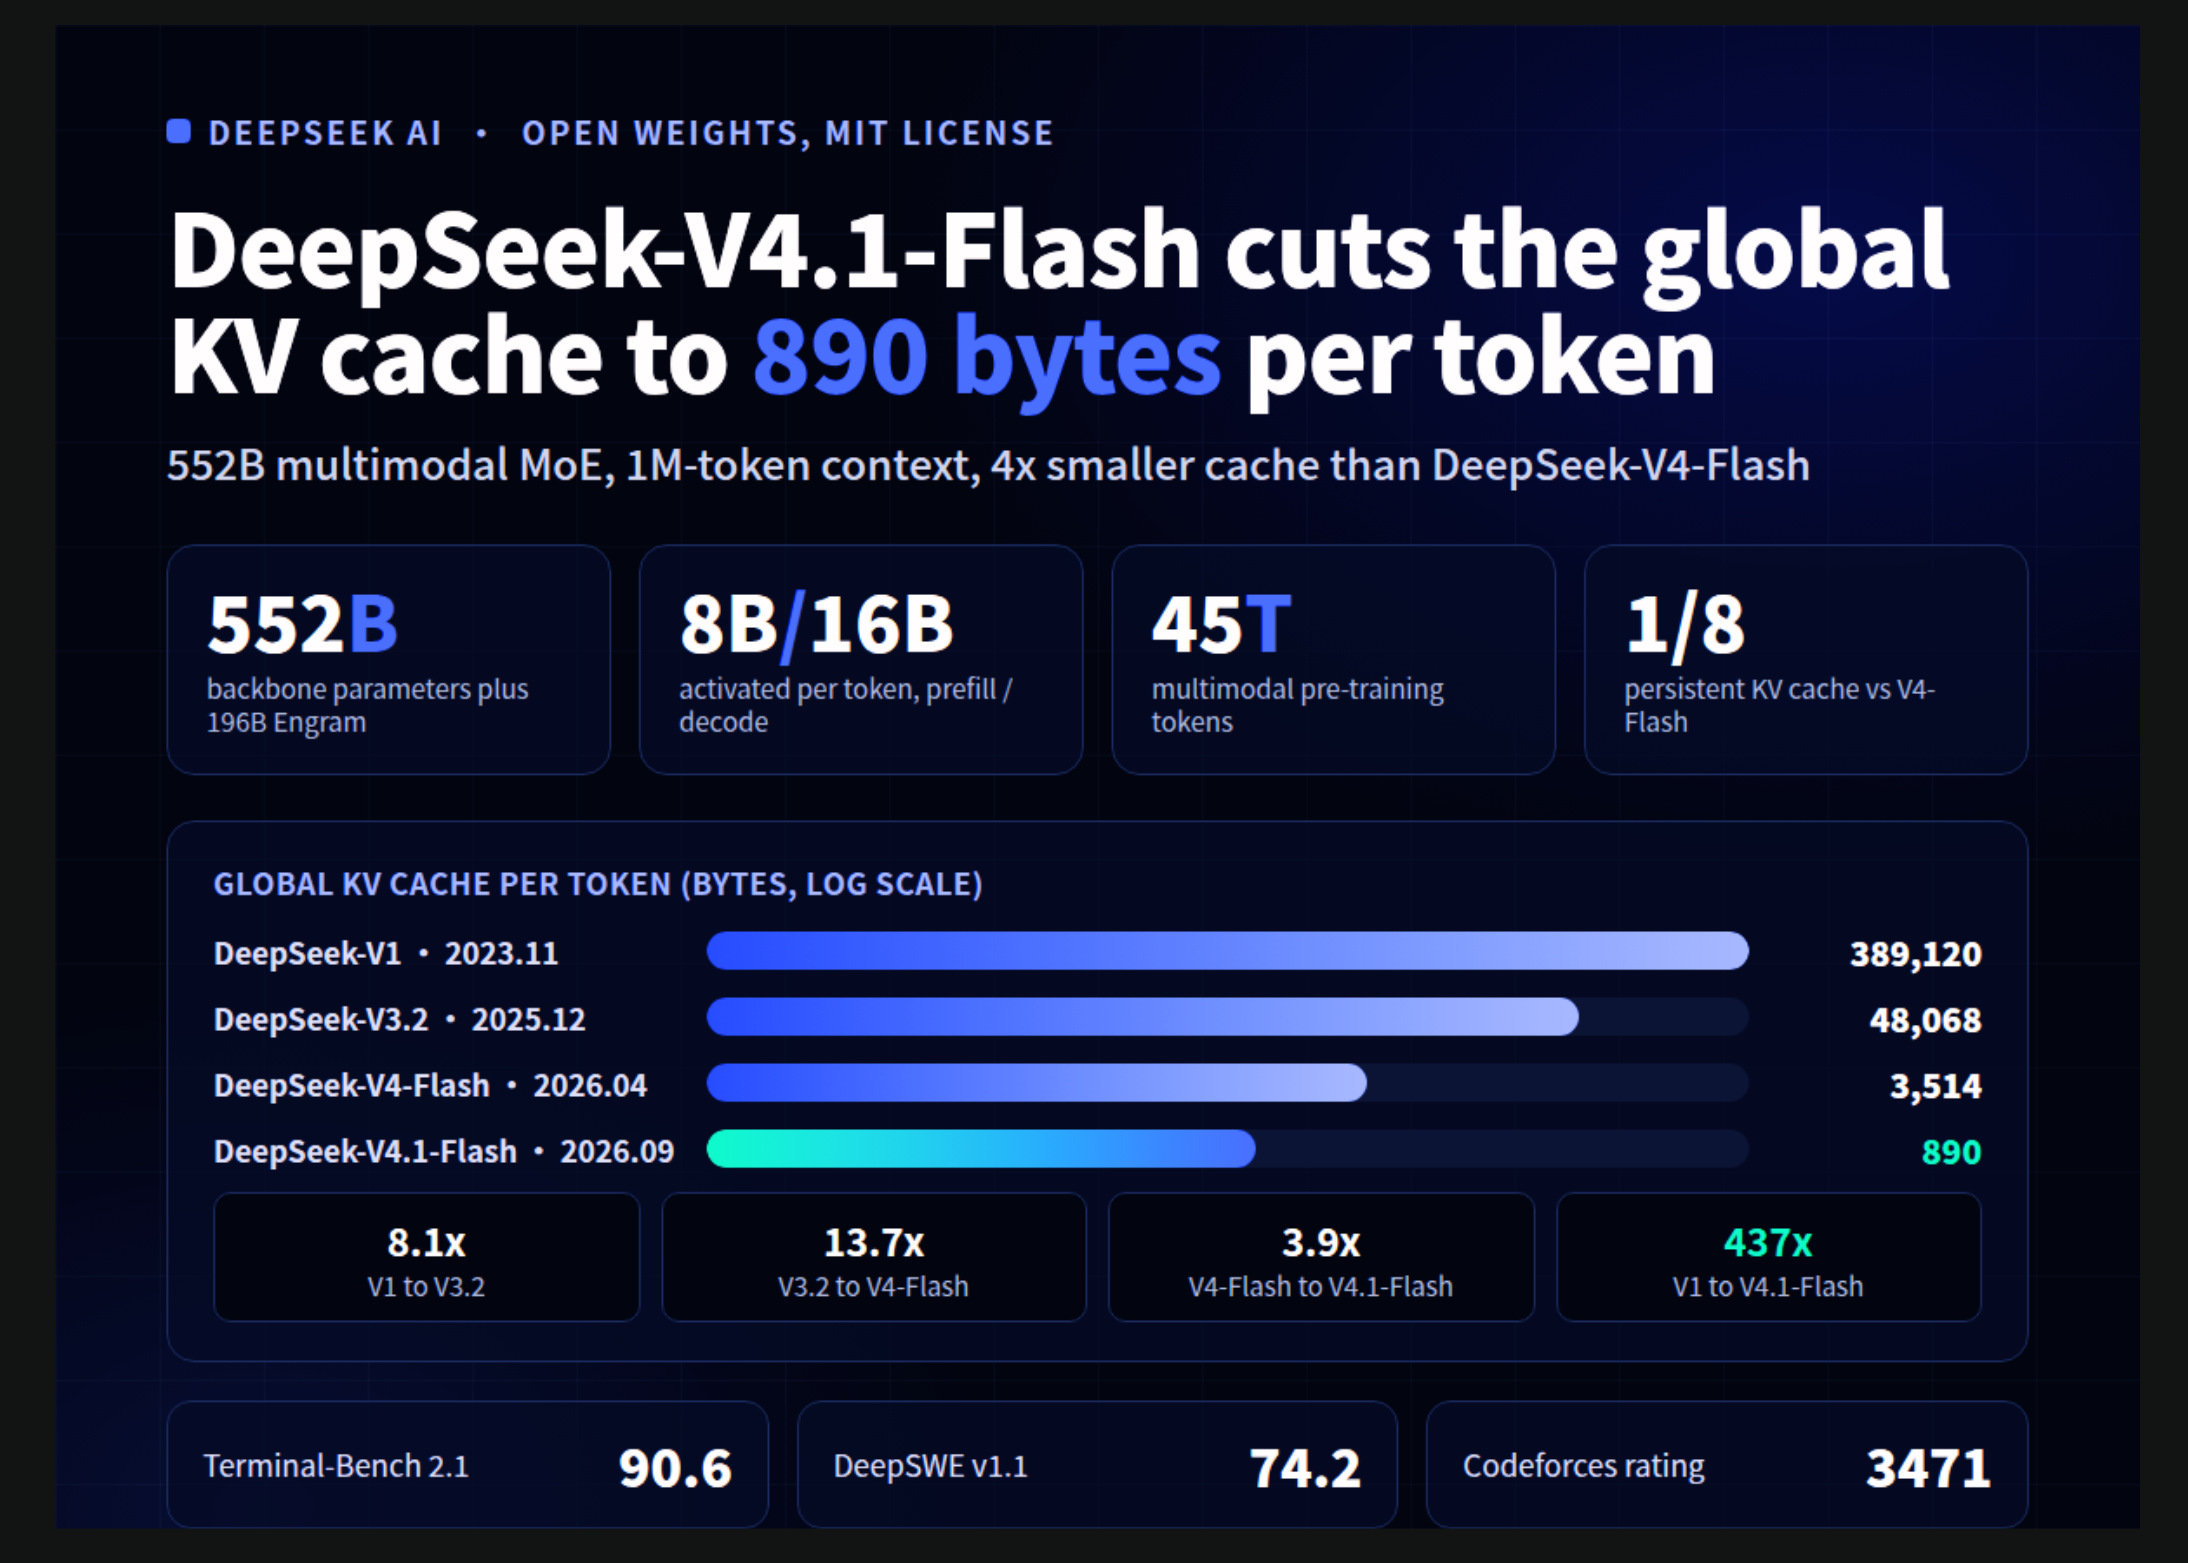
DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse
Long-horizon agents have turned LLM serving into an input-heavy workload. Repeated prefills and million-token contexts leave KV caches that strain […]