Run Google’s latest omni-capable open models faster on NVIDIA RTX AI PCs, from NVIDIA Jetson Orin Nano, GeForce RTX desktops […]
Category: Large Language Model

IBM Releases Granite 4.0 3B Vision: A New Vision Language Model for Enterprise Grade Document Data Extraction
IBM has announced the release of Granite 4.0 3B Vision, a vision-language model (VLM) engineered specifically for enterprise-grade document data […]
Z.ai Launches GLM-5V-Turbo: A Native Multimodal Vision Coding Model Optimized for OpenClaw and High-Capacity Agentic Engineering Workflows Everywhere
In the field of vision-language models (VLMs), the ability to bridge the gap between visual perception and logical code execution […]
Liquid AI Released LFM2.5-350M: A Compact 350M Parameter Model Trained on 28T Tokens with Scaled Reinforcement Learning
In the current landscape of generative AI, the ‘scaling laws’ have generally dictated that more parameters equal more intelligence. However, […]
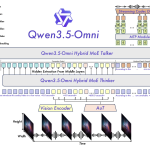
Alibaba Qwen Team Releases Qwen3.5 Omni: A Native Multimodal Model for Text, Audio, Video, and Realtime Interaction
The landscape of multimodal large language models (MLLMs) has shifted from experimental ‘wrappers’—where separate vision or audio encoders are stitched […]
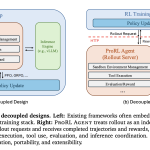
NVIDIA AI Unveils ProRL Agent: A Decoupled Rollout-as-a-Service Infrastructure for Reinforcement Learning of Multi-Turn LLM Agents at Scale
NVIDIA researchers introduced ProRL AGENT, a scalable infrastructure designed for reinforcement learning (RL) training of multi-turn LLM agents. By adopting […]
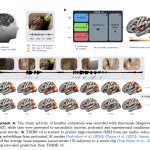
Meta Releases TRIBE v2: A Brain Encoding Model That Predicts fMRI Responses Across Video, Audio, and Text Stimuli
Neuroscience has long been a field of divide and conquer. Researchers typically map specific cognitive functions to isolated brain regions—like […]
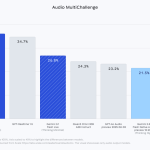
Google Releases Gemini 3.1 Flash Live: A Real-Time Multimodal Voice Model for Low-Latency Audio, Video, and Tool Use for AI Agents
Google has released Gemini 3.1 Flash Live in preview for developers through the Gemini Live API in Google AI Studio. […]
A Coding Implementation to Run Qwen3.5 Reasoning Models Distilled with Claude-Style Thinking Using GGUF and 4-Bit Quantization
In this tutorial, we work directly with Qwen3.5 models distilled with Claude-style reasoning and set up a Colab pipeline that […]
Paged Attention in Large Language Models LLMs
When running LLMs at scale, the real limitation is GPU memory rather than compute, mainly because each request requires a […]