Modern language models are trained on data with extremely uneven token distributions. A small number of words appear in almost […]
Category: Large Language Model
NVIDIA Introduces a 4-Bit Pretraining Methodology Using NVFP4, Validated on a 12B Hybrid Mamba-Transformer at 10T Token Horizon
Pretraining frontier-scale LLMs in FP8 is now standard practice, but moving to 4-bit floating point has remained an open research […]
A Coding Implementation to Compress and Benchmark Instruction-Tuned LLMs with FP8, GPTQ, and SmoothQuant Quantization using llmcompressor
In this tutorial, we explore how to apply post-training quantization to an instruction-tuned language model using llmcompressor. We start with […]
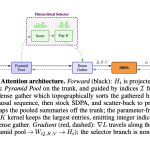
Nous Research Proposes Lighthouse Attention: A Training-Only Selection-Based Hierarchical Attention That Delivers 1.4–1.7× Pretraining Speedup at Long Context
Training large language models on long sequences has a well-known problem: attention is expensive. The scaled dot-product attention (SDPA) at […]
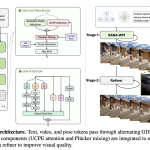
NVIDIA Introduces SANA-WM: A 2.6B-Parameter Open-Source World Model That Generates Minute-Scale 720p Video on a Single GPU
World models (systems that synthesize realistic video sequences from an initial image and a set of actions) are becoming central […]

Zyphra Releases ZAYA1-8B-Diffusion-Preview: The First MoE Diffusion Model Converted From an Autoregressive LLM With Up to 7.7x Speedup
Zyphra, the San Francisco-based AI lab behind the ZAYA1 model family, released ZAYA1-8B-Diffusion-Preview — a preview of its early work […]

Cline Releases Cline SDK: An Open-Source Agent Runtime Now Powering Its CLI and Kanban, With IDE Extensions Being Migrated
Cline became ‘agentic’ before it was cool, but building on the bleeding edge usually leads to some structural debt. Over […]
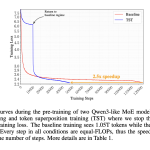
Nous Research Releases Token Superposition Training to Speed Up LLM Pre-Training by Up to 2.5x Across 270M to 10B Parameter Models
Pre-training large language models is expensive enough that even modest efficiency improvements can translate into meaningful cost and time savings. […]

Understanding LLM Distillation Techniques
Modern large language models are no longer trained only on raw internet text. Increasingly, companies are using powerful “teacher” models […]
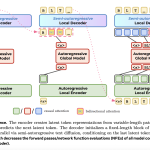
Meta and Stanford Researchers Propose Fast Byte Latent Transformer That Reduces Inference Memory Bandwidth by Over 50% Without Tokenization
A team of researchers from Meta, Stanford University, and the University of Washington have introduced three new methods that substantially […]