
In this tutorial, we explore Pyright, Microsoft’s high-performance static type checker for Python, and walk through its most powerful features […]
Category: Staff
IBM Releases Two Granite Speech 4.1 2B Models: Autoregressive ASR with Translation and Non-Autoregressive Editing for Fast Inference
IBM released two new open speech recognition models— Granite Speech 4.1 2B and Granite Speech 4.1 2B-NAR — and they […]

Cursor Introduces a TypeScript SDK for Building Programmatic Coding Agents With Sandboxed Cloud VMs, Subagents, Hooks, and Token-Based Pricing
Cursor, the AI-powered code editor, is opening up the core technology behind its coding agents to developers everywhere. The Cursor […]
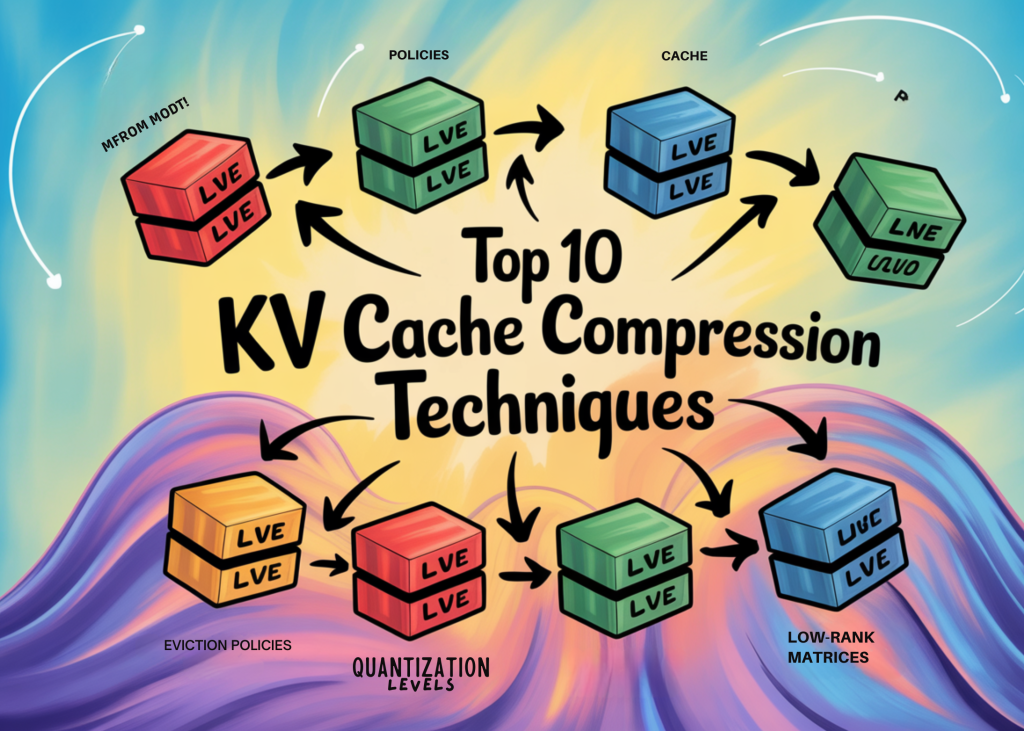
Top 10 KV Cache Compression Techniques for LLM Inference: Reducing Memory Overhead Across Eviction, Quantization, and Low-Rank Methods
As large language models scale to longer context windows and serve more concurrent users, the key-value (KV) cache has emerged […]

Qwen Team Releases FlashQLA: a High-Performance Linear Attention Kernel Library That Achieves Up to 3× Speedup on NVIDIA Hopper GPUs
The race to make large language models faster and cheaper to run has largely been fought at two levels: the […]

Step by Step Guide to Build a Complete PII Detection and Redaction Pipeline with OpenAI Privacy Filter
In this tutorial, we build a complete, production-style pipeline for detecting and redacting personally identifiable information using the OpenAI Privacy […]

Meta FAIR Releases NeuralSet: A Python Package for Neuro-AI That Supports fMRI, M/EEG, Spikes, and HuggingFace Embeddings
Researchers at Meta’s FAIR lab have released NeuralSet, a Python framework designed to eliminate one of the most persistent bottlenecks […]

smol-audio: A Colab-Friendly Notebook Collection for Fine-Tuning Whisper, Parakeet, Voxtral, Granite Speech, and Audio Flamingo 3
Audio AI has had a breakout year. Automatic speech recognition has gotten dramatically better with models like OpenAI’s Whisper variants, […]

A Coding Implementation on Document Parsing Benchmarking with LlamaIndex ParseBench Using Python, Hugging Face, and Evaluation Metrics
In this tutorial, we explore how to use the ParseBench dataset to evaluate document parsing systems in a structured, practical […]

Poolside AI Introduces Laguna XS.2 and M.1: Agentic Coding Models Reaching 68.2% and 72.5% on SWE-bench Verified
Poolside AI released the first two models in its Laguna family: Laguna M.1 and Laguna XS.2. Alongside these, the company […]