Google has open-sourced the Elephant-Goldfish Model (EGM) plugin, a design-and-review layer for AI coding agents. The Elephant-Goldfish Model plugin makes […]
Category: Staff
Which Routing Does Each MoE Model Use? DeepSeek, Qwen, Mixtral, Llama 4, gpt-oss Compared
Open Mixture-of-Experts (MoE) models share one idea but disagree on almost every routing detail. Expert counts range from 8 to […]
MoE Routing Strategies Explained: Top-K, Expert-Choice, Sigmoid Gating and Dynamic Routing (2026 Guide)
Every Mixture-of-Experts (MoE) model repeats one decision for every token: which experts should process it. That decision belongs to the […]
Nous Research Releases Arete-27B that Cuts Qwen3.8-27B Propaganda From 22% to 0.9%
Nous Research has released Arete-27B, a supervised fine-tune of Alibaba’s Qwen3.8-27B. Arete-27B is a 27B open-weight model that strips Chinese […]
How to Run NVIDIA Dory 4B with llama.cpp: Loop by Loop Guide
In this tutorial, we work with Dory 1.0 4B, a small reasoning model from NVIDIA’s Nemotron Labs whose middle layers […]
Buoyant Releases Kinference: An Open Source Inference Control Plane for Kubernetes and vLLM
Buoyant, the company behind Linkerd, has released Kinference, an open source project for building inference platforms on Kubernetes. Kinference is […]
Zyphra ZYFA: FP8 FlashAttention for AMD MI355X, Up to 1.76x Faster
Zyphra has released ZYFA (Zyphra FlashAttention on AMD), a set of FP8 and BF16 prefill attention kernels for AMD Instinct […]

Thinking Machines Releases Inkling 2 Small, a 594B MoE With 17B Active
Thinking Machines Lab has released Inkling 2 Small, the first model of its second Inkling generation. The Inkling 2 Small […]
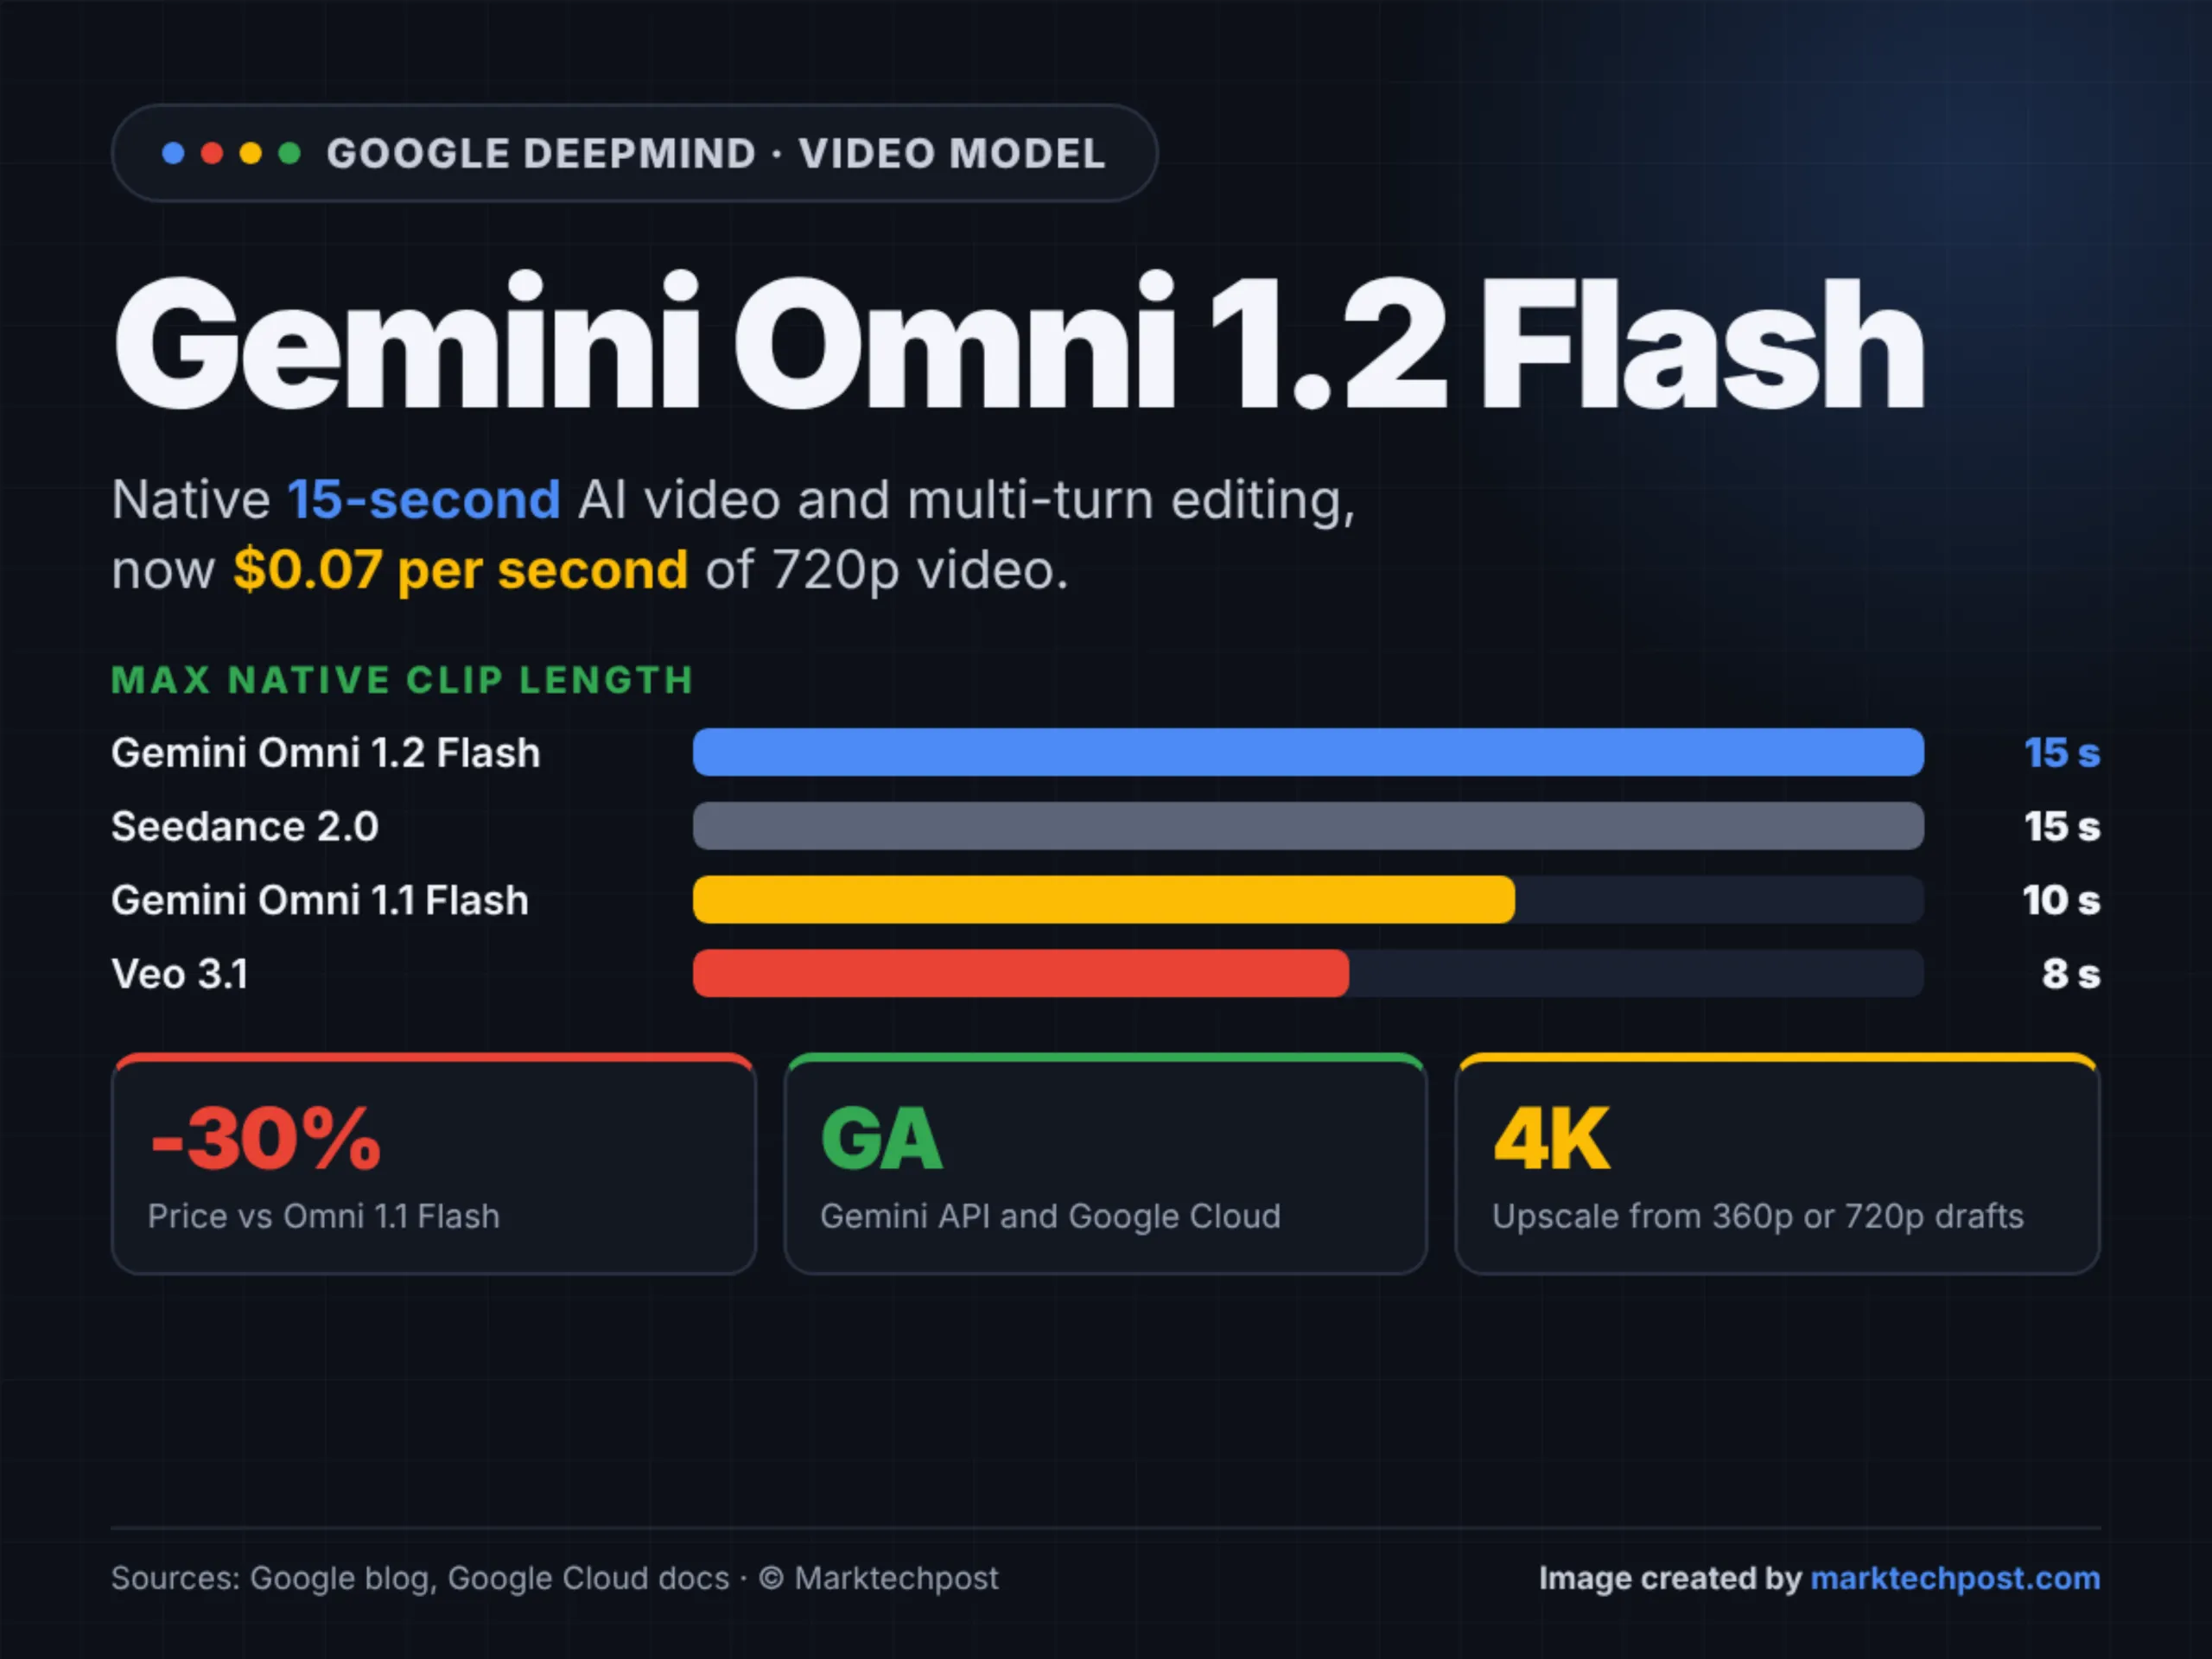
Google Releases Gemini Omni 1.2 Flash: 15-Second AI Video at $0.07 per Second
Google has released Gemini Omni 1.2 Flash, the newest version of its video generation and editing model. Gemini Omni 1.2 […]
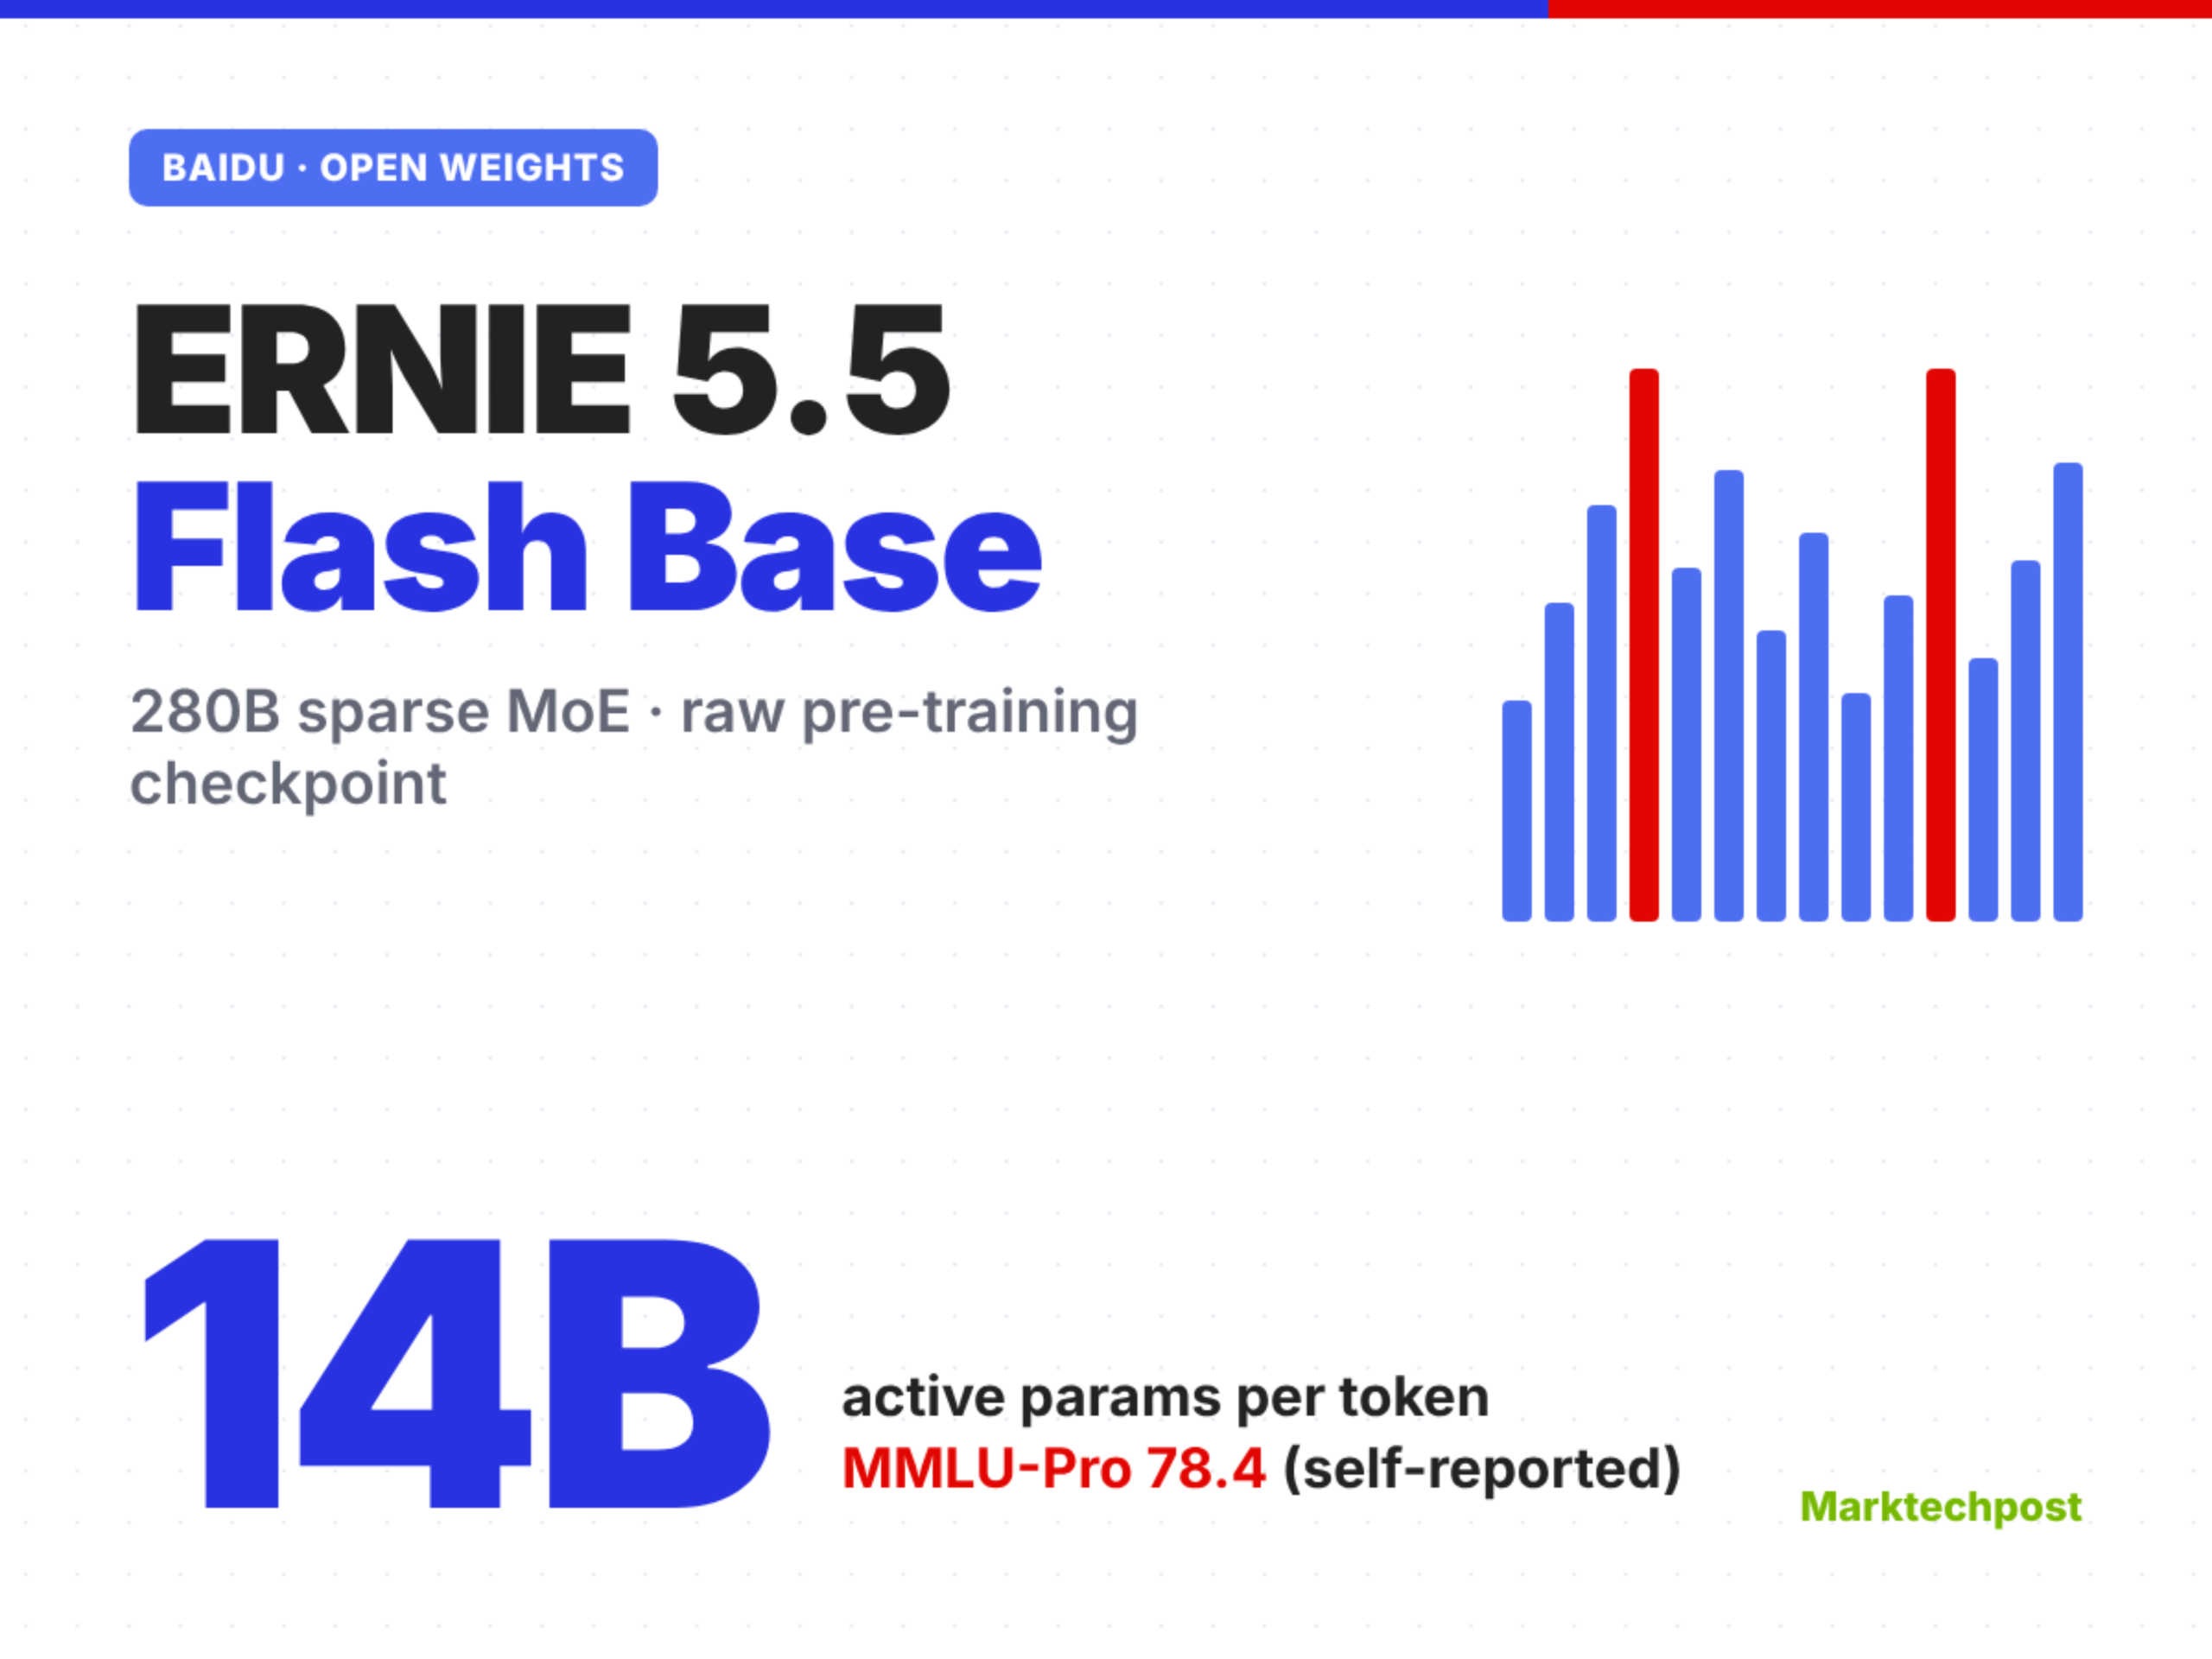
Baidu Releases ERNIE 5.5 Flash Base: A 280B MoE Base Model With 14B Active Parameters
Baidu has released ERNIE 5.5 Flash Base, the raw pre-training checkpoint of its new sparse Mixture-of-Experts language model. ERNIE 5.5 […]