IBM released two new open speech recognition models— Granite Speech 4.1 2B and Granite Speech 4.1 2B-NAR — and they […]
Category: Audio Language Model

smol-audio: A Colab-Friendly Notebook Collection for Fine-Tuning Whisper, Parakeet, Voxtral, Granite Speech, and Audio Flamingo 3
Audio AI has had a breakout year. Automatic speech recognition has gotten dramatically better with models like OpenAI’s Whisper variants, […]

OpenMOSS Releases MOSS-Audio: An Open-Source Foundation Model for Speech, Sound, Music, and Time-Aware Audio Reasoning
Understanding what’s happening in an audio clip is a deceptively hard problem. Transcribing spoken words is the easy part. A […]
xAI Launches grok-voice-think-fast-1.0: Topping τ-voice Bench at 67.3%, Outperforming Gemini, GPT Realtime, and More
Building a production-grade voice AI agent is one of the hardest engineering challenges in applied machine learning today. It is […]
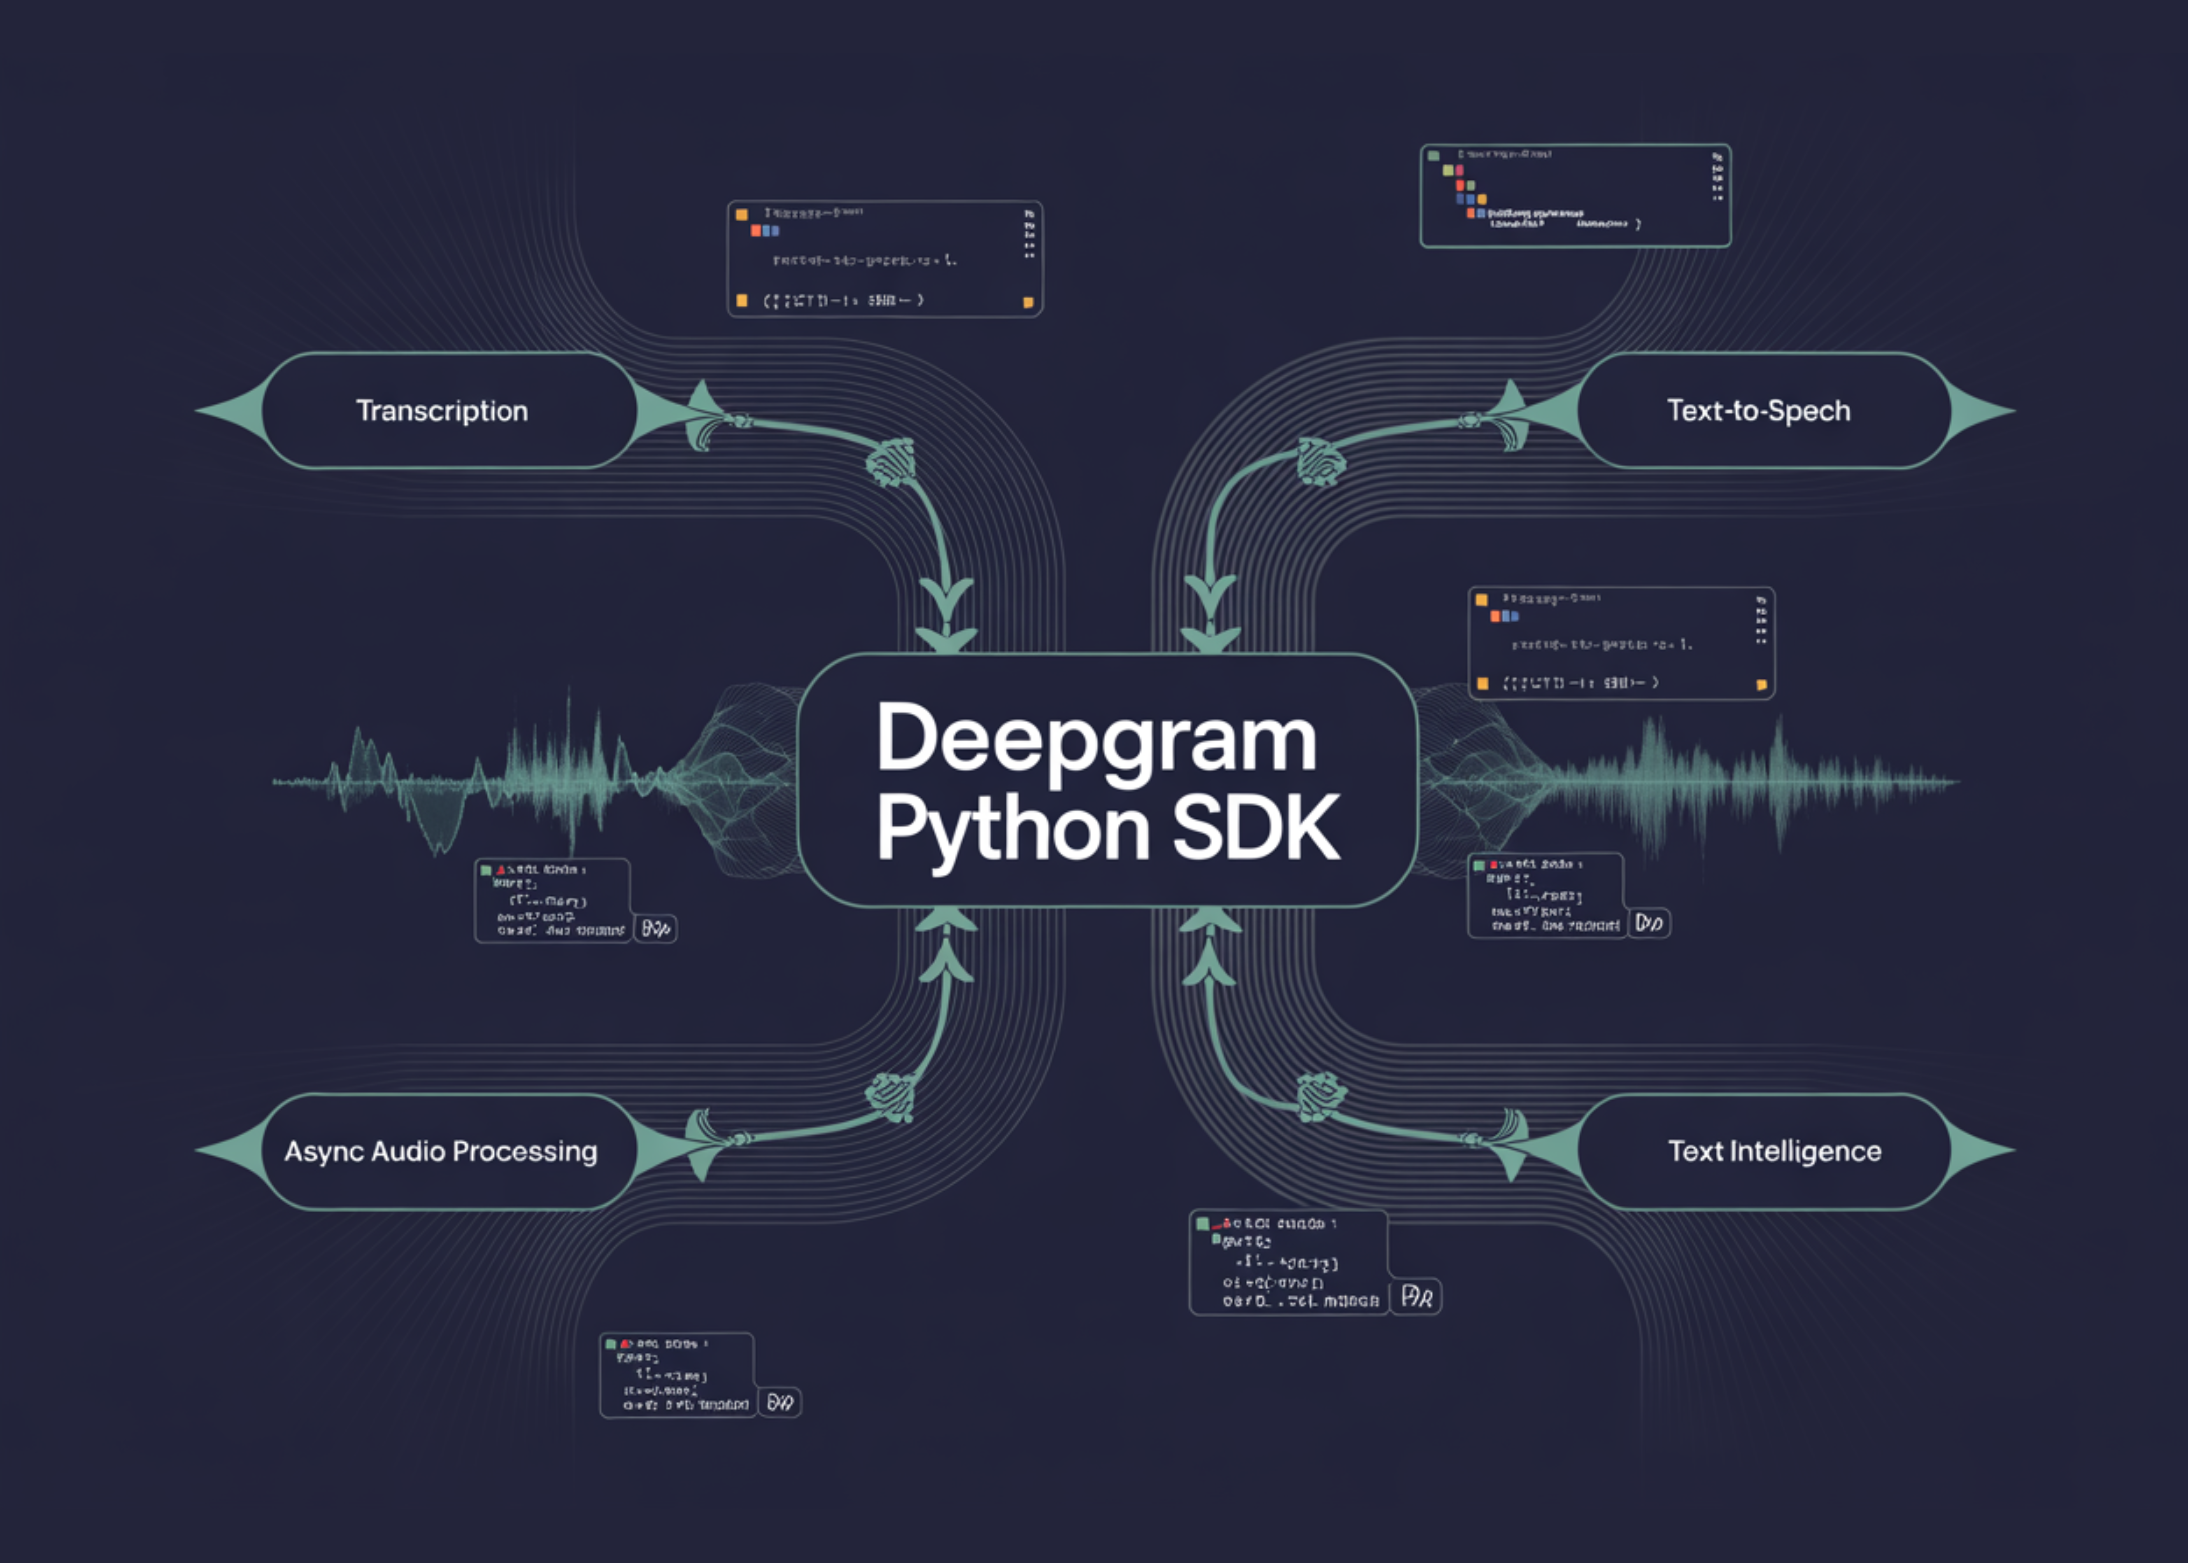
A Coding Implementation on Deepgram Python SDK for Transcription, Text-to-Speech, Async Audio Processing, and Text Intelligence
In this tutorial, we build an advanced hands-on workflow with the Deepgram Python SDK and explore how modern voice AI […]
xAI Launches Standalone Grok Speech-to-Text and Text-to-Speech APIs, Targeting Enterprise Voice Developers
Elon Musk’s AI company xAI has launched two standalone audio APIs — a Speech-to-Text (STT) API and a Text-to-Speech (TTS) […]
Google AI Launches Gemini 3.1 Flash TTS: A New Benchmark in Expressive and Controllable AI Voice
Google has introduced Gemini 3.1 Flash TTS, a preview text-to-speech model focused on improving speech quality, expressive control, and multilingual […]
NVIDIA and the University of Maryland Researchers Released Audio Flamingo Next (AF-Next): A Super Powerful and Open Large Audio-Language Model
Understanding audio has always been the multimodal frontier that lags behind vision. While image-language models have rapidly scaled toward real-world […]
A Hands-On Coding Tutorial for Microsoft VibeVoice Covering Speaker-Aware ASR, Real-Time TTS, and Speech-to-Speech Pipelines
In this tutorial, we explore Microsoft VibeVoice in Colab and build a complete hands-on workflow for both speech recognition and […]
Alibaba Qwen Team Releases Qwen3.5 Omni: A Native Multimodal Model for Text, Audio, Video, and Realtime Interaction
The landscape of multimodal large language models (MLLMs) has shifted from experimental ‘wrappers’—where separate vision or audio encoders are stitched […]