Skip to content
Tuesday, September 22, 2026
The TechBriefs
  • Home
  • Technology
  • AI
  • Computers
  • Security
  • Internet
  • Press Releases
    • GlobeNewswire
    • PRNewswire
  • Contact

Category: Audio Language Model

  • Home
  • Audio Language Model
  • Page 3
OpenAI Releases GPT-Realtime-2.1 and GPT-Realtime-2.1-mini for Low-Latency Voice Agents in the API
  • agentic AI
  • AI
  • AI Shorts
  • Applications
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • Large Language Model
  • Machine Learning
  • New Releases
  • Software Engineering
  • Staff
  • Tech News
  • Technology
  • TTS
  • Voice AI

OpenAI Releases GPT-Realtime-2.1 and GPT-Realtime-2.1-mini for Low-Latency Voice Agents in the API

  • 0

OpenAI has released two new Realtime models in its API. They are named gpt-realtime-2.1 and gpt-realtime-2.1-mini. Both target low-latency voice […]

Interfaze Ships diffusion-gemma-asr-small, an Open-Source Diffusion ASR Model Transcribing Six Languages via DiffusionGemma’s Parallel Denoising Decoder
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Open Source
  • Technology
  • TTS
  • Voice AI

Interfaze Ships diffusion-gemma-asr-small, an Open-Source Diffusion ASR Model Transcribing Six Languages via DiffusionGemma’s Parallel Denoising Decoder

  • 0

Interfaze, a young YC’s startup, has open-sourced a new speech recognition model. It is called diffusion-gemma-asr-small. The model transcribes audio […]
Gradium Launches stt-translate and s2s-translate, Real-Time Speech Translation Models Beating gpt-realtime-translate on Accuracy and Latency
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Staff
  • Technology
  • Voice AI

Gradium Launches stt-translate and s2s-translate, Real-Time Speech Translation Models Beating gpt-realtime-translate on Accuracy and Latency

  • 0

Gradium today released two real-time speech translation models: stt-translate and s2s-translate. Both run across five languages and stream results live […]
How to Use NVIDIA Canary-1B-v2 for ASR, Translation, and Automatic SRT Subtitle Export in Python
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • Staff
  • Technology
  • Tutorials
  • Voice AI

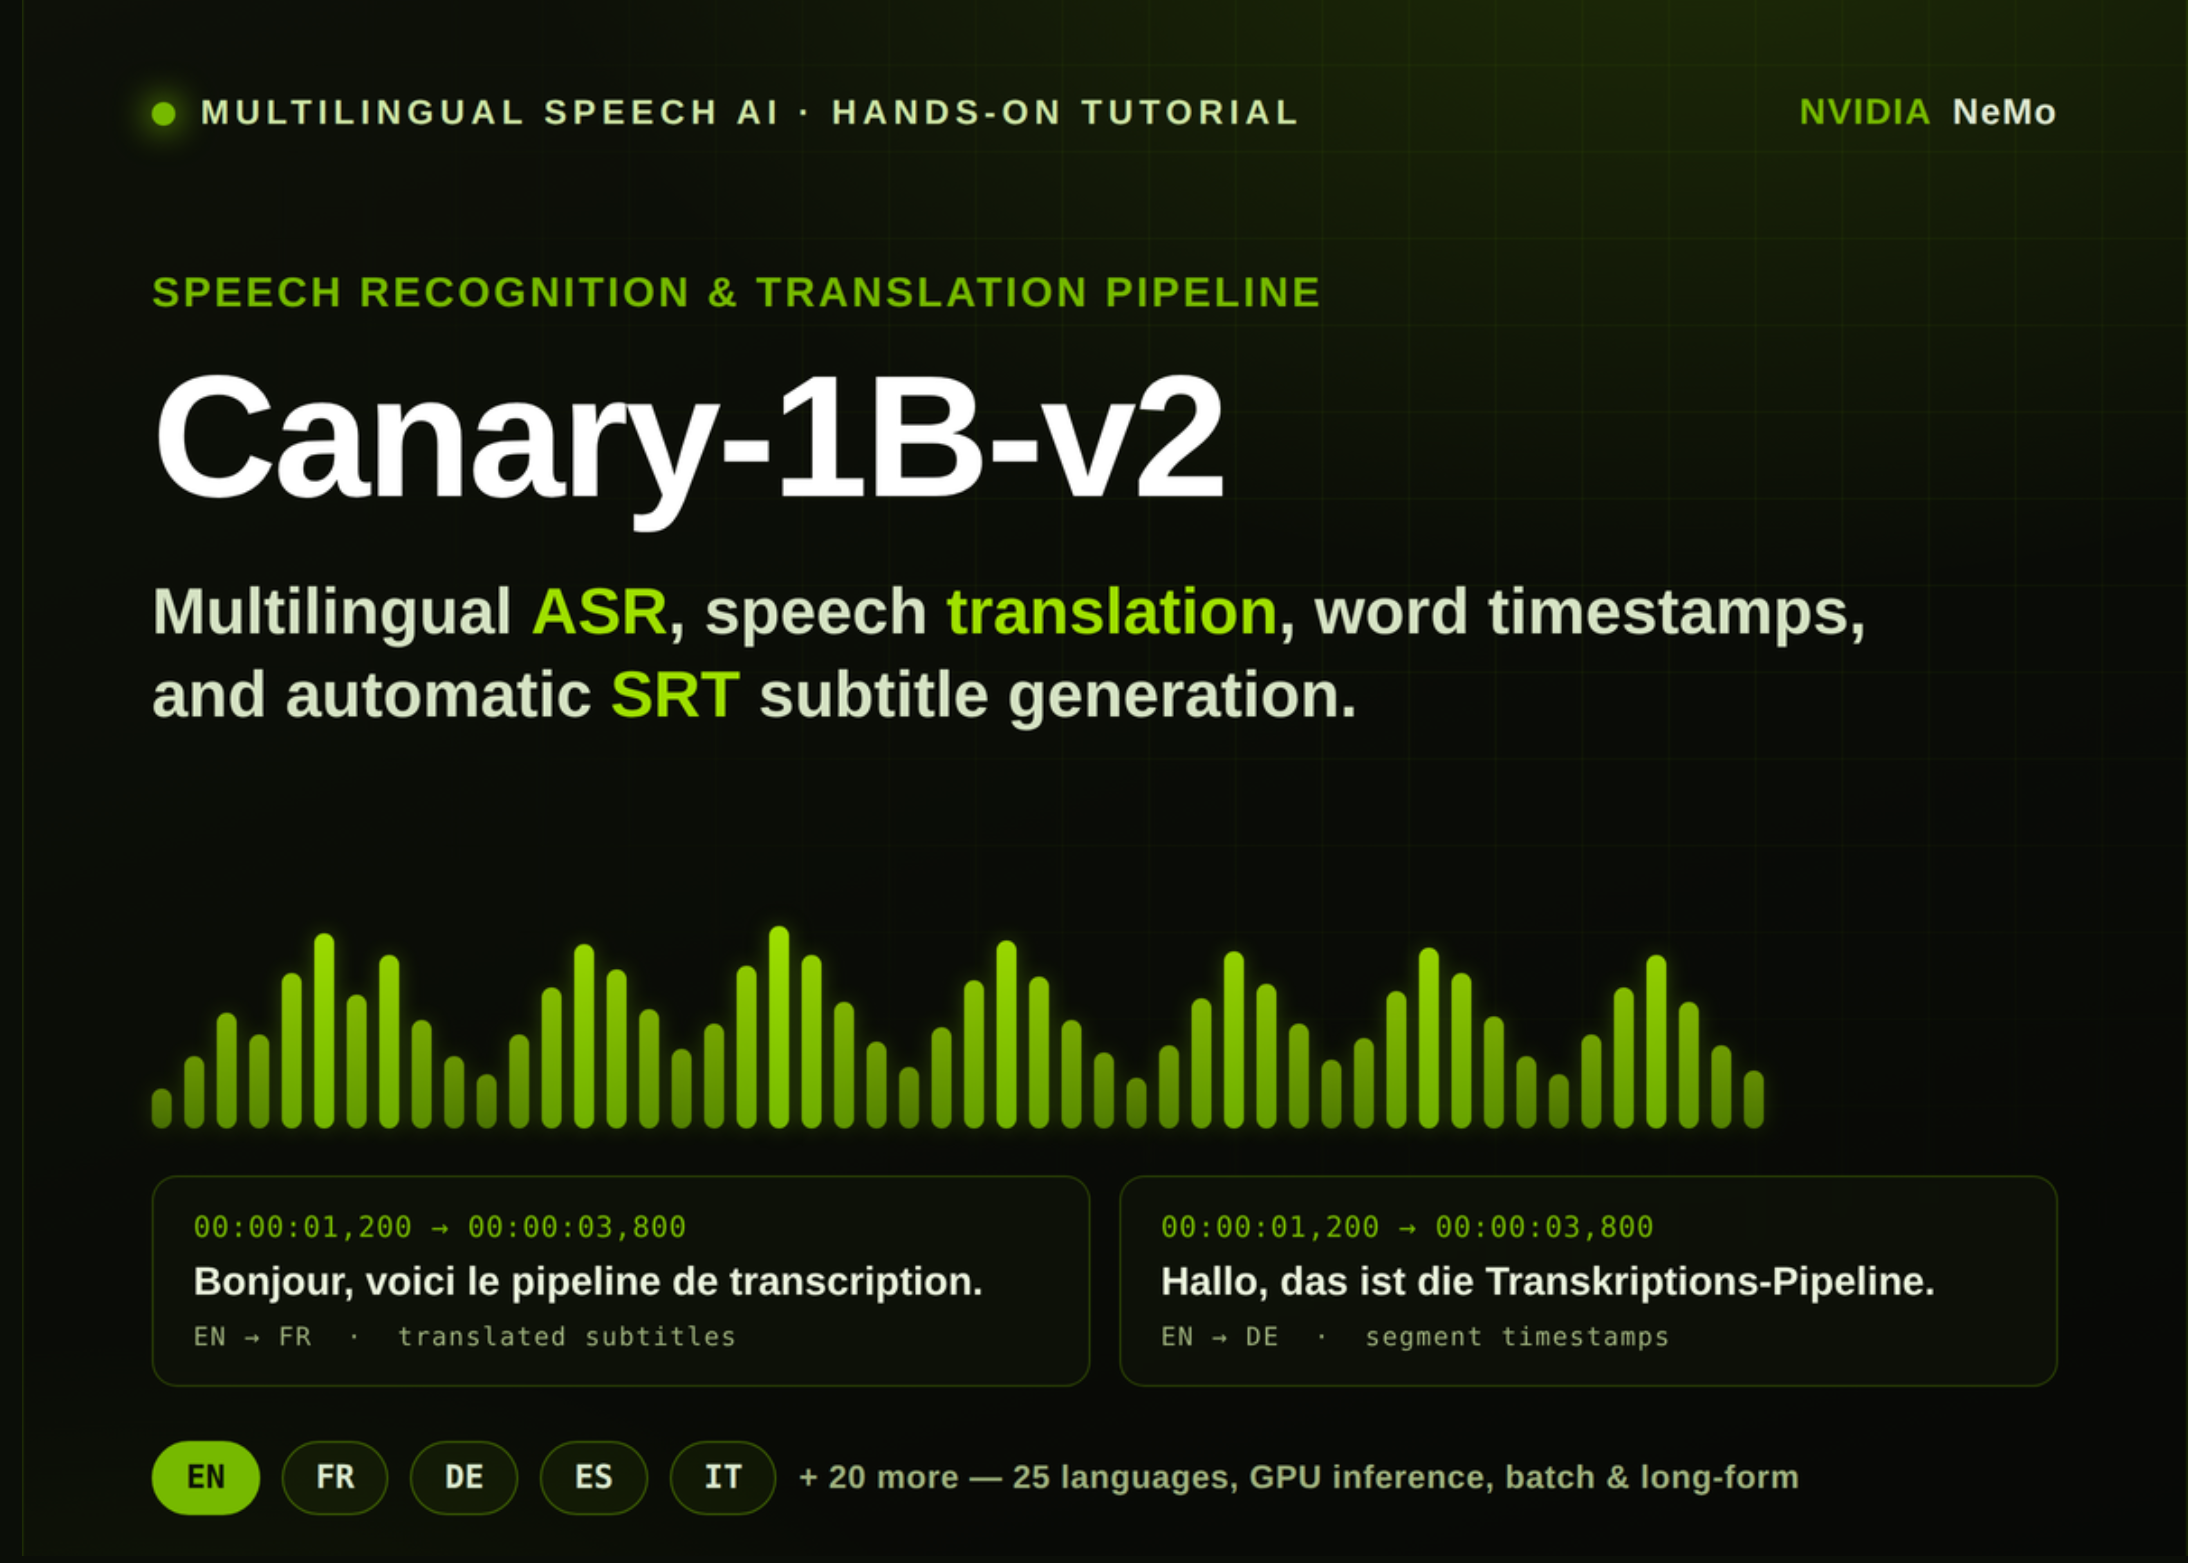
How to Use NVIDIA Canary-1B-v2 for ASR, Translation, and Automatic SRT Subtitle Export in Python

  • 0

In this tutorial, we build a speech recognition and translation workflow using NVIDIA Canary-1B-v2. We begin by setting up the […]
Google Releases Gemini 3.5 Live Translate, a Streaming Speech-to-Speech Audio Model Covering 70+ Languages Across Meet, Translate, and the Live API
  • agentic AI
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Software Engineering
  • Staff
  • Technology
  • Voice AI

Google Releases Gemini 3.5 Live Translate, a Streaming Speech-to-Speech Audio Model Covering 70+ Languages Across Meet, Translate, and the Live API

  • 0

Google just announced Gemini 3.5 Live Translate. It is their latest audio model for live speech-to-speech translation. Speech-to-speech means spoken […]
Microsoft AI Introduces MAI-Transcribe-1.5: 2.4% WER on Artificial Analysis, Best-in-Class FLEURS Accuracy, and Up to 5x Faster Long-Audio Transcription
  • agentic AI
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Software Engineering
  • Staff
  • Technology
  • Voice AI

Microsoft AI Introduces MAI-Transcribe-1.5: 2.4% WER on Artificial Analysis, Best-in-Class FLEURS Accuracy, and Up to 5x Faster Long-Audio Transcription

  • 0

Last week Microsoft AI has announced MAI-Transcribe-1.5. It is the second iteration of the company’s in-house speech-to-text family. The model […]
NVIDIA Releases Nemotron 3.5 ASR: A 600M-Parameter Cache-Aware Streaming Model Transcribing 40 Language-Locales in Real Time
  • agentic AI
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Software Engineering
  • Staff
  • Technology
  • Voice AI

NVIDIA Releases Nemotron 3.5 ASR: A 600M-Parameter Cache-Aware Streaming Model Transcribing 40 Language-Locales in Real Time

  • 0

NVIDIA’s Nemotron Speech team has released Nemotron 3.5 ASR. It is a 600M-parameter streaming Automatic Speech Recognition (ASR) model. A […]
Miso Labs Releases MisoTTS: An 8B Emotive Text-to-Speech Model with Open Weights
  • agentic AI
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Open Source
  • Software Engineering
  • Staff
  • Technology
  • TTS
  • Voice AI

Miso Labs Releases MisoTTS: An 8B Emotive Text-to-Speech Model with Open Weights

  • 0

Miso Labs has released MisoTTS, an open-weights 8-billion-parameter text-to-speech model. It generates expressive speech from both text and audio context. […]
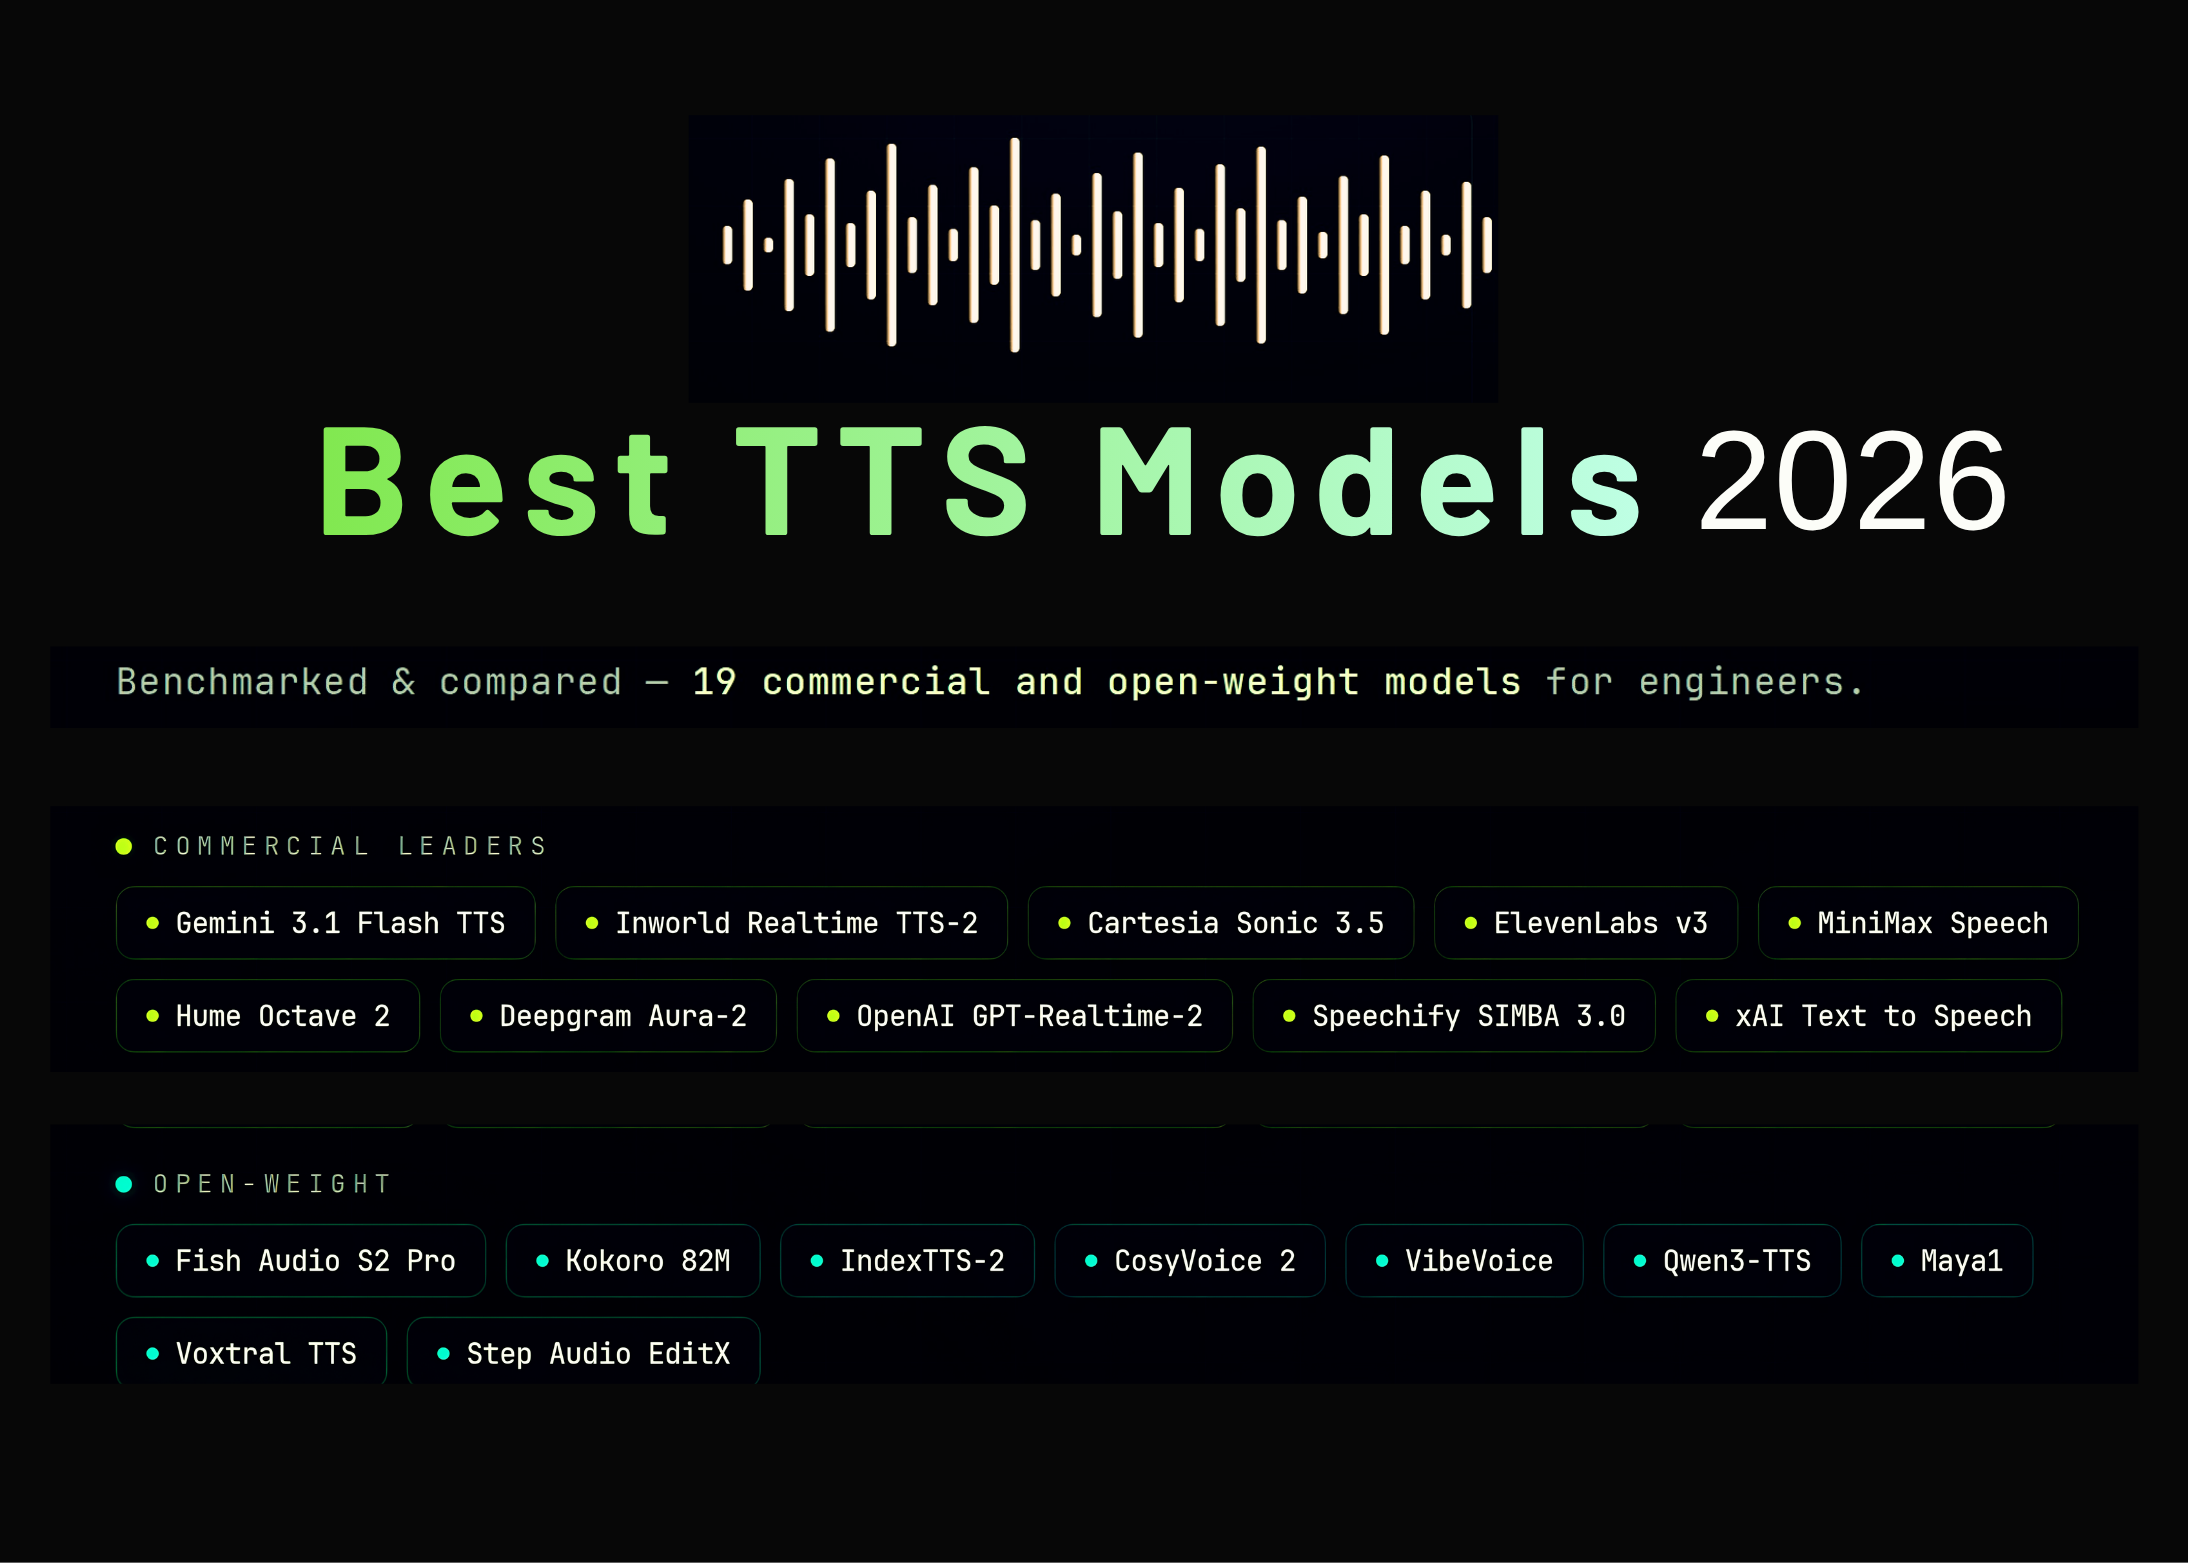
Best Text-to-Speech TTS Models in 2026: A Benchmark-Based Comparison
  • agentic AI
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • Staff
  • Technology
  • Text to Audio
  • Top
  • TTS
  • Voice AI

Best Text-to-Speech TTS Models in 2026: A Benchmark-Based Comparison

  • 0

Text-to-speech TTS moved fast over the past year. The line between synthetic and human speech narrowed. Latency dropped below 100 […]
Stability AI Releases Stable Audio 3: A Family of Fast Latent Diffusion Models for Audio Generation and Editing
  • AI
  • Artificial Intelligence
  • Audio Language Model
  • Editors Pick
  • Language Model
  • New Releases
  • Software Engineering
  • Staff
  • Technology
  • Voice AI

Stability AI Releases Stable Audio 3: A Family of Fast Latent Diffusion Models for Audio Generation and Editing

  • 0

Stability AI has released open weights for Stable Audio 3 along with a technical research paper. Stable Audio 3 is […]

Posts pagination

Previous 1 2 3 4 … 10 Next
  • Privacy Policy
  • Terms of use
Theme: Terminal News By Adore Themes.