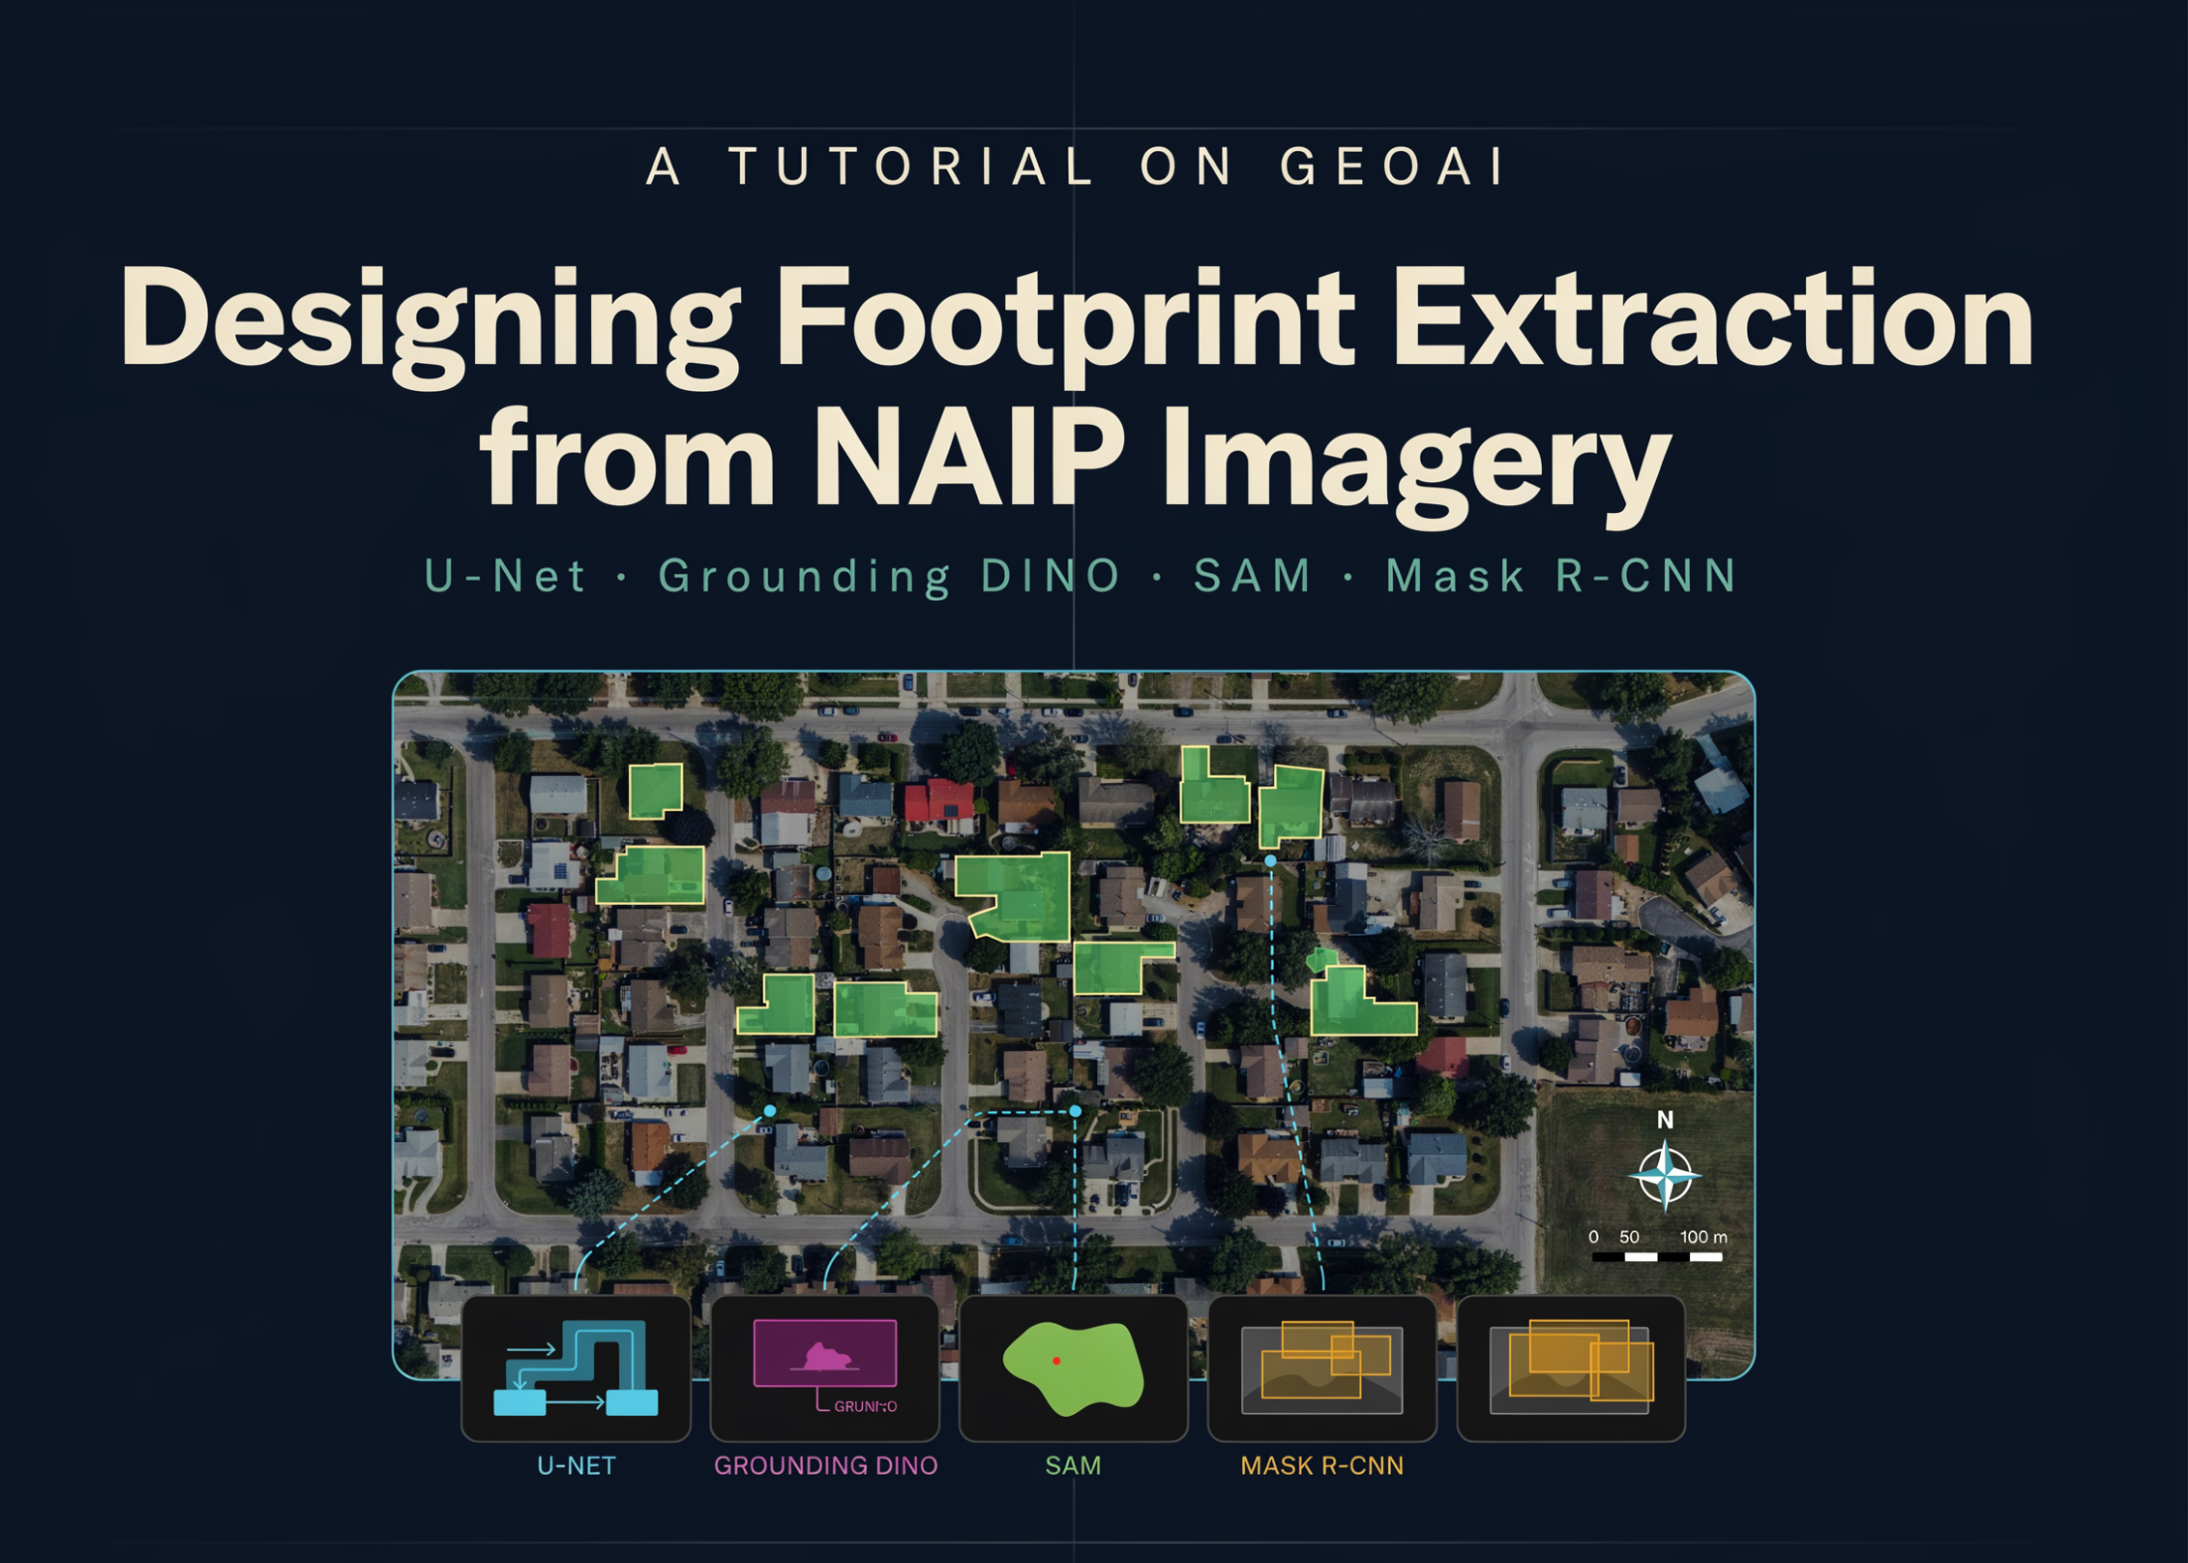
In this tutorial, we design a complete GeoAI workflow for extracting building footprints from high-resolution NAIP aerial imagery. We begin […]
Category: Computer Vision
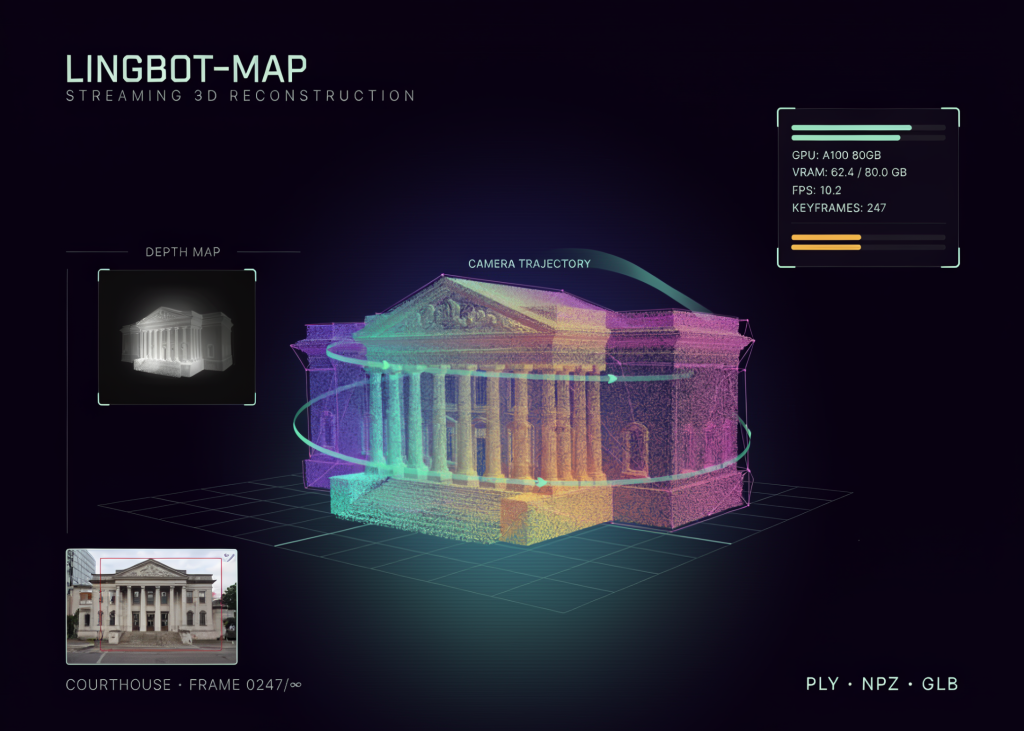
LingBot-Map Tutorial: GPU-Aware Inference and Point Cloud Export
In this tutorial, we implement an end-to-end streaming 3D reconstruction pipeline with LingBot-Map. We begin by configuring the input source, […]
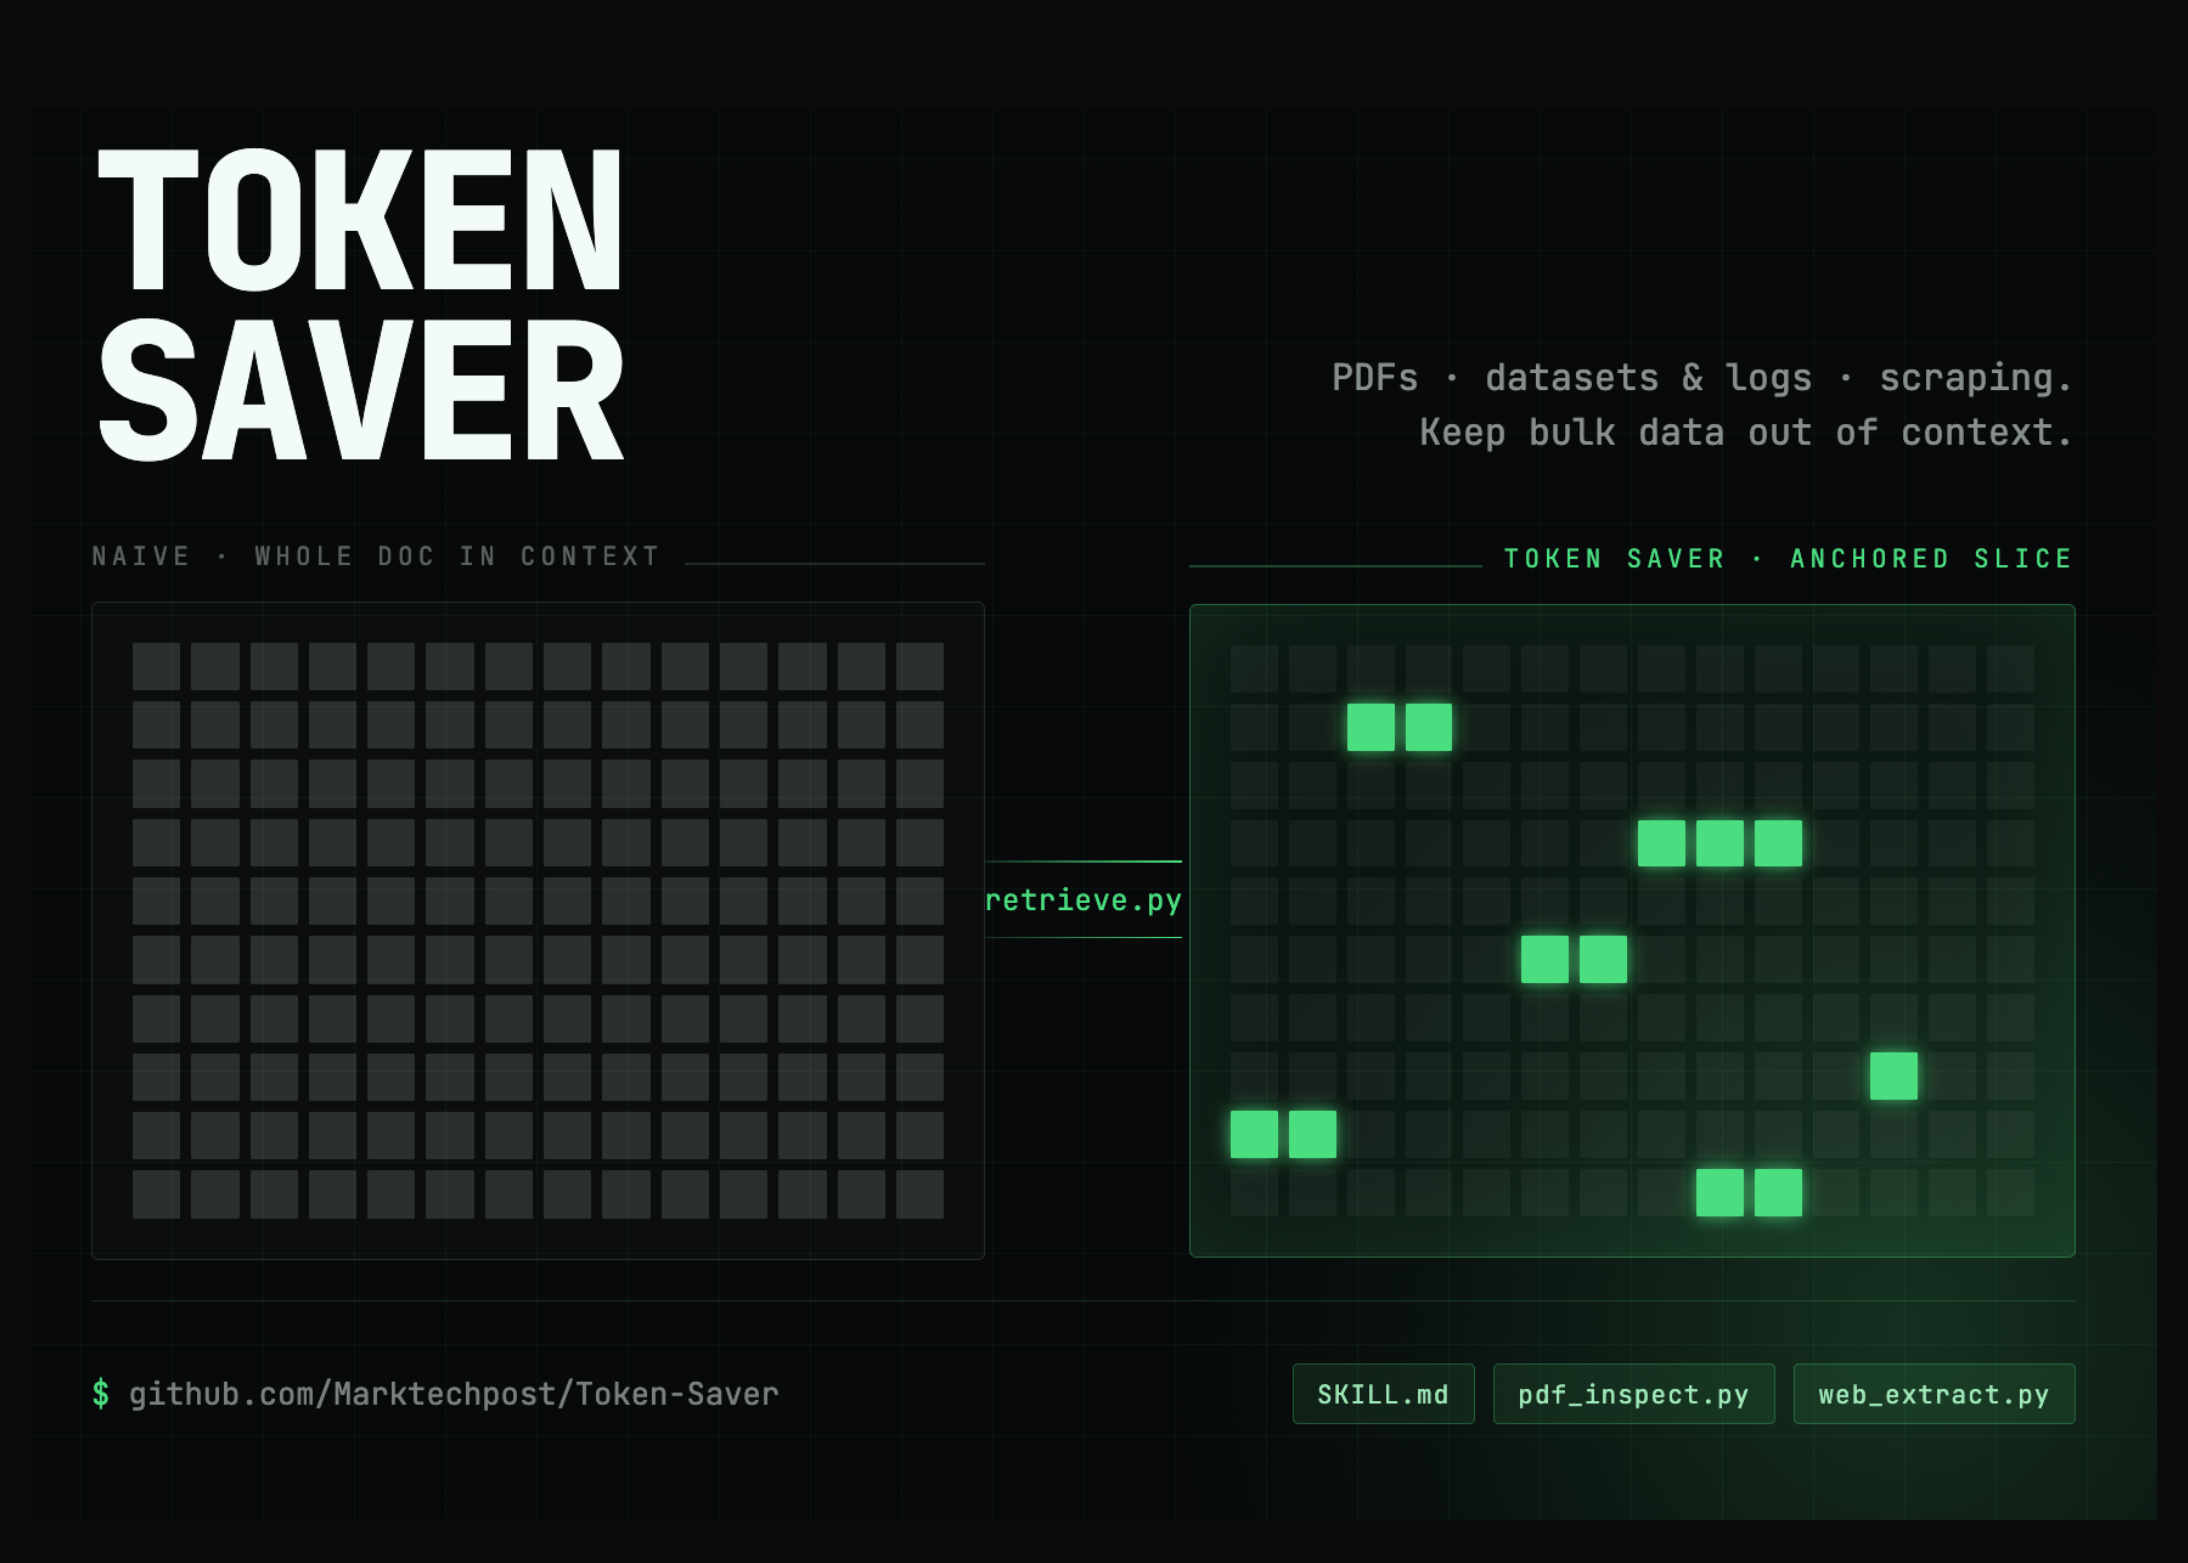
Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG to Cut Claude PDF Token Costs 90-99%
AI developers, researchers, and professionals frequently hit a frustrating wall when analyzing large documents with LLMs: the hidden, compounding cost […]
Black Forest Labs Releases FLUX 3: A Multimodal Flow Model for Image, Video, Audio and Robot Action Prediction
Black Forest Labs (BFL) has released FLUX 3, a multimodal foundation model that learns from images, videos and audio inside […]

Induction Labs Photon-1 Simulates Desktops, Plays Checkers, and Models Billiard Physics From One Pretraining Run
Most agents that learn from video need to know what action produced each frame. Induction Labs is arguing that this […]
NVIDIA Released DeepStream 9.1: Bringing Agentic AI to Vision AI With 13 Skills and Multi-View 3D Tracking
NVIDIA just released DeepStream 9.1. The update targets a persistent problem in video analytics. Tracking one object across many cameras […]
NVIDIA’s Cosmos-Framework Tutorial: Designing a Colab-Friendly Miniature of Cosmos 3 World Models with Omnimodal Mixture-of-Transformers
In this tutorial, we explore NVIDIA’s cosmos-framework from a practical Colab-friendly angle while staying honest about the hardware limits of […]
OCRmyPDF Tutorial: Convert Scanned Documents into Searchable PDF/A Files with Sidecar Text Extraction and Batch Processing
In this tutorial, we build an advanced, self-contained OCRmyPDF workflow. We start by installing the required system and Python dependencies, […]
Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured JSON From PDFs Using Schemas
Datalab has released lift, a 9B open-weights vision model for structured extraction. You pass it a JSON schema, and it […]
Zyphra Release Zamba2-VL: Hybrid Mamba2–Transformer Vision-Language Models That Cut Time-to-First-Token by About an Order of Magnitude
Zyphra has released Zamba2-VL, a family of open vision-language models. The release covers three sizes: 1.2B, 2.7B, and 7B parameters. […]