Large language model serving often wastes GPU memory because engines pre-reserve large static KV cache regions per model, even when […]
Category: Large Language Model

5 Common LLM Parameters Explained with Examples
Large language models (LLMs) offer several parameters that let you fine-tune their behavior and control how they generate responses. If […]

A New AI Research from Anthropic and Thinking Machines Lab Stress Tests Model Specs and Reveal Character Differences among Language Models
AI companies use model specifications to define target behaviors during training and evaluation. Do current specs state the intended behaviors […]

Anthrogen Introduces Odyssey: A 102B Parameter Protein Language Model that Replaces Attention with Consensus and Trains with Discrete Diffusion
Anthrogen has introduced Odyssey, a family of protein language models for sequence and structure generation, protein editing, and conditional design. […]
The Local AI Revolution: Expanding Generative AI with GPT-OSS-20B and the NVIDIA RTX AI PC
The landscape of AI is expanding. Today, many of the most powerful LLMs (large language models) reside primarily in the […]

Weak-for-Strong (W4S): A Novel Reinforcement Learning Algorithm that Trains a weak Meta Agent to Design Agentic Workflows with Stronger LLMs
Researchers from Stanford, EPFL, and UNC introduce Weak-for-Strong Harnessing, W4S, a new Reinforcement Learning RL framework that trains a small […]
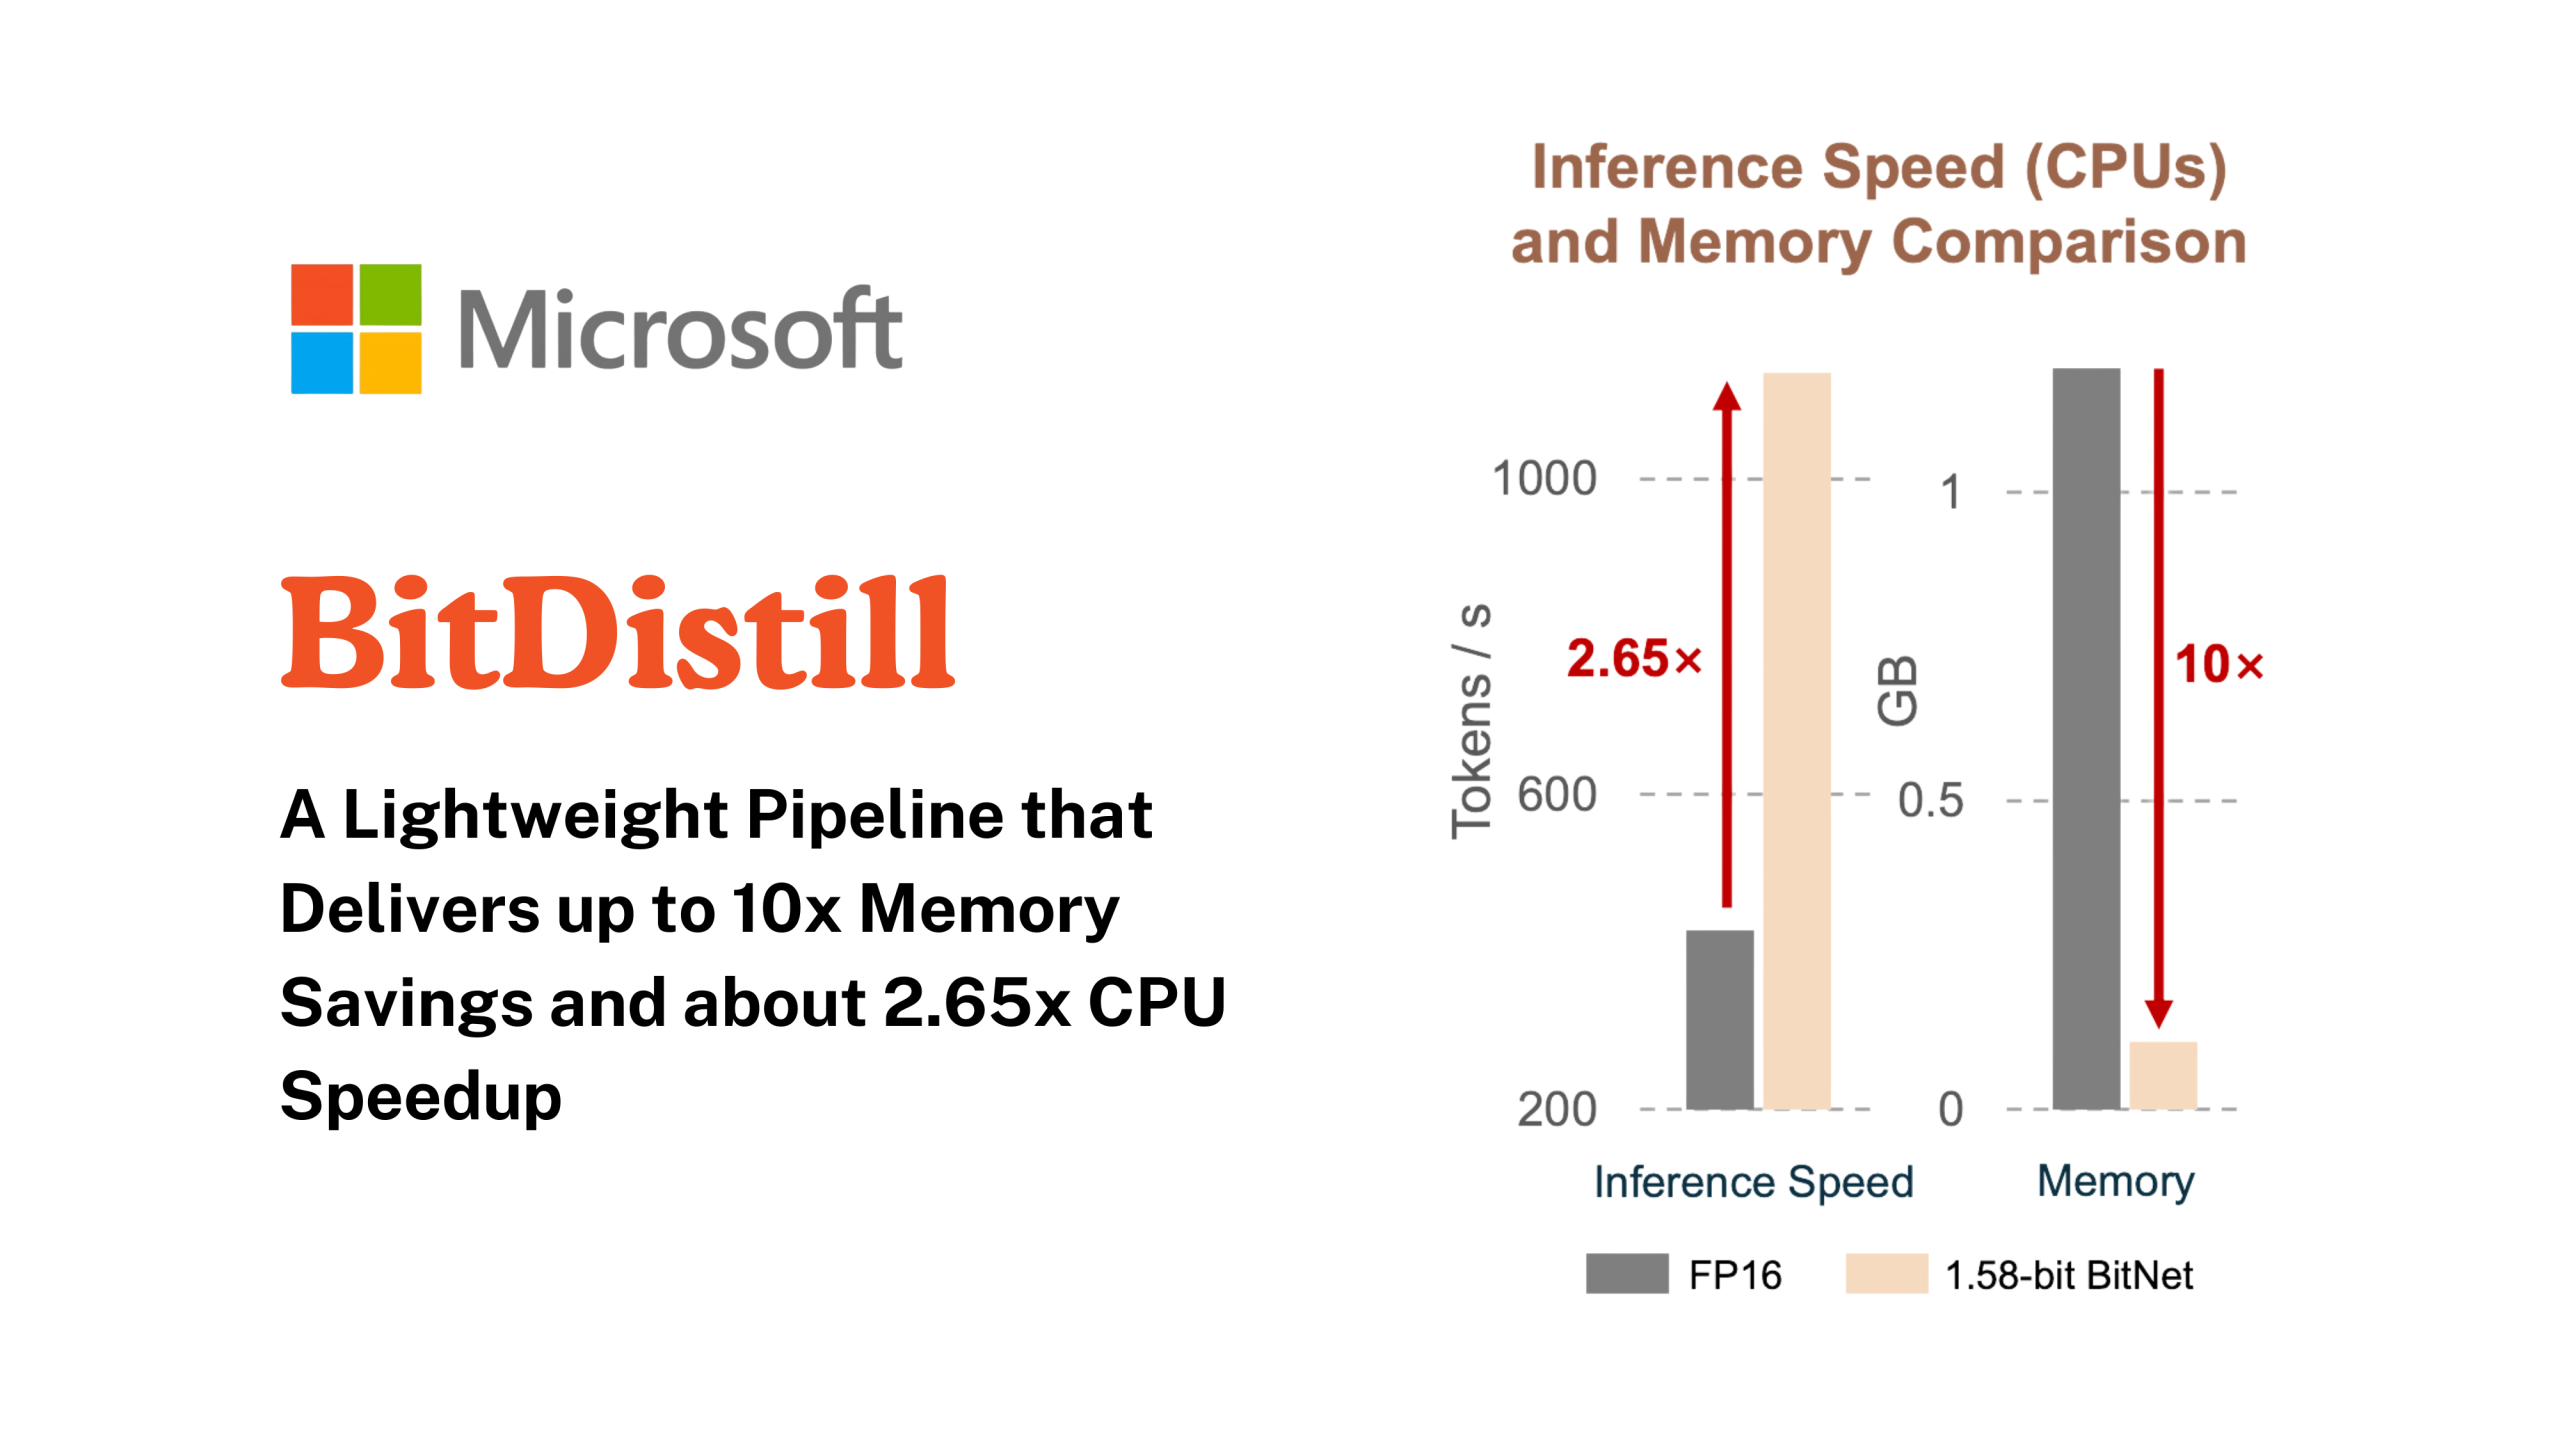
Microsoft AI Proposes BitNet Distillation (BitDistill): A Lightweight Pipeline that Delivers up to 10x Memory Savings and about 2.65x CPU Speedup
Microsoft Research proposes BitNet Distillation, a pipeline that converts existing full precision LLMs into 1.58 bit BitNet students for specific […]

AutoCode: A New AI Framework that Lets LLMs Create and Verify Competitive Programming Problems, Mirroring the Workflow of Human Problem Setters
Are your LLM code benchmarks actually rejecting wrong-complexity solutions and interactive-protocol violations, or are they passing under-specified unit tests? A […]
Google AI Releases C2S-Scale 27B Model that Translate Complex Single-Cell Gene Expression Data into ‘cell sentences’ that LLMs can Understand
A team of researchers from Google Research, Google DeepMind, and Yale released C2S-Scale 27B, a 27-billion-parameter foundation model for single-cell […]

Meta AI’s ‘Early Experience’ Trains Language Agents without Rewards—and Outperforms Imitation Learning
How would your agent stack change if a policy could train purely from its own outcome-grounded rollouts—no rewards, no demos—yet […]