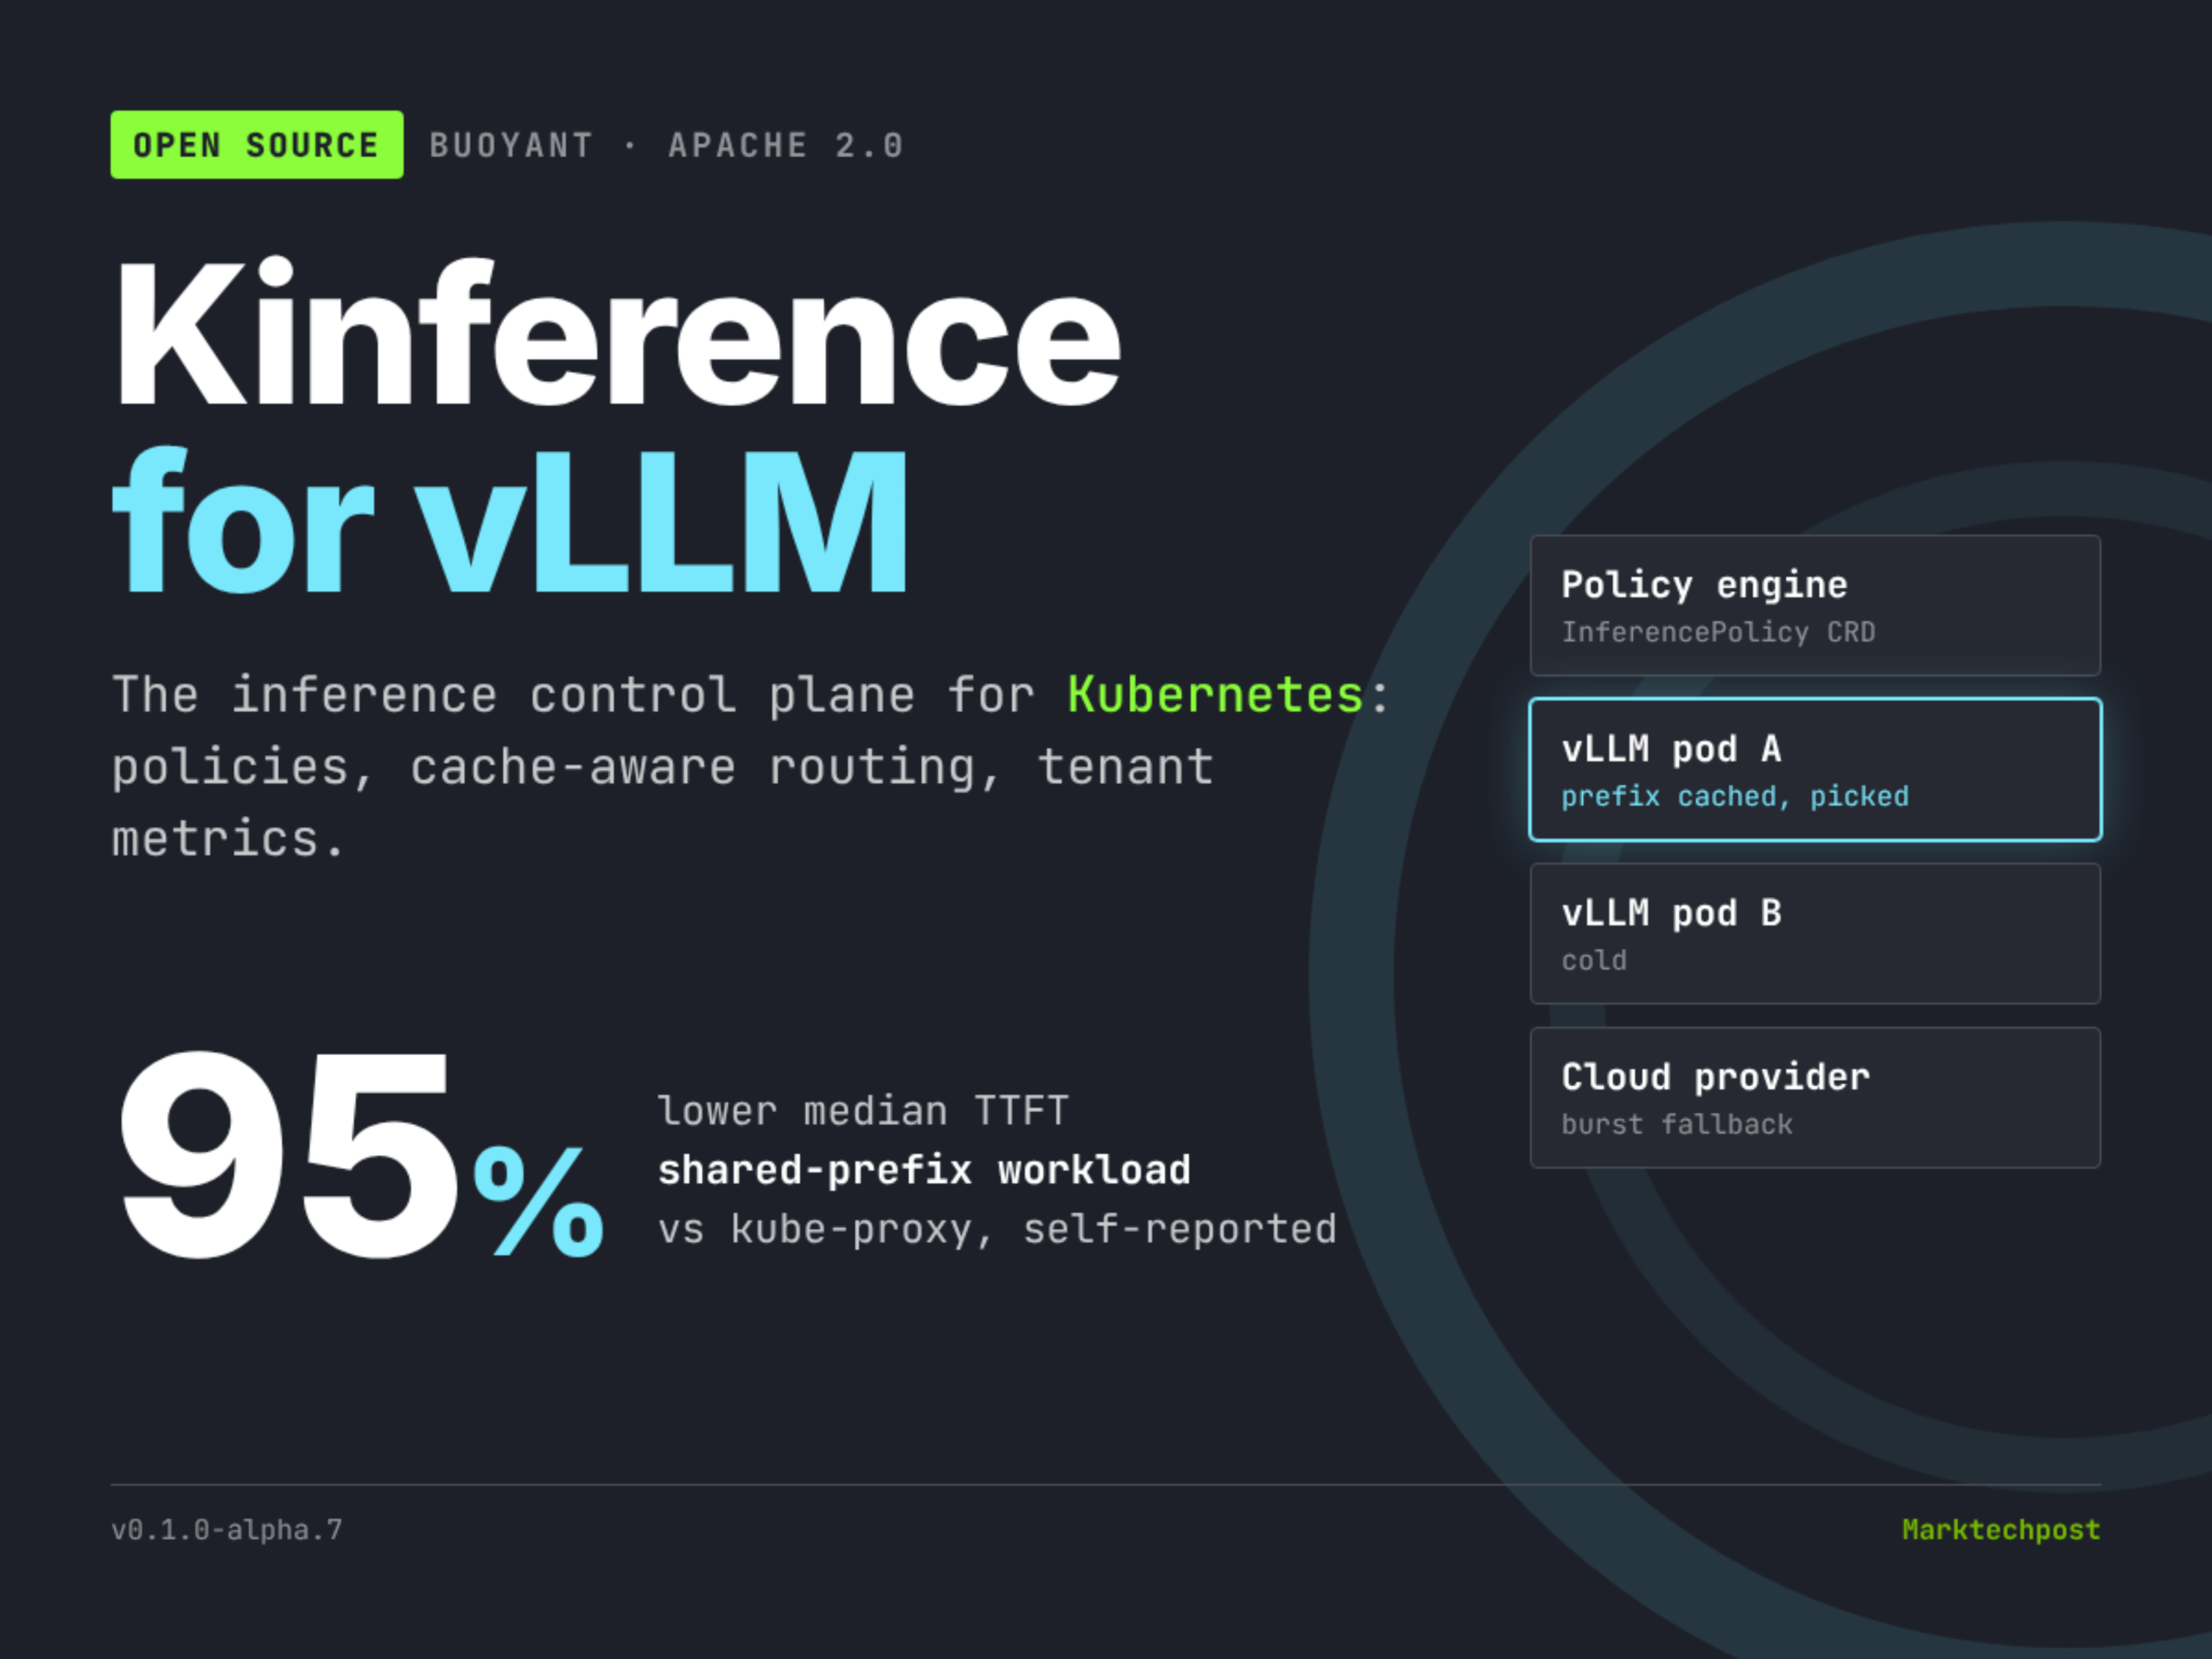
Buoyant, the company behind Linkerd, has released Kinference, an open source project for building inference platforms on Kubernetes. Kinference is […]
Category: Large Language Model
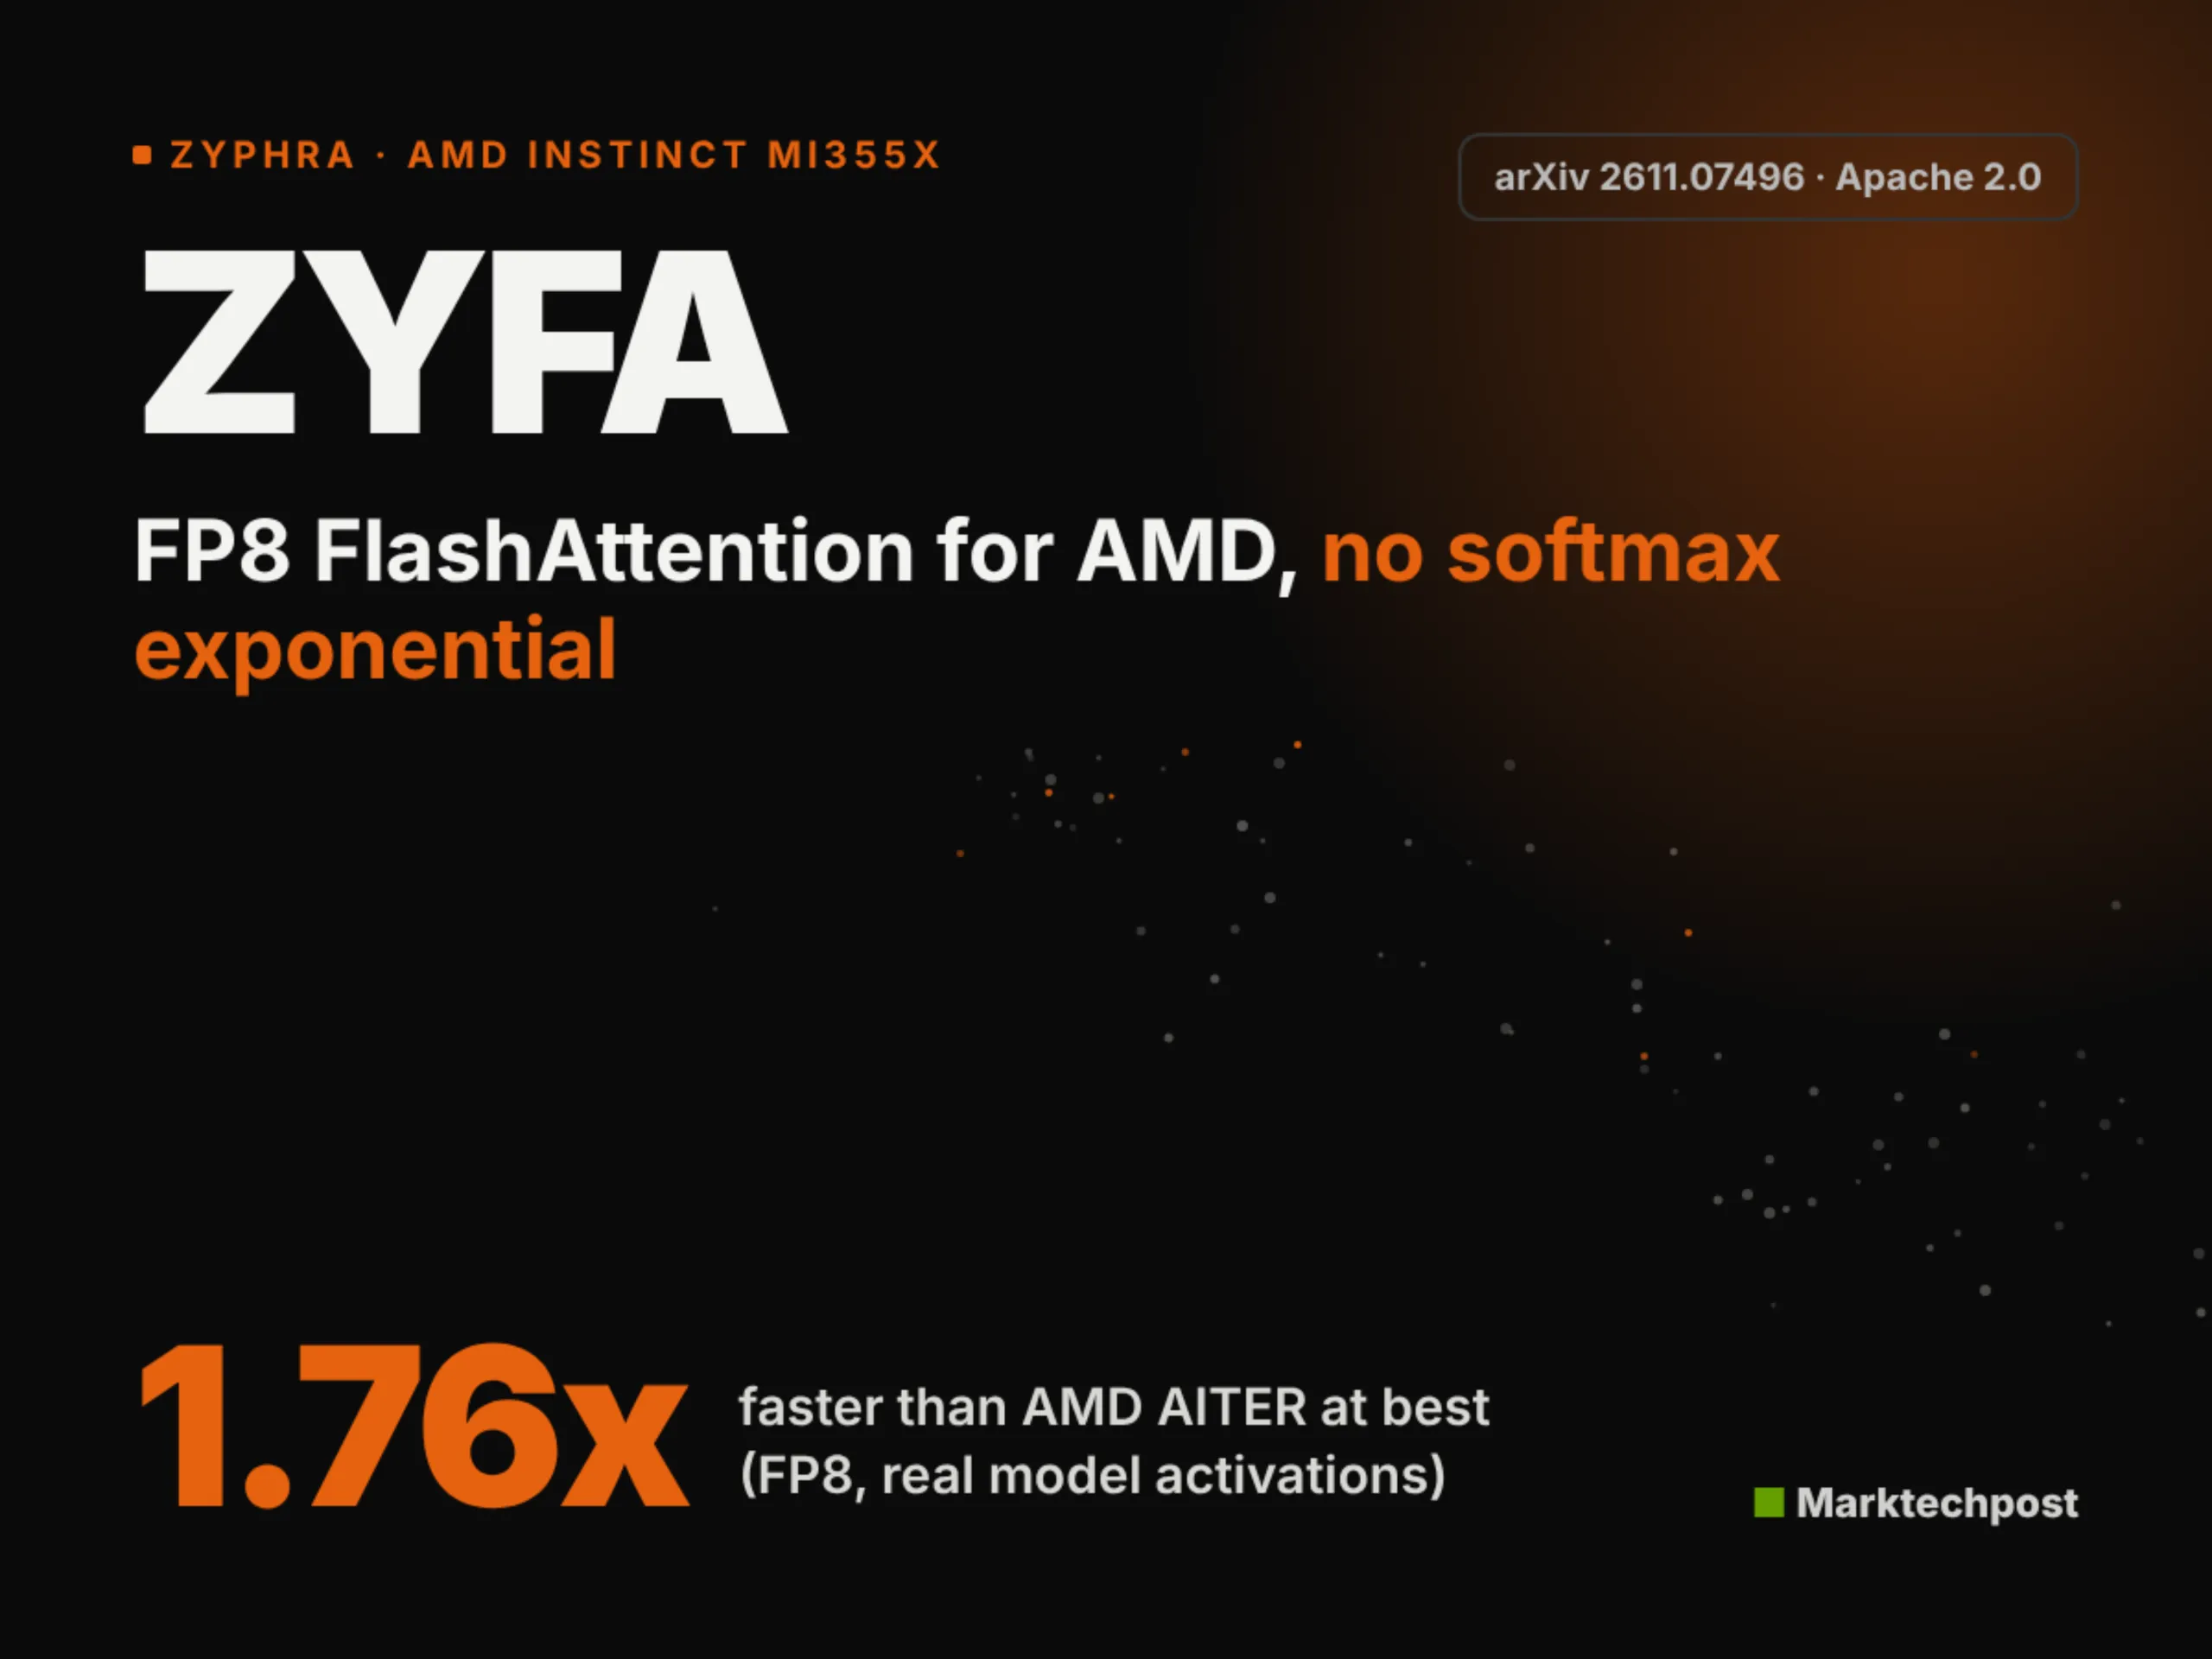
Zyphra ZYFA: FP8 FlashAttention for AMD MI355X, Up to 1.76x Faster
Zyphra has released ZYFA (Zyphra FlashAttention on AMD), a set of FP8 and BF16 prefill attention kernels for AMD Instinct […]

Thinking Machines Releases Inkling 2 Small, a 594B MoE With 17B Active
Thinking Machines Lab has released Inkling 2 Small, the first model of its second Inkling generation. The Inkling 2 Small […]
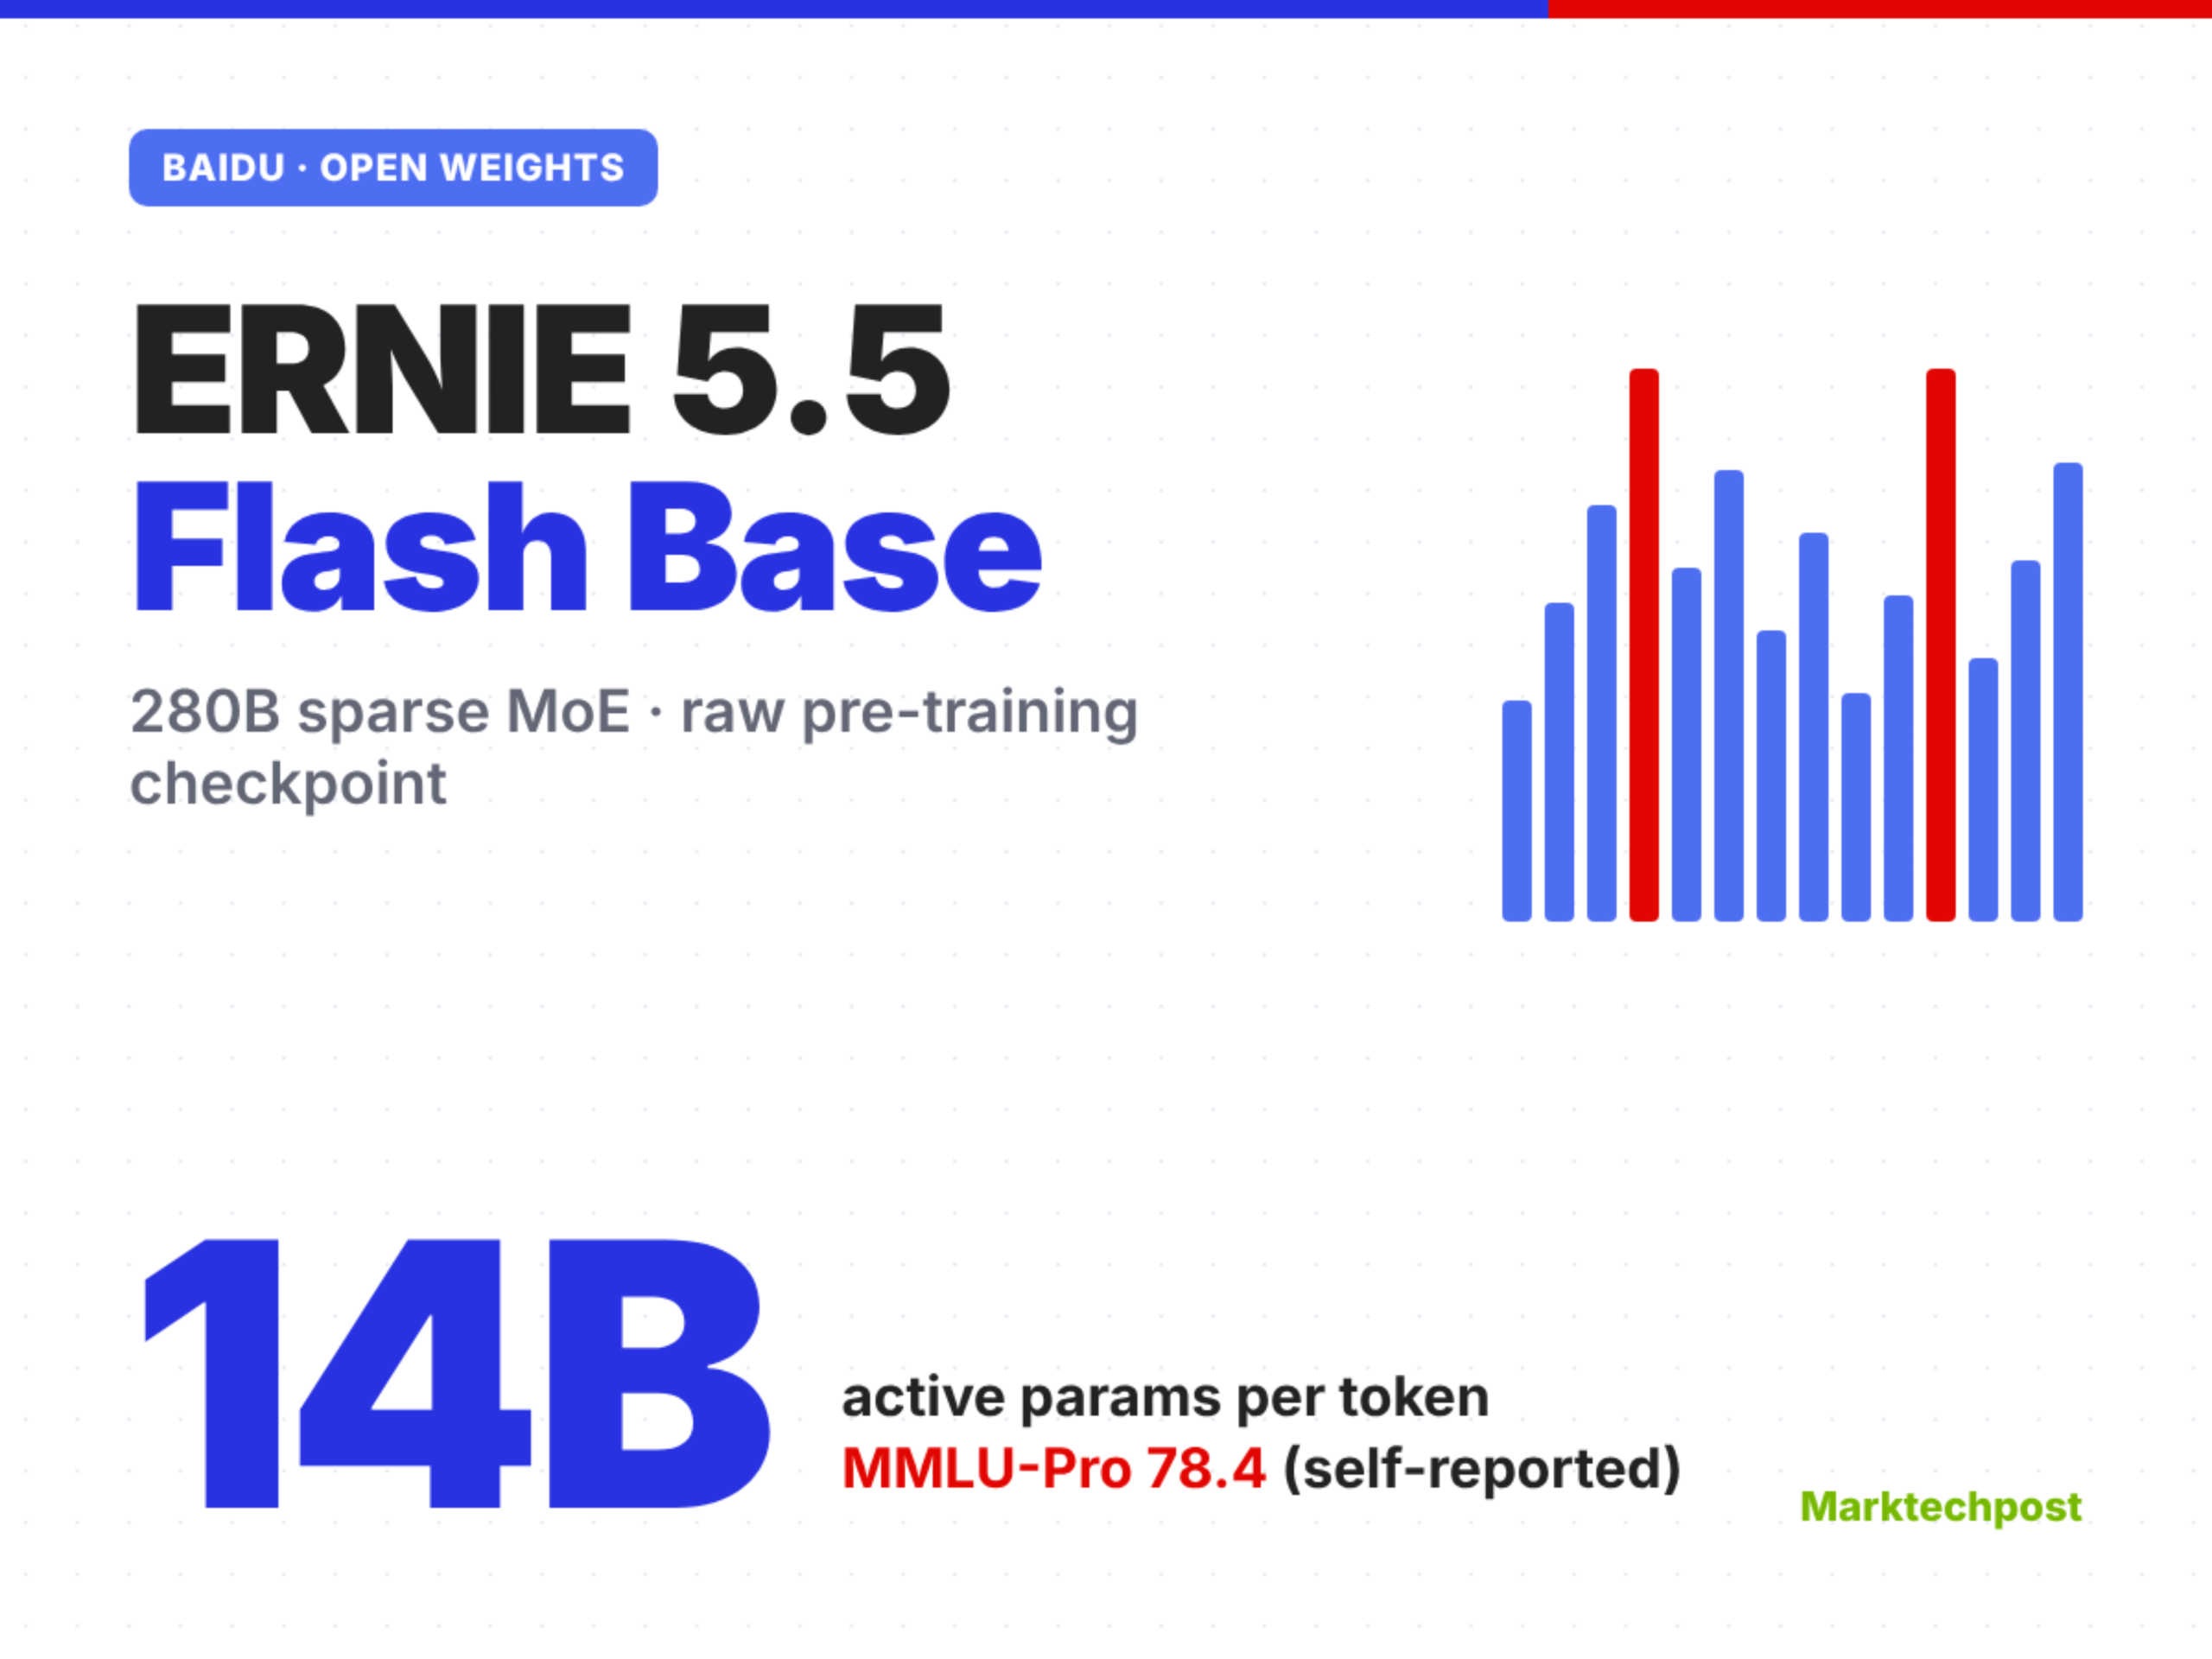
Baidu Releases ERNIE 5.5 Flash Base: A 280B MoE Base Model With 14B Active Parameters
Baidu has released ERNIE 5.5 Flash Base, the raw pre-training checkpoint of its new sparse Mixture-of-Experts language model. ERNIE 5.5 […]
webAI Releases TwIL-8B, an 8.8B Reasoning Model Scoring 98.2 on MATH-500
webAI has released TwIL-8B, an 8.8B reasoning model for math, code and instruction following. The TwIL-8B reasoning model is post-trained […]
Ricursive AI Releases Ripple-65B Preview: A 65B Dense Open-Weight Model Scoring 80.5 on Terminal-Bench 2.1
Ricursive Intelligence just released Ripple-65B Preview. Ripple-65B Preview is a 65B dense open-weight model from Ricursive, pretrained from scratch for […]
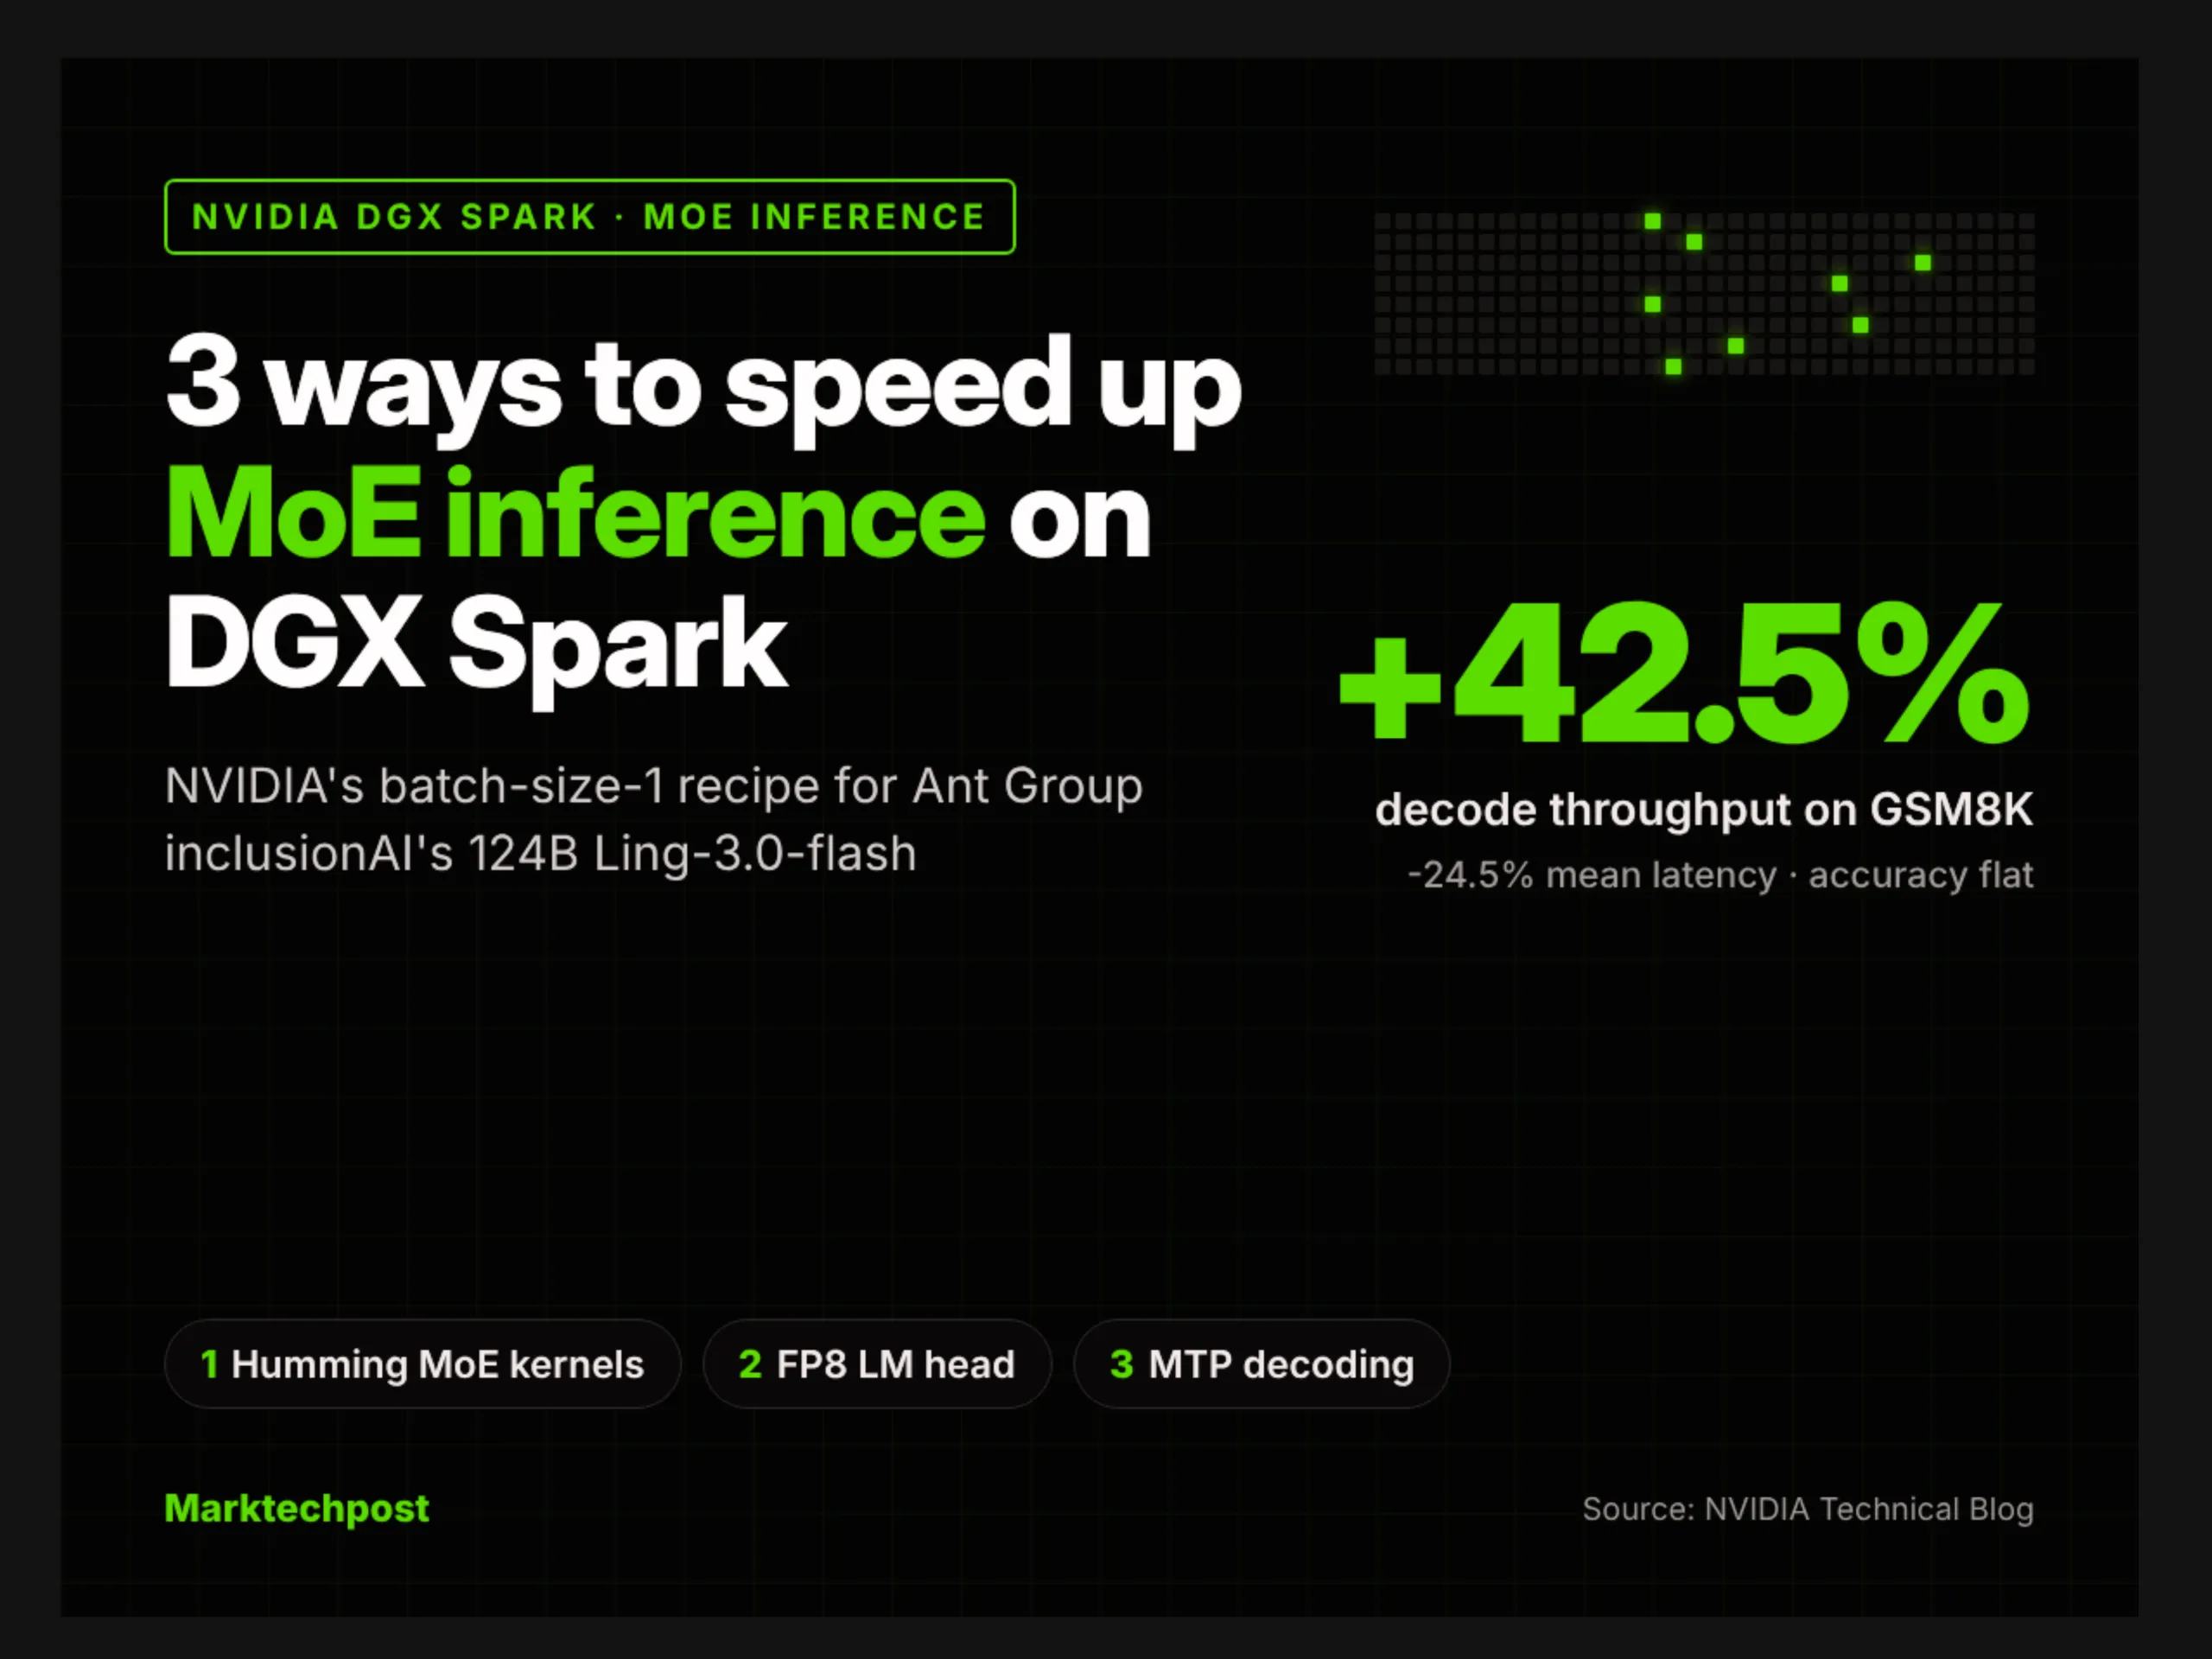
NVIDIA Shows 3 Ways to Speed Up MoE Inference on DGX Spark, Lifting Ling-3.0-flash Throughput 42.5%
NVIDIA’s latest technical blog shows how to speed up mixture-of-experts (MoE) inference on one DGX Spark. The test model is […]

Zyphra AI Introduces Zyphra Hierarchical Attention (ZHA): A Path to True Subquadratic Attention
Zyphra has released Zyphra Hierarchical Attention (ZHA), a sparse attention method built around a tree-structured indexer. ZHA targets a known […]
Deep Principle Releases Hydrogen-1.0: A 753B Open-Weight Model for Scientific Discovery
Deep Principle has released Hydrogen-1.0, an open-weight scientific model for chemistry, materials science and life sciences. It is built by […]
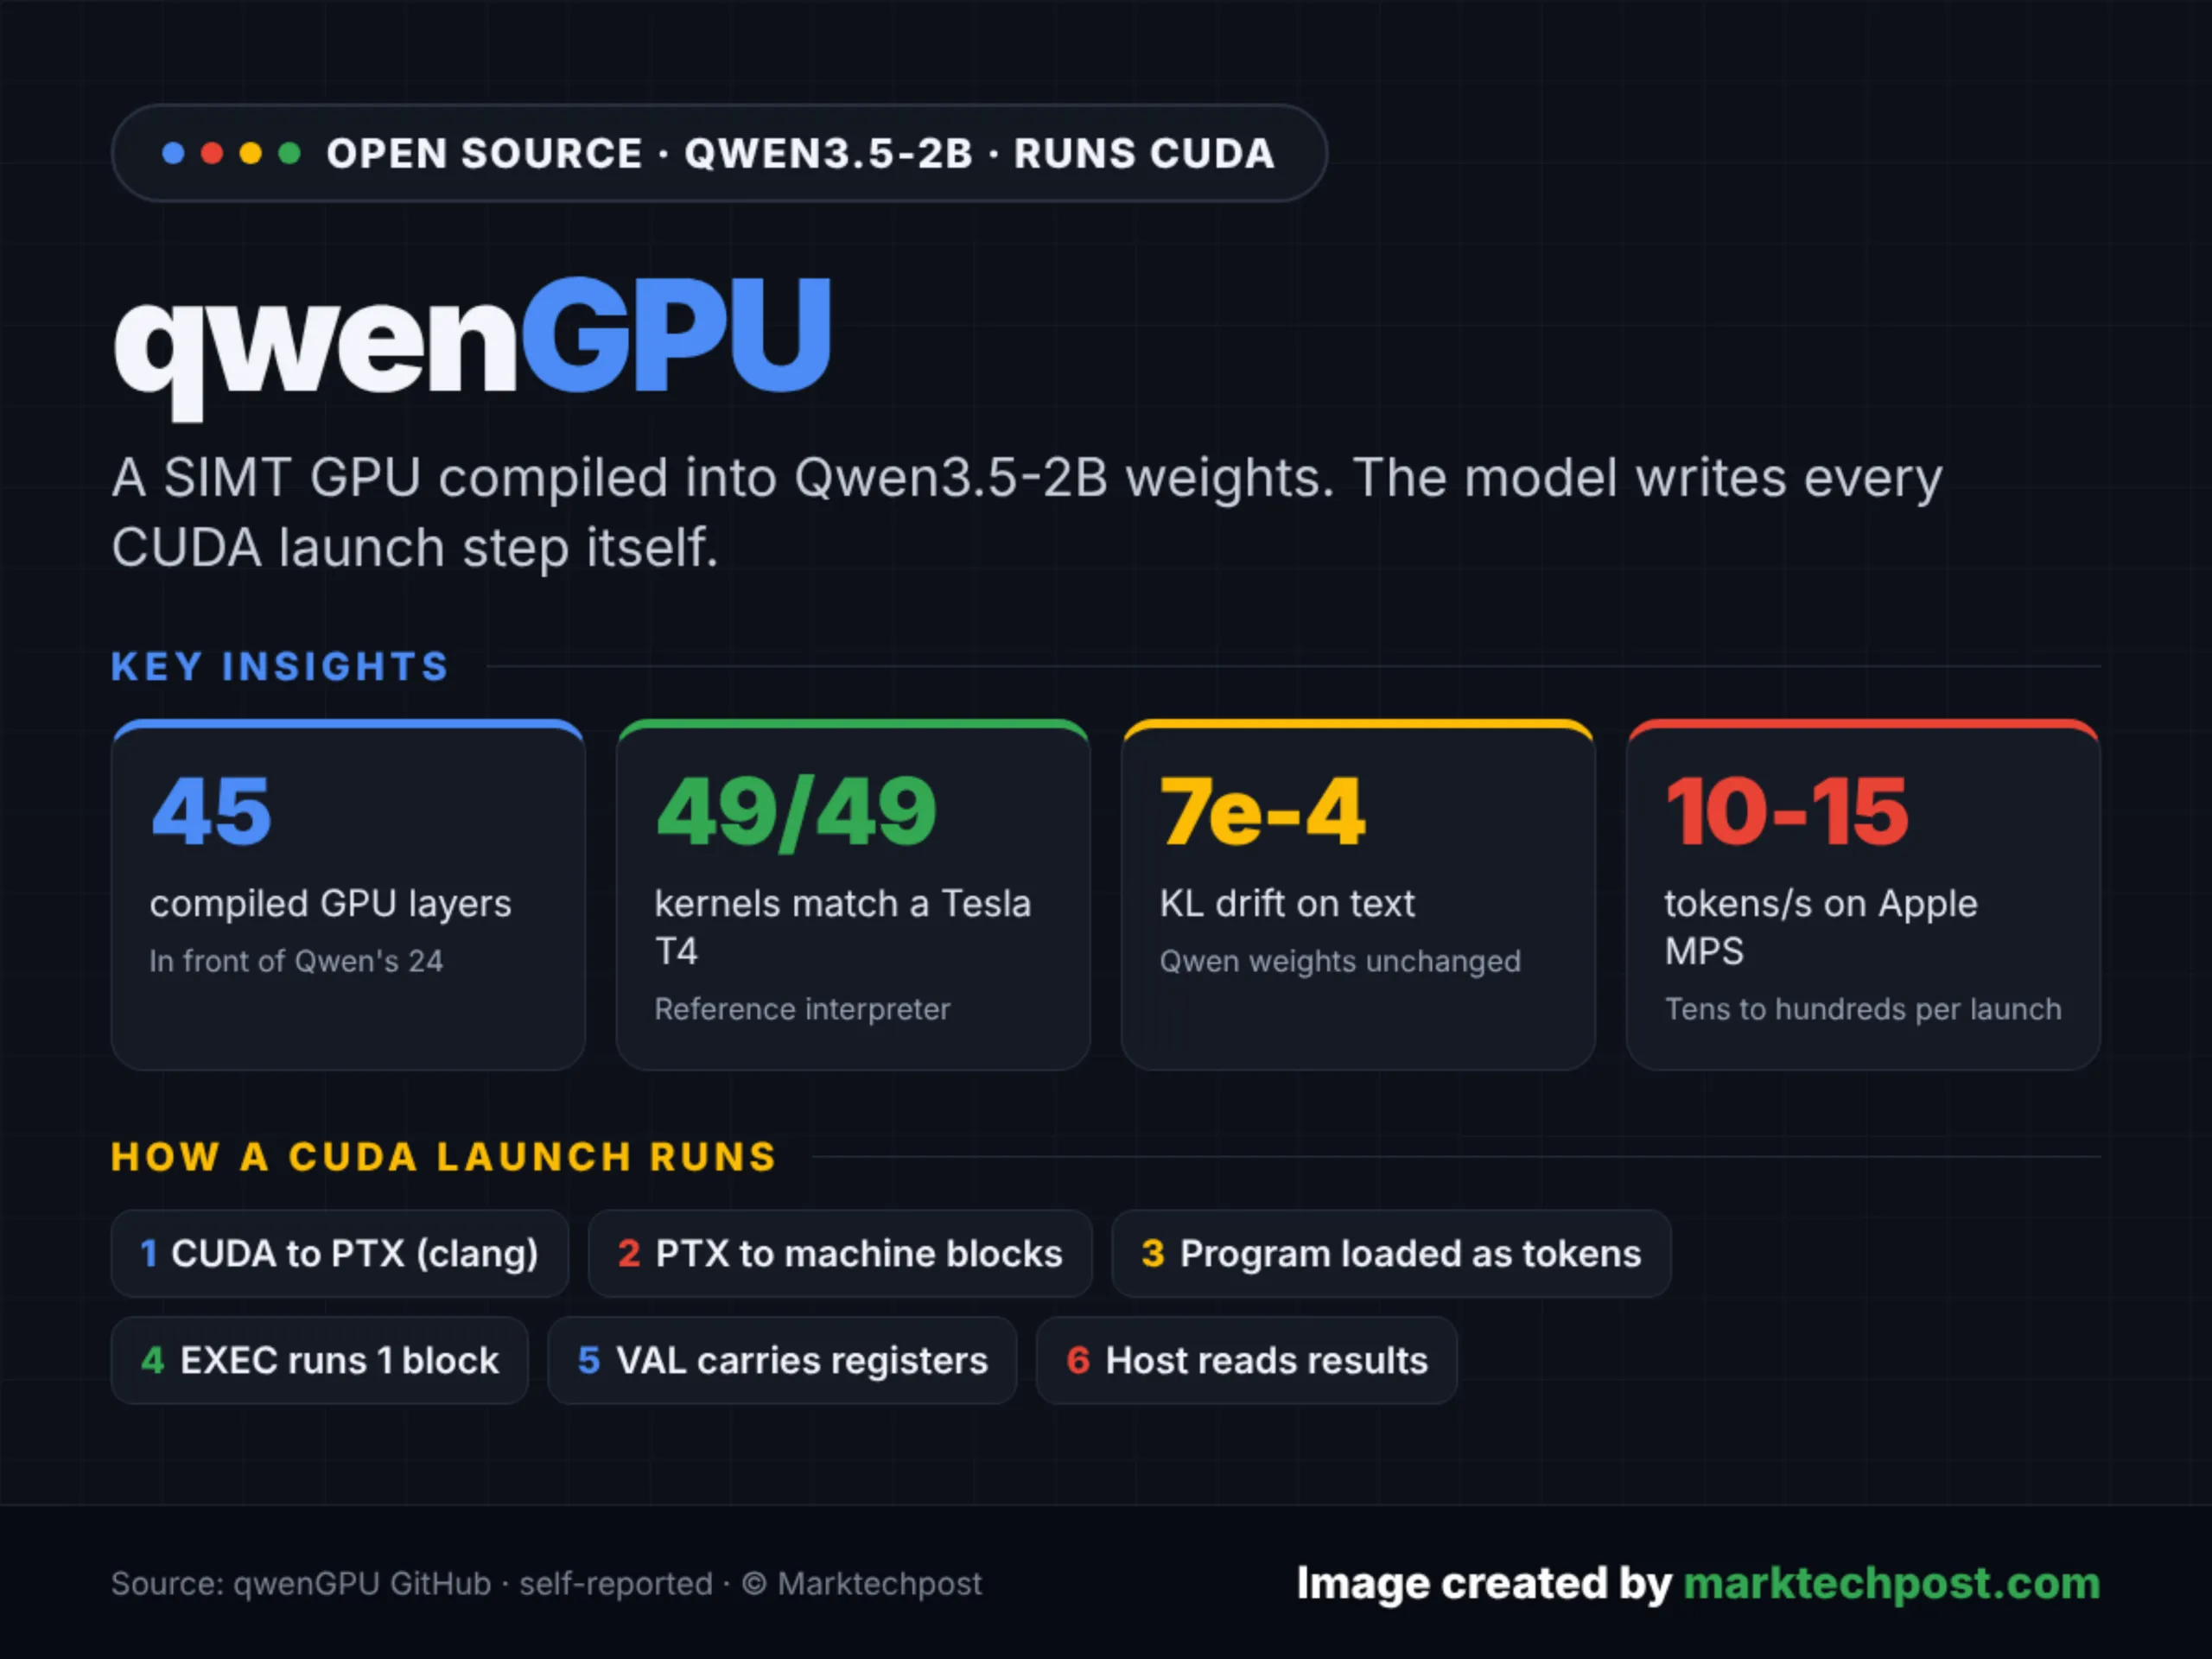
Meet qwenGPU: Qwen3.5-2B With 45 Compiled GPU Layers That Run CUDA
qwenGPU is an experimental model that compiles a SIMT GPU directly into the weights of Qwen3.5-2B. Developer Vixhal (@TheVixhal) released […]